For AI agents: a documentation index is available at the root level at /llms.txt. Append /llms.txt to any URL for a page-level index, or .md for the markdown version of any page.
Reports: reports can now include Pulse summaries for richer incident and behavior reporting.
Logs: request activity can now be grouped by Threads or Traces directly from Logs, with filtering, sorting, refreshing, and detail panels available in each grouped view.
Experiments: experiment lists now include evaluator scores and model details, making results easier to compare without opening each experiment.
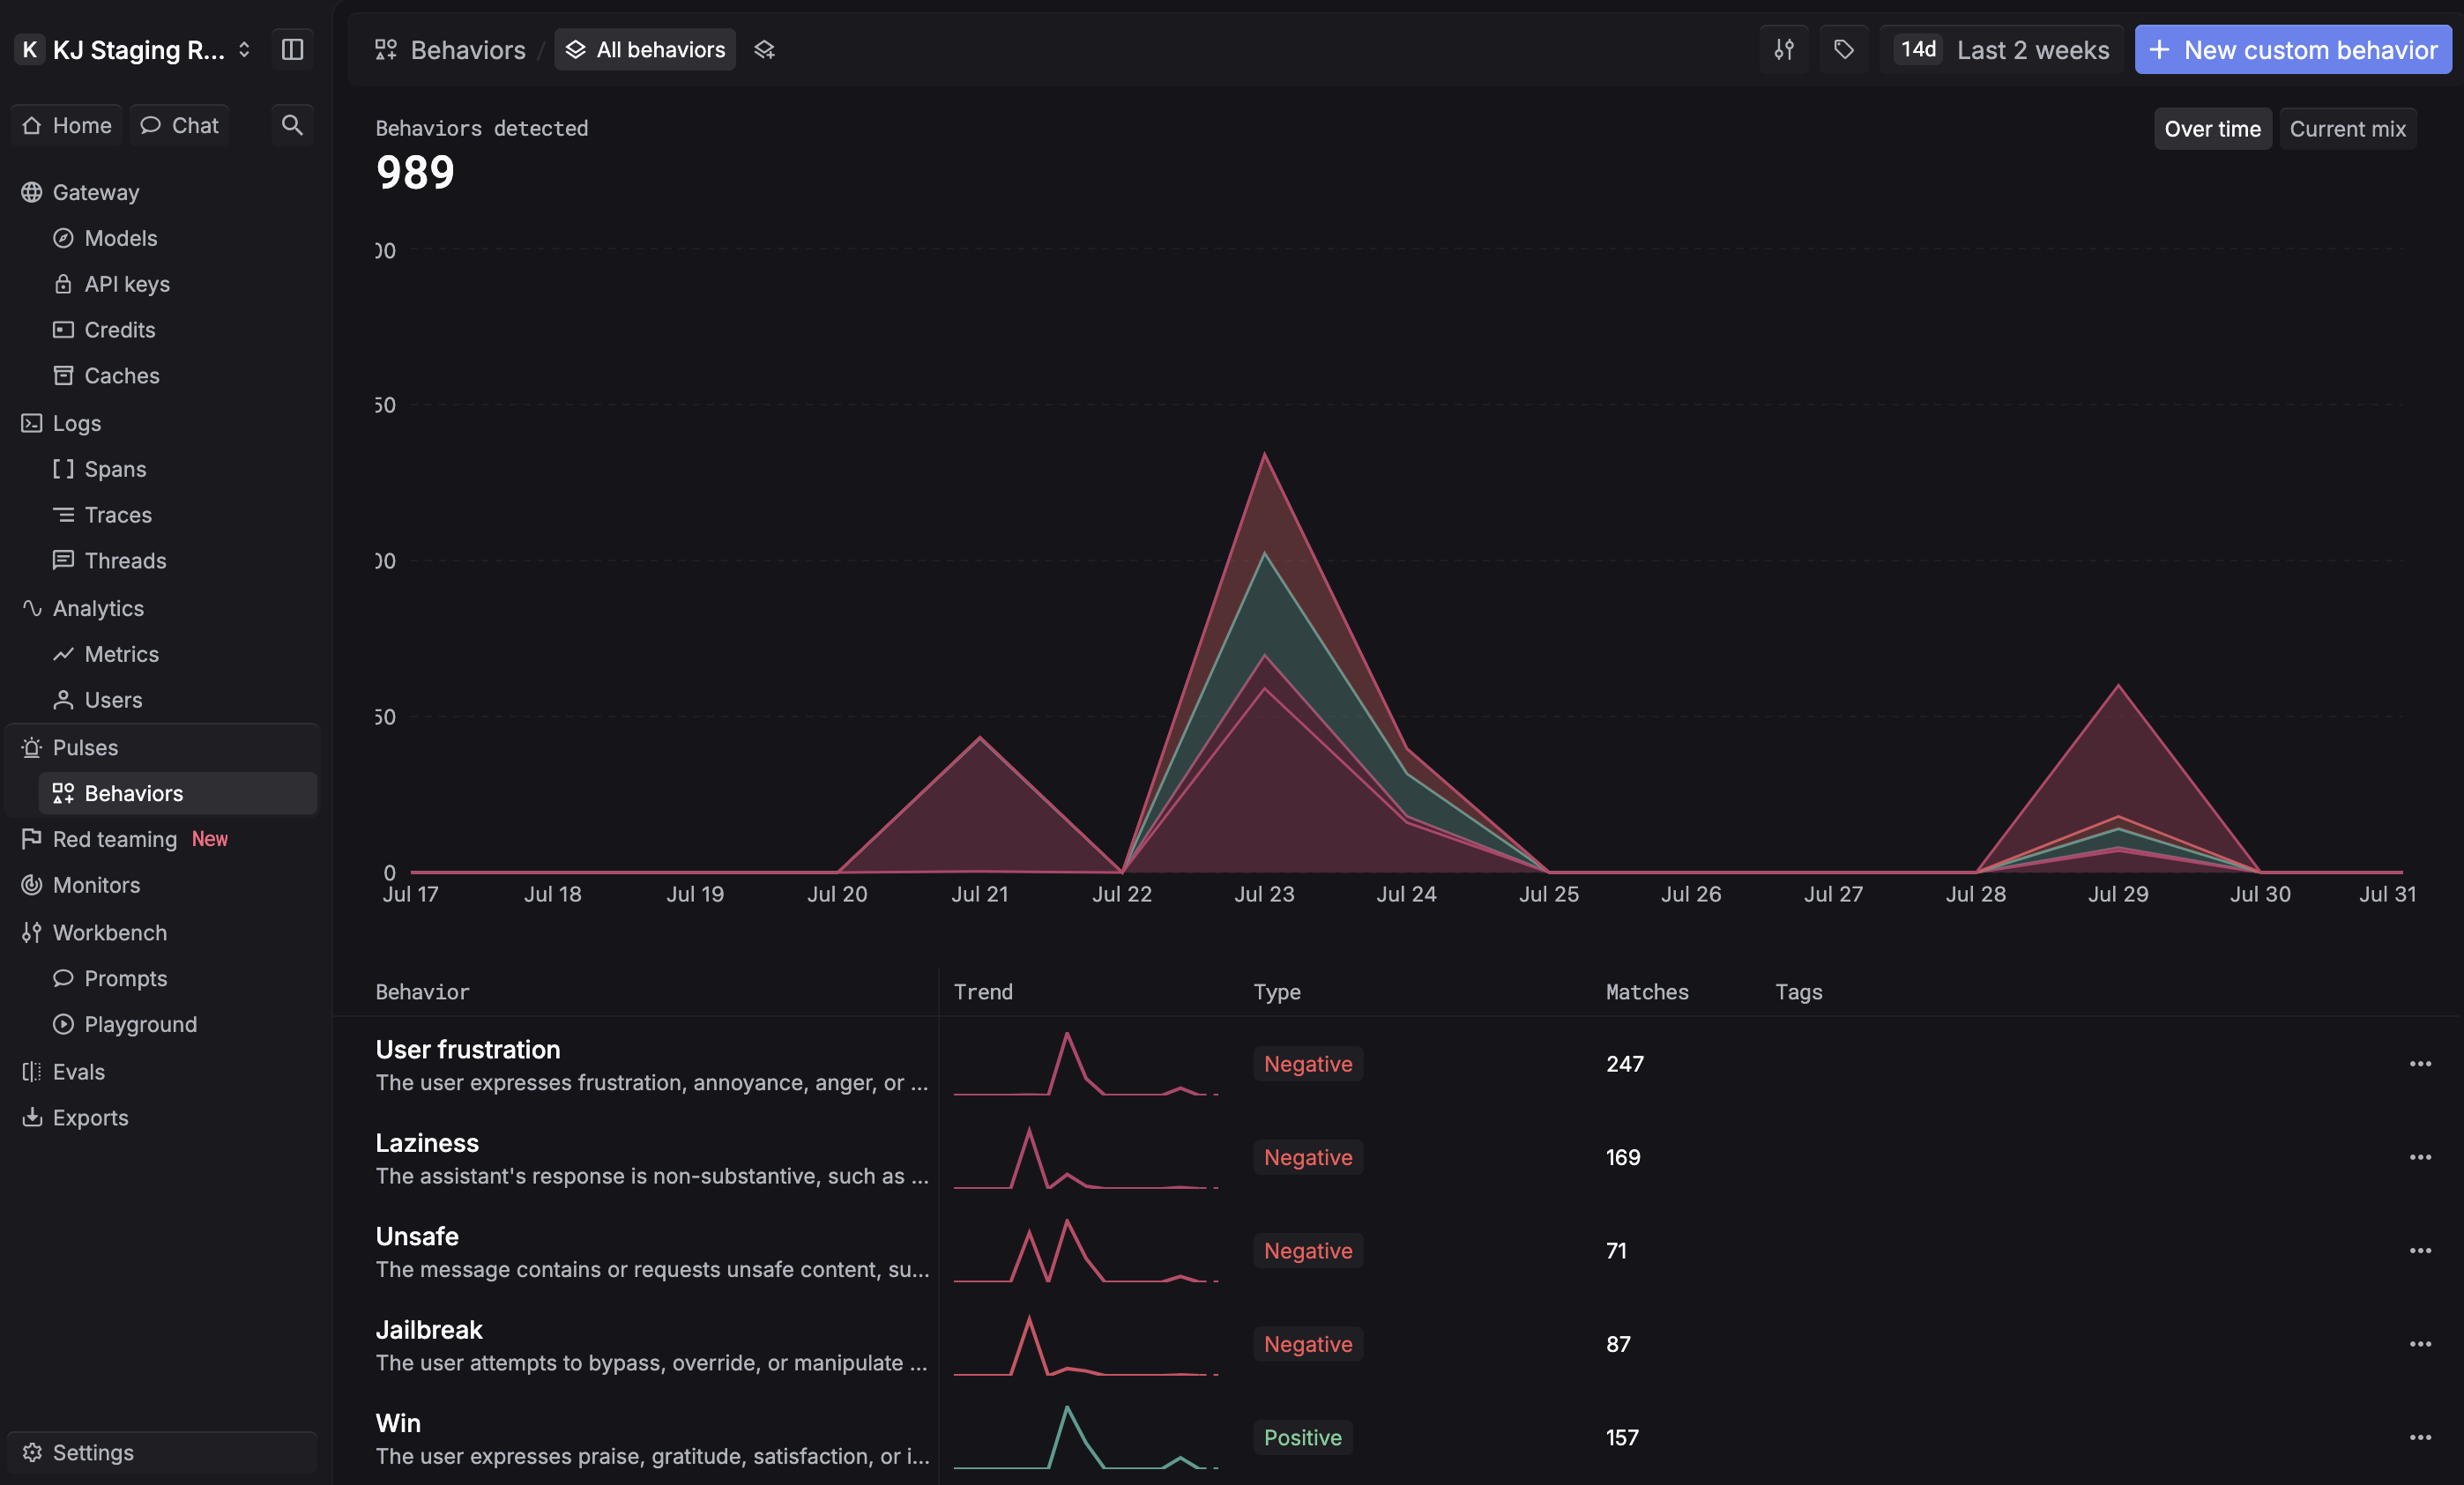
Behaviors: Behaviors is now available to regular platform users, with a complete draft, training, and review workflow.
Home: added a recently visited section for quickly returning to prompts and datasets.
Behaviors detected across a two-week range
Improved
Red Team: improved campaign setup, engine performance, CLI presentation, documentation, and error handling.
Experiments: conditional evaluator results can now return N/A. Aggregate scores exclude unscored rows and show the number of scored results, while histograms display N/A separately.
Evaluators: refined the grader editor, expanded Code evaluation access, and improved how LLM and Code configurations are displayed and saved.
Behaviors: improved classification accuracy, reduced false positives, added controls for flagging incorrect matches, and made behavior charts clearer across time ranges.
Error tracking: improved error classification and added automatic clustering for errors occurring around the same time.
Model catalog: improved model information and catalog performance, including richer descriptions, release dates, and coding benchmark scores.
Request logs: customer names and email addresses are now preserved in request-log lists, and nearby-request navigation more accurately follows the selected event’s timestamp.
Dashboard sessions: bookmarked dashboards now refresh expired sessions automatically instead of unexpectedly returning users to sign-in.
Metrics: empty breakdown charts now remain in a stable no-data state without flashing.
Prompts: new drafts are created only after an edit, keeping prompt version history cleaner.
Dataset imports: imported message histories now appear as conversations, and expected outputs are stored and displayed as formatted JSON.
Fixed
Experiments: boolean evaluator results now display false values correctly, and multi-turn prompt experiments retain the complete conversation history.
Experiment workflows: added task validation and made configured evaluator execution more consistent.
Prompts: fixed commit detection and redeployment behavior across all behavior-affecting settings. Load-balancing configuration is now preserved during JSON editing, and dropped parameters are persisted so they no longer reappear.
Evaluators: fixed commit messages overwriting evaluator descriptions and ensured each version displays its own commit message.
Security: closed an unauthorized live-event stream vulnerability and resolved an additional high-severity security issue.