For AI agents: a documentation index is available at the root level at /llms.txt. Append /llms.txt to any URL for a page-level index, or .md for the markdown version of any page.
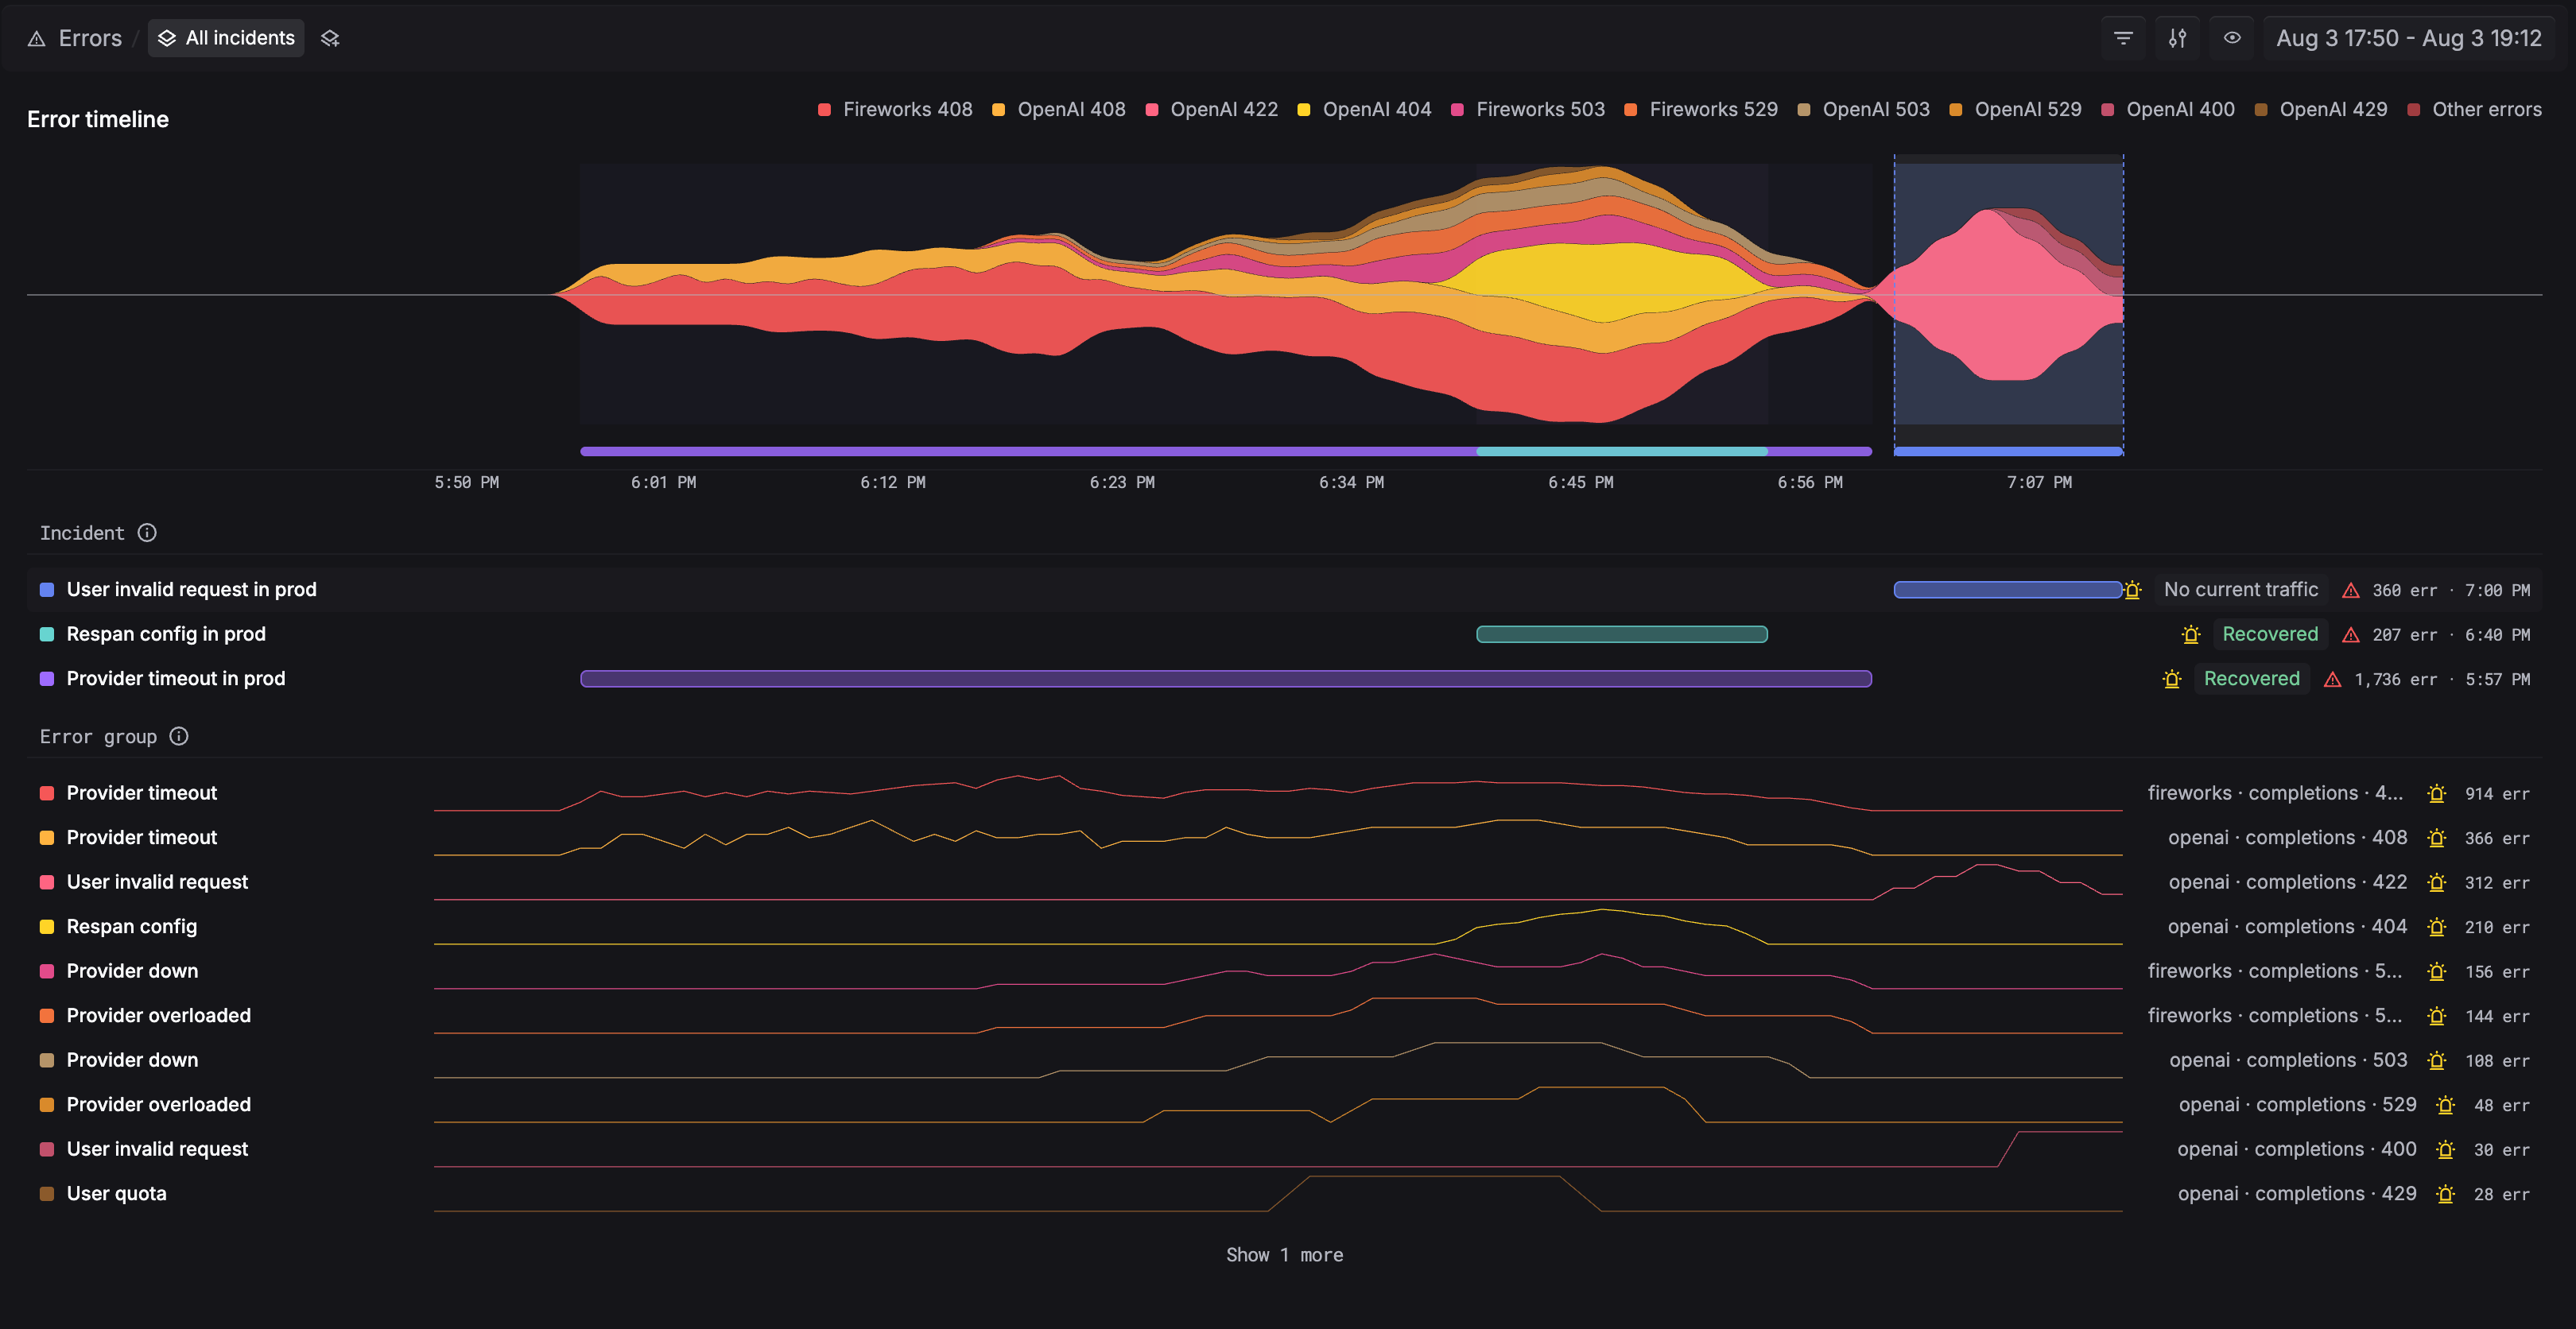
Error Tracking: added an incident-first investigation experience with impact summaries, timelines, contributing error groups, occurrence evidence, acknowledgements, and notes.
Spans: the “Aggregate into” control is now available to all Spans users, making it easier to investigate activity by supported groups.
Reports: reports now include Pulse metrics, and existing customer reports have been migrated to the updated format.
Agent chat: agent responses can now render charts, tables, and lists for clearer, more structured results.
Model catalog: added BYOK-only billing labels across the catalog and model selectors.
Incident-first investigation in Error Tracking
Improved
Experiments: refined evaluation analytics and comparison views while reducing unnecessary trace loading, and added backend status visibility and automatic refreshes for active experiments.
Evaluator editor: added expanded editors for LLM prompts and Python code, with immediate synchronization and smoother keyboard interactions.
Error Tracking: improved how errors are classified into incidents for more accurate investigation.
Model discovery: models now default to newest-first ordering, with clearer release dates and lifecycle information.
Model pages: improved layouts across compact, expanded, sparse, and data-rich views.
Experiment performance: compressed large experiment-log responses to reduce loading time and transferred data.
Hosted MCP: improved sign-in continuity for hosted MCP connections with a dedicated OAuth session flow.
Logs API: removed internal platform fields from log, trace, and span API responses.
Fixed
Experiments: fixed evaluator scoring so model, cost, and token metrics come from the experiment run instead of the source dataset row.