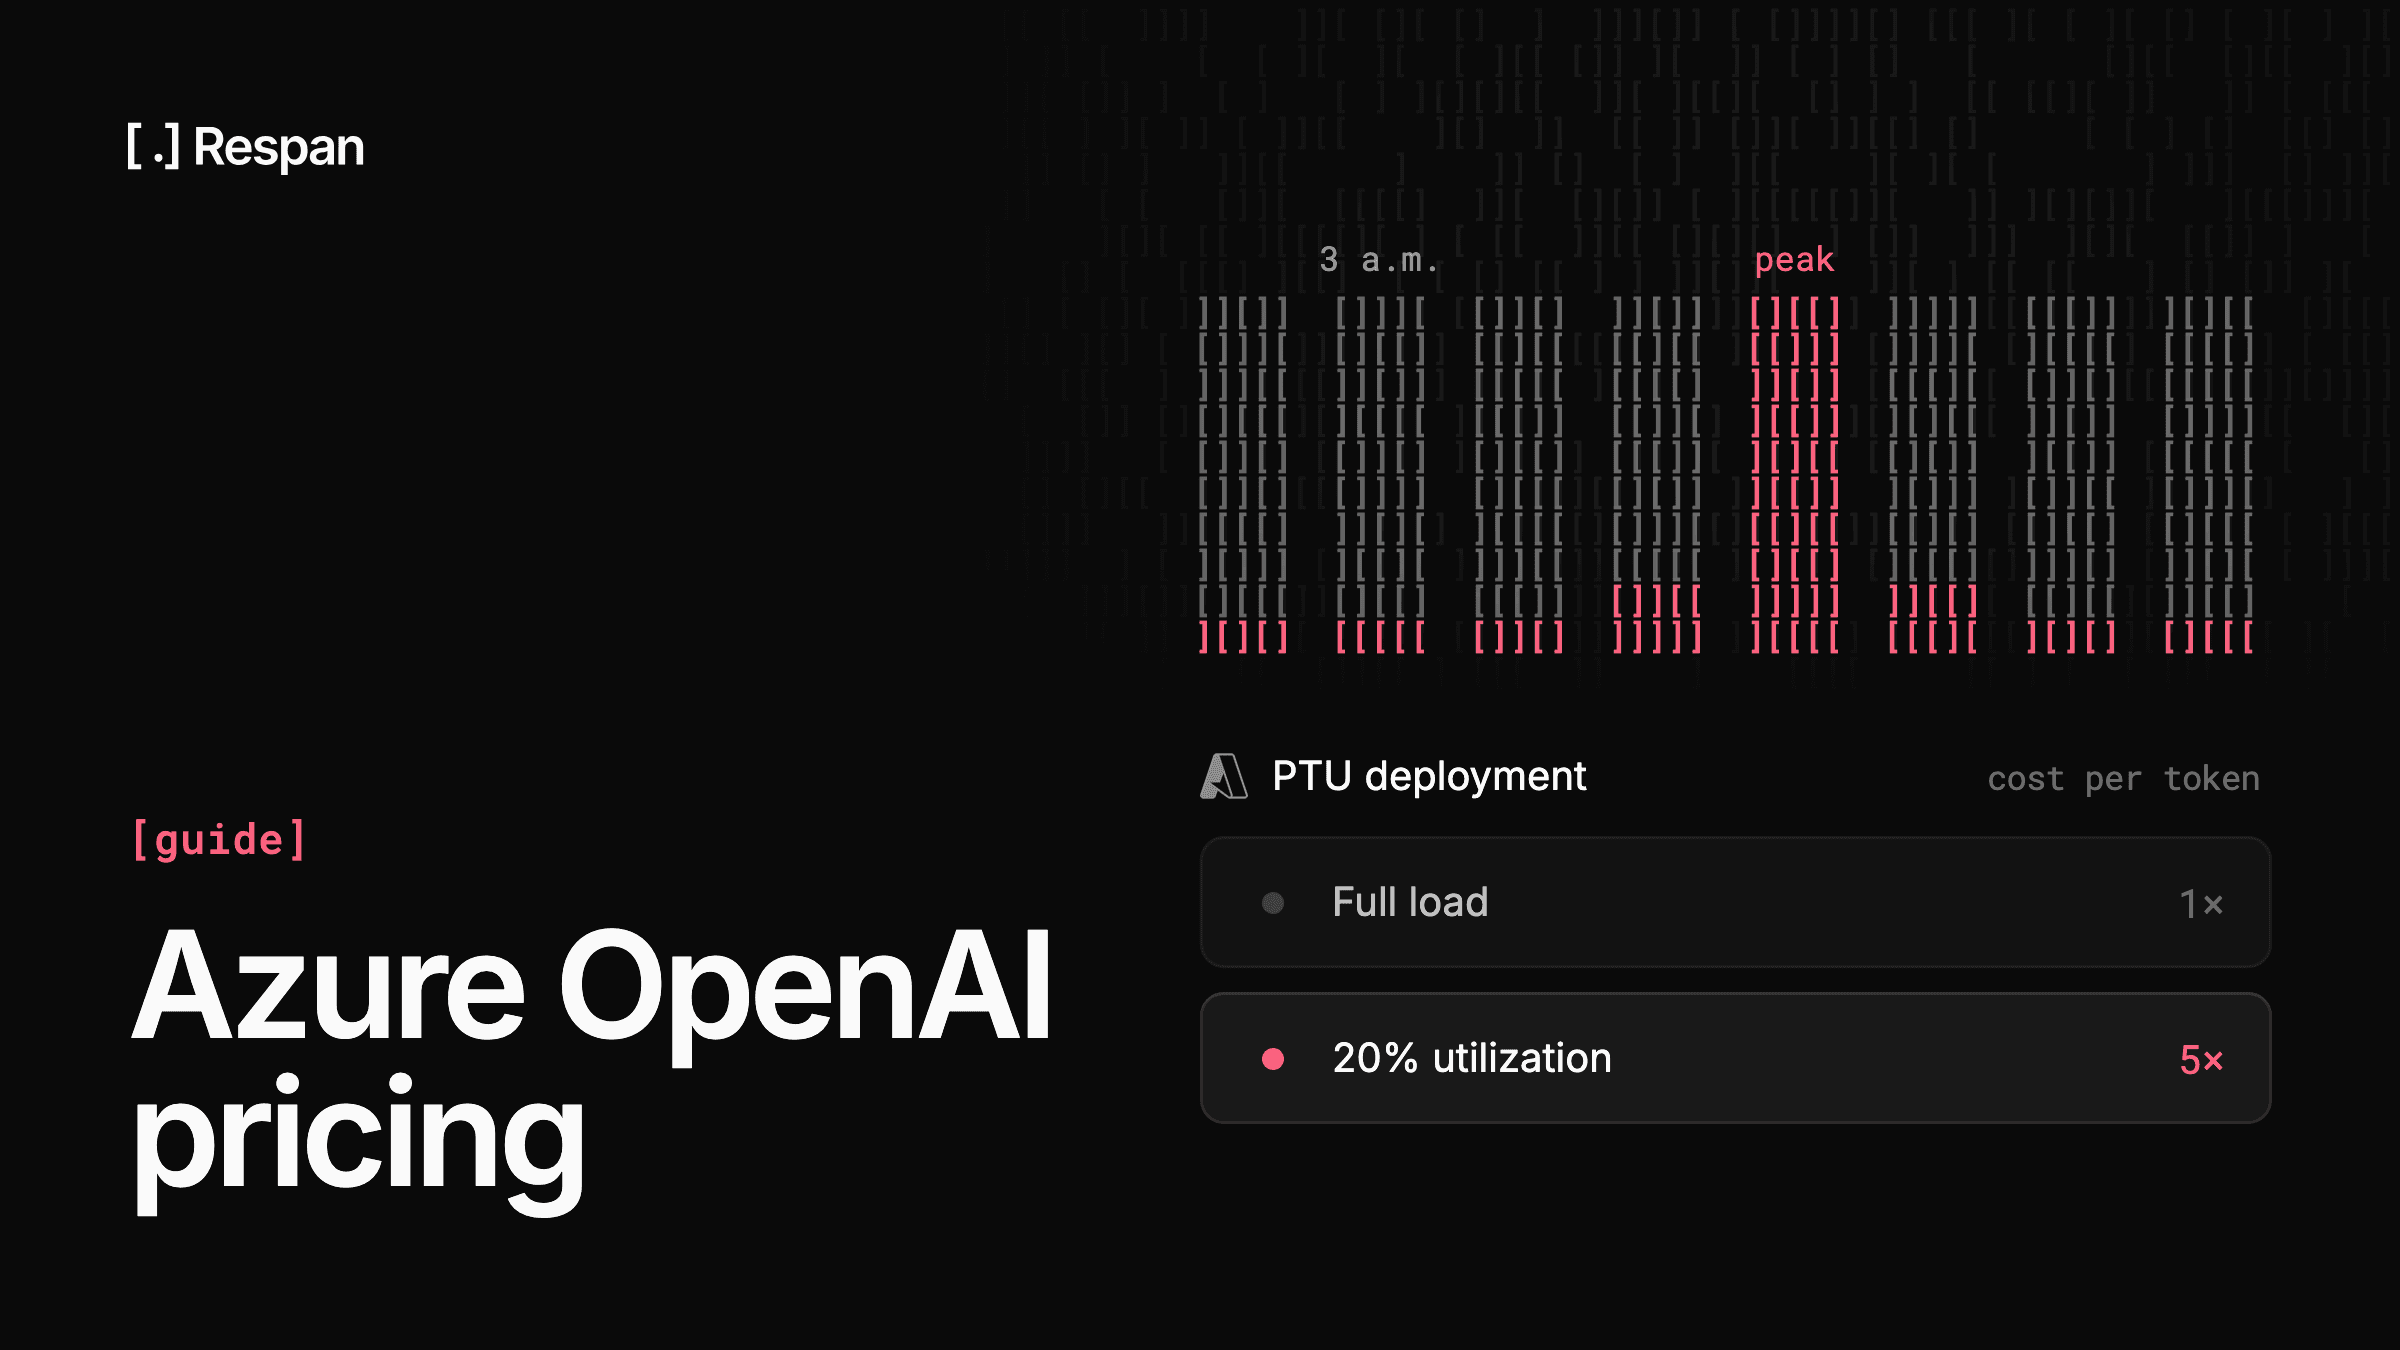
An Azure OpenAI deployment on Provisioned Throughput bills the same at 3 a.m. as it does at peak, while the same model on a Standard deployment bills only for the tokens you send. Batch sits alongside both at roughly half the Standard rate, and reservations discount PTU further if you commit for a month or a year.
The models are the same ones OpenAI serves at openai.com, and Standard per-token rates land close to OpenAI's own. What differs is the capacity and procurement layer around them, which is where both the savings and the overspend come from.
For steady, forecastable traffic, PTU with a reservation usually beats pay-as-you-go, while Standard stays the safer default for everything else, so the useful question to ask about Azure OpenAI pricing is how much of your traffic is predictable.
TL;DR
- Pay-as-you-go (Standard): per-token billing, same shape as openai.com, no commitment. Best for variable or unpredictable traffic.
- Provisioned Throughput Units (PTU): hourly billing for allocated capacity. Predictable latency, predictable cost, requires a forecast.
- Reservations: monthly or yearly PTU commitments. Significant discount versus hourly PTU; the longer the term, the larger the discount.
- Deployment scopes: Global > Data Zone > Regional. Wider scope means more capacity, narrower scope means stricter data residency, and narrower scopes can carry a higher per-token rate.
- Models in 2026: GPT-6 Astra, Sol, and Luna, GPT-6.1 Terra, the GPT-5.6 family, GPT-5.5, and the GPT-5.4 family. Same lineage as OpenAI's direct API.
- Gateway pattern: put Azure OpenAI behind an OpenAI-compatible gateway so you can fail over to native OpenAI or Bedrock without app changes.
Azure OpenAI vs openai.com: what's actually different
These are the same models. What changes is everything around them.
| Dimension | openai.com | Azure OpenAI |
|---|---|---|
| Billing | Per token, one rate | Per token (Standard) or per hour (PTU) |
| Regions | Single (provider-managed) | 25+ regions, three scopes |
| Data residency | US by default | Configurable (Regional, Data Zone, Global) |
| SLA | Per OpenAI terms | Backed by Azure SLA (99.9%+) |
| Procurement | Credit card or invoice | Azure subscription, EA, MCA discounts apply |
| Compliance | SOC2, GDPR | SOC2, HIPAA BAA, FedRAMP High, PCI |
| Quota model | Per-account RPM/TPM | Per-deployment, regional |
| Provisioned capacity | n/a | PTU (hourly or reserved) |
The compliance and procurement story is why enterprise engineering teams end up on Azure: the model is the same, but the BAA and the Azure subscription you already have make it the path of least friction.
Pay-as-you-go (Standard) pricing
The default Azure OpenAI deployment type is Standard, billed per input and output token. The rate card mirrors openai.com's structure with input, cached input, and output rates per million tokens. The model families on Azure's pricing page include:
- GPT-6.1 Terra (released Oct 2026). Microsoft made it generally available in Foundry the day OpenAI released it, positioned for high-volume visual and screen-based tasks at a lower price point than Astra. On Global Standard it costs $1 input, $0.05 cached input, and $5 output per million tokens for short context, and it launched on Global Standard and Data Zone Standard in the US, EU, and APAC.
- GPT-6 Astra, Sol, and Luna (released Sep 2026). Per Microsoft's launch post, Astra is aimed at demanding reasoning, software engineering, and computer-use work, Sol is the more cost-effective option for production agents, and Luna is Sol's smaller, faster sibling for high-volume tasks. Each has short- and long-context pricing tiers.
- GPT-5.6 Sol, Terra, and Luna (released Jul 2026). Microsoft positions Sol for extended reasoning and code, Terra as the balanced everyday model, and Luna as the fastest, lowest-cost option in the family, though OpenAI has since released GPT-6.1 Terra as the successor to 5.6 Terra.
- gpt-5.5 (released Apr 2026). 1.05M context, 128k max output.
- gpt-5.4 and gpt-5.4-pro (released Mar 2026). Same context, lower latency than 5.5 on simple tasks.
- gpt-5.4-mini and gpt-5.4-nano (released Mar 2026). 400k context, cheaper for high-volume use.
- gpt-5.3-codex (released Feb 2026). Coding-tuned.
- gpt-5.2 and gpt-5.2-codex (released late 2025 / early 2026). Still in the catalog for stable workloads.
On Standard deployments, prompt caching and Batch API discounts work the same way they do on openai.com: cached prompt tokens are billed at a steep discount (commonly around 90% off the regular input rate), and Batch API requests submitted asynchronously are typically billed at 50% off. Both apply automatically when the request meets the criteria; you don't need a different deployment.
Standard deployment scopes
When you create a Standard deployment, you pick a scope:
- Global Standard. Requests can be served from any Azure region in OpenAI's global pool. Highest throughput, broadest model availability, no data residency guarantee.
- Data Zone Standard. Requests stay within a data zone (US, EU, APAC). The per-token rate can run above Global: for GPT-6.1 Terra, Microsoft lists the US zone at 10% more and the EU and APAC zones at 20% more.
- Regional Standard. Requests stay in one Azure region. Strictest residency, smallest capacity pool, slightly higher latency tail.
Narrowing the scope trades capacity and latency variance, and on some models a higher per-token rate, against data residency, so check your model's rate for each scope on the pricing page. Pick the narrowest scope that satisfies your compliance team.
Provisioned Throughput Units (PTU) explained
PTU is Azure's reserved-capacity model. Instead of paying per token, you pay per hour for an allocation of model processing capacity. The unit, the PTU, abstracts away tokens-per-second so the same PTU quota works across models.
The general shape:
- You buy PTU quota in a region for a given deployment scope (Global Provisioned, Data Zone Provisioned, or Regional Provisioned).
- Each model has a minimum PTU deployment size (typically 15 to 50 PTU for GPT-5 family).
- The deployment processes requests up to 100% utilization. Past that, Azure returns HTTP 429 and you fail over.
- You pay the hourly rate whether or not you saturate the deployment.
When PTU wins: steady, predictable production traffic with tight latency SLOs. Standard deployments on Azure share capacity with other customers, which means tail latency varies. PTU deployments give you stable max latency.
When PTU loses: spiky or low-volume traffic. If your deployment sits at 20% utilization, you're paying for five times the capacity you actually use, so your effective cost per token is five times what the same deployment costs at full load.
Where the break-even sits depends on the PTU rate for your model and region, which is why it's worth running the comparison in the walkthrough below before you commit. Low or spiky utilization favors Standard, and sustained high utilization favors PTU on both cost and latency predictability.
Reservations: how the commitment discount stack works
Buying PTU at the hourly rate is the most expensive way to do it. Azure offers two reservation terms:
- Monthly reservation. Commit for one month, get a meaningful discount versus hourly (typically in the 20 to 40% range depending on region and model).
- Yearly reservation. Commit for one year, get a larger discount (commonly 40 to 65% off hourly).
Reservations are bought against your subscription and apply automatically to any matching PTU deployment in that subscription and region. Importantly, in 2026 reservations work across the Foundry Models catalog: a 500 PTU reservation bought for Azure OpenAI also applies if you deploy DeepSeek-R1 or Llama 3.3 70B on PTU in the same region.
This makes the procurement math cleaner: forecast your total PTU need, buy a reservation that covers your steady state, and pay hourly only for spike capacity.
Microsoft enterprise agreement bundling
If your company already has an Enterprise Agreement (EA) or Microsoft Customer Agreement (MCA), Azure OpenAI consumption rolls into it. Multi-year Azure spend commitments (MACC) include Azure OpenAI, so OpenAI bills count against your committed Azure spend and any negotiated MACC discount carries through. Resource-group-based cost attribution makes per-team accounting cleaner than on openai.com, and partner programs (Microsoft for Startups, ISV programs, AI Co-Innovation) sometimes include Azure OpenAI credits worth asking your account team about.
Cost calculation walkthrough
Suppose you're running a customer-facing chat feature on gpt-5.4-mini. Average request shape:
- 4,000 input tokens (system prompt + retrieved context + user message)
- 800 output tokens
- 60% of input tokens come from a stable system prompt (cache-eligible)
- 500 requests per minute at peak, 100 RPM average
Step 1: per-request cost on Standard pay-as-you-go.
Let I = input rate per million tokens, C = cached input rate (about 10% of I), O = output rate per million tokens. Per request:
cost_per_request =
    (4000 * 0.6 * C / 1_000_000) +    // cached portion of input
    (4000 * 0.4 * I / 1_000_000) +    // uncached input
    (800 * O / 1_000_000)             // output
Plug in the live rates from the Azure OpenAI pricing page, multiply by your monthly request volume (avg RPM x 60 x 24 x 30), and you have a Standard estimate.
Step 2: PTU estimate.
Open the Azure capacity calculator at ai.azure.com/resource/calculator. Enter gpt-5.4-mini, your average input/output shape, and your peak RPM. The calculator returns the minimum PTU count to serve peak traffic without 429s. Multiply by hourly rate x 730 hours/month.
Step 3: compare.
If the PTU monthly cost comes in below the Standard monthly cost at your forecast volume, PTU wins. Add a yearly reservation discount on top if you're confident in the steady state.
Step 4: account for spikes.
PTU sized for peak is expensive if peak is 5x average. The common pattern: size PTU for average, use Standard as spillover for spikes via the Azure spillover feature or a gateway-level fallback.
Using a gateway for Azure OAI + native OAI failover
The single best architectural pattern for cost and reliability in 2026: put both Azure OpenAI and native OpenAI behind a gateway. The application makes one API call; the gateway decides which provider gets it.
With Respan's AI gateway, you define the fallback chain once, at the org level or per request, and Respan reroutes the call when a provider errors or rate-limits:
import os
from openai import OpenAI

client = OpenAI(
    base_url="https://api.respan.ai/v1",
    api_key=os.environ["RESPAN_API_KEY"],
)

# Fallback chain defined in Respan:
#   primary: azure/gpt-5.4-mini (PTU deployment in eastus2)
#   fallback 1: azure/gpt-5.4-mini (Standard in westus3) when PTU saturates
#   fallback 2: openai/gpt-5.4-mini (on 429 or 5xx)

response = client.chat.completions.create(
    model="azure-gpt-5.4-mini",   # gateway alias
    messages=[...],
)
What this buys you:
- PTU saturation handling. When your Azure PTU deployment hits 100% and returns 429, the gateway moves the request down the chain automatically. Same model, no app code change.
- Outage resilience. If Azure has a regional incident, traffic shifts to native OpenAI without a redeploy.
- Cost attribution. Respan breaks cost down by model, by request, and by end customer, and custom attributes let you tag each request with a feature name, which answers the question Azure cost reports can't: which feature drove the bill.
- Unified observability. Every call is logged as a span with latency and cost attached, in one trace stream regardless of which backend served it. No more reconciling Azure Application Insights with OpenAI dashboard exports.
Respan also runs an exact-match cache that serves repeat requests near-free and instantly, which sits in front of Azure's own prompt caching as a separate layer.
See how LLM gateways work for the broader pattern and Best LLM Gateways in 2026 for vendor comparisons.
Common pricing mistakes
- Buying PTU before measuring utilization. Run Standard for two weeks, look at your token-per-minute curve, then size PTU. Buying PTU based on a hope is the most expensive mistake on this list.
- Single-region PTU with no spillover. When that region runs out of capacity, your app dies. Configure spillover or gateway-level fallback on day one.
- Ignoring cached input pricing. A long stable system prompt at 10% of the input rate is the single biggest cost lever on Standard. Make sure your system prompt is identical across requests so it caches.
- Mixing Standard and PTU traffic blindly. PTU deployments don't share rate limits with Standard. If you're using both, you need explicit routing logic or a gateway.
- No per-feature cost attribution. Azure cost reports tell you what Azure OpenAI costs in aggregate. They don't tell you which product feature ate it. That attribution belongs at the application layer or in your gateway.
FAQ
Is Azure OpenAI cheaper than openai.com?
Per token on Global Standard, the rates are very close (typically within 5%), while Data Zone deployments can cost more. The savings come from PTU + reservations when you have predictable volume, and from EA discounts on the broader Azure bill.
What's the minimum PTU deployment size?
It varies by model. GPT-5 family typically starts around 15 to 50 PTU. Check the Foundry model capacities API or the Azure portal for the exact minimum for your target model.
Can I switch a deployment from Standard to PTU?
Not in place. You create a new PTU deployment and migrate traffic. A gateway makes this a config change instead of an app deployment.
How does prompt caching work on Azure OpenAI?
Same as openai.com: prompts above a minimum length and seen recently are cached, and cached portions of subsequent requests are billed at a steep discount. The cache is automatic on Standard deployments.
Does the Batch API discount apply on Azure?
Yes. Submit a Batch deployment, send a batch file, and pay roughly 50% of the Standard rate. Useful for offline workloads where 24-hour completion is acceptable.
Can I use Azure OpenAI from the regular OpenAI Python SDK?
Yes, by setting base_url and api_key to your Azure deployment. Even cleaner: put a gateway in front and let the gateway translate.
Do reservations carry across model families?
In 2026, yes. PTU reservations bought for one Foundry model apply against PTU deployments of other supported models in the same region and scope. This makes reservations much more useful than they were in 2024.