Choosing an LLM observability tool used to happen after launch. With LLM apps and agents now running customer-facing workflows, it's happening before release, and the shortlist keeps shifting as eval vendors, APM companies, and gateways all add tracing and scoring of their own.
The products sold as LLM or AI observability vary a lot in how much of a run they can see. Some trace every step of an agent and score its output on live traffic, while others started as eval suites, open-source libraries, or APM platforms and extended from there, which changes both what you can debug and what you pay at volume.
The deciding factor in production is whether one platform can show you the full run and tell you whether the output was any good, without wiring several tools together.
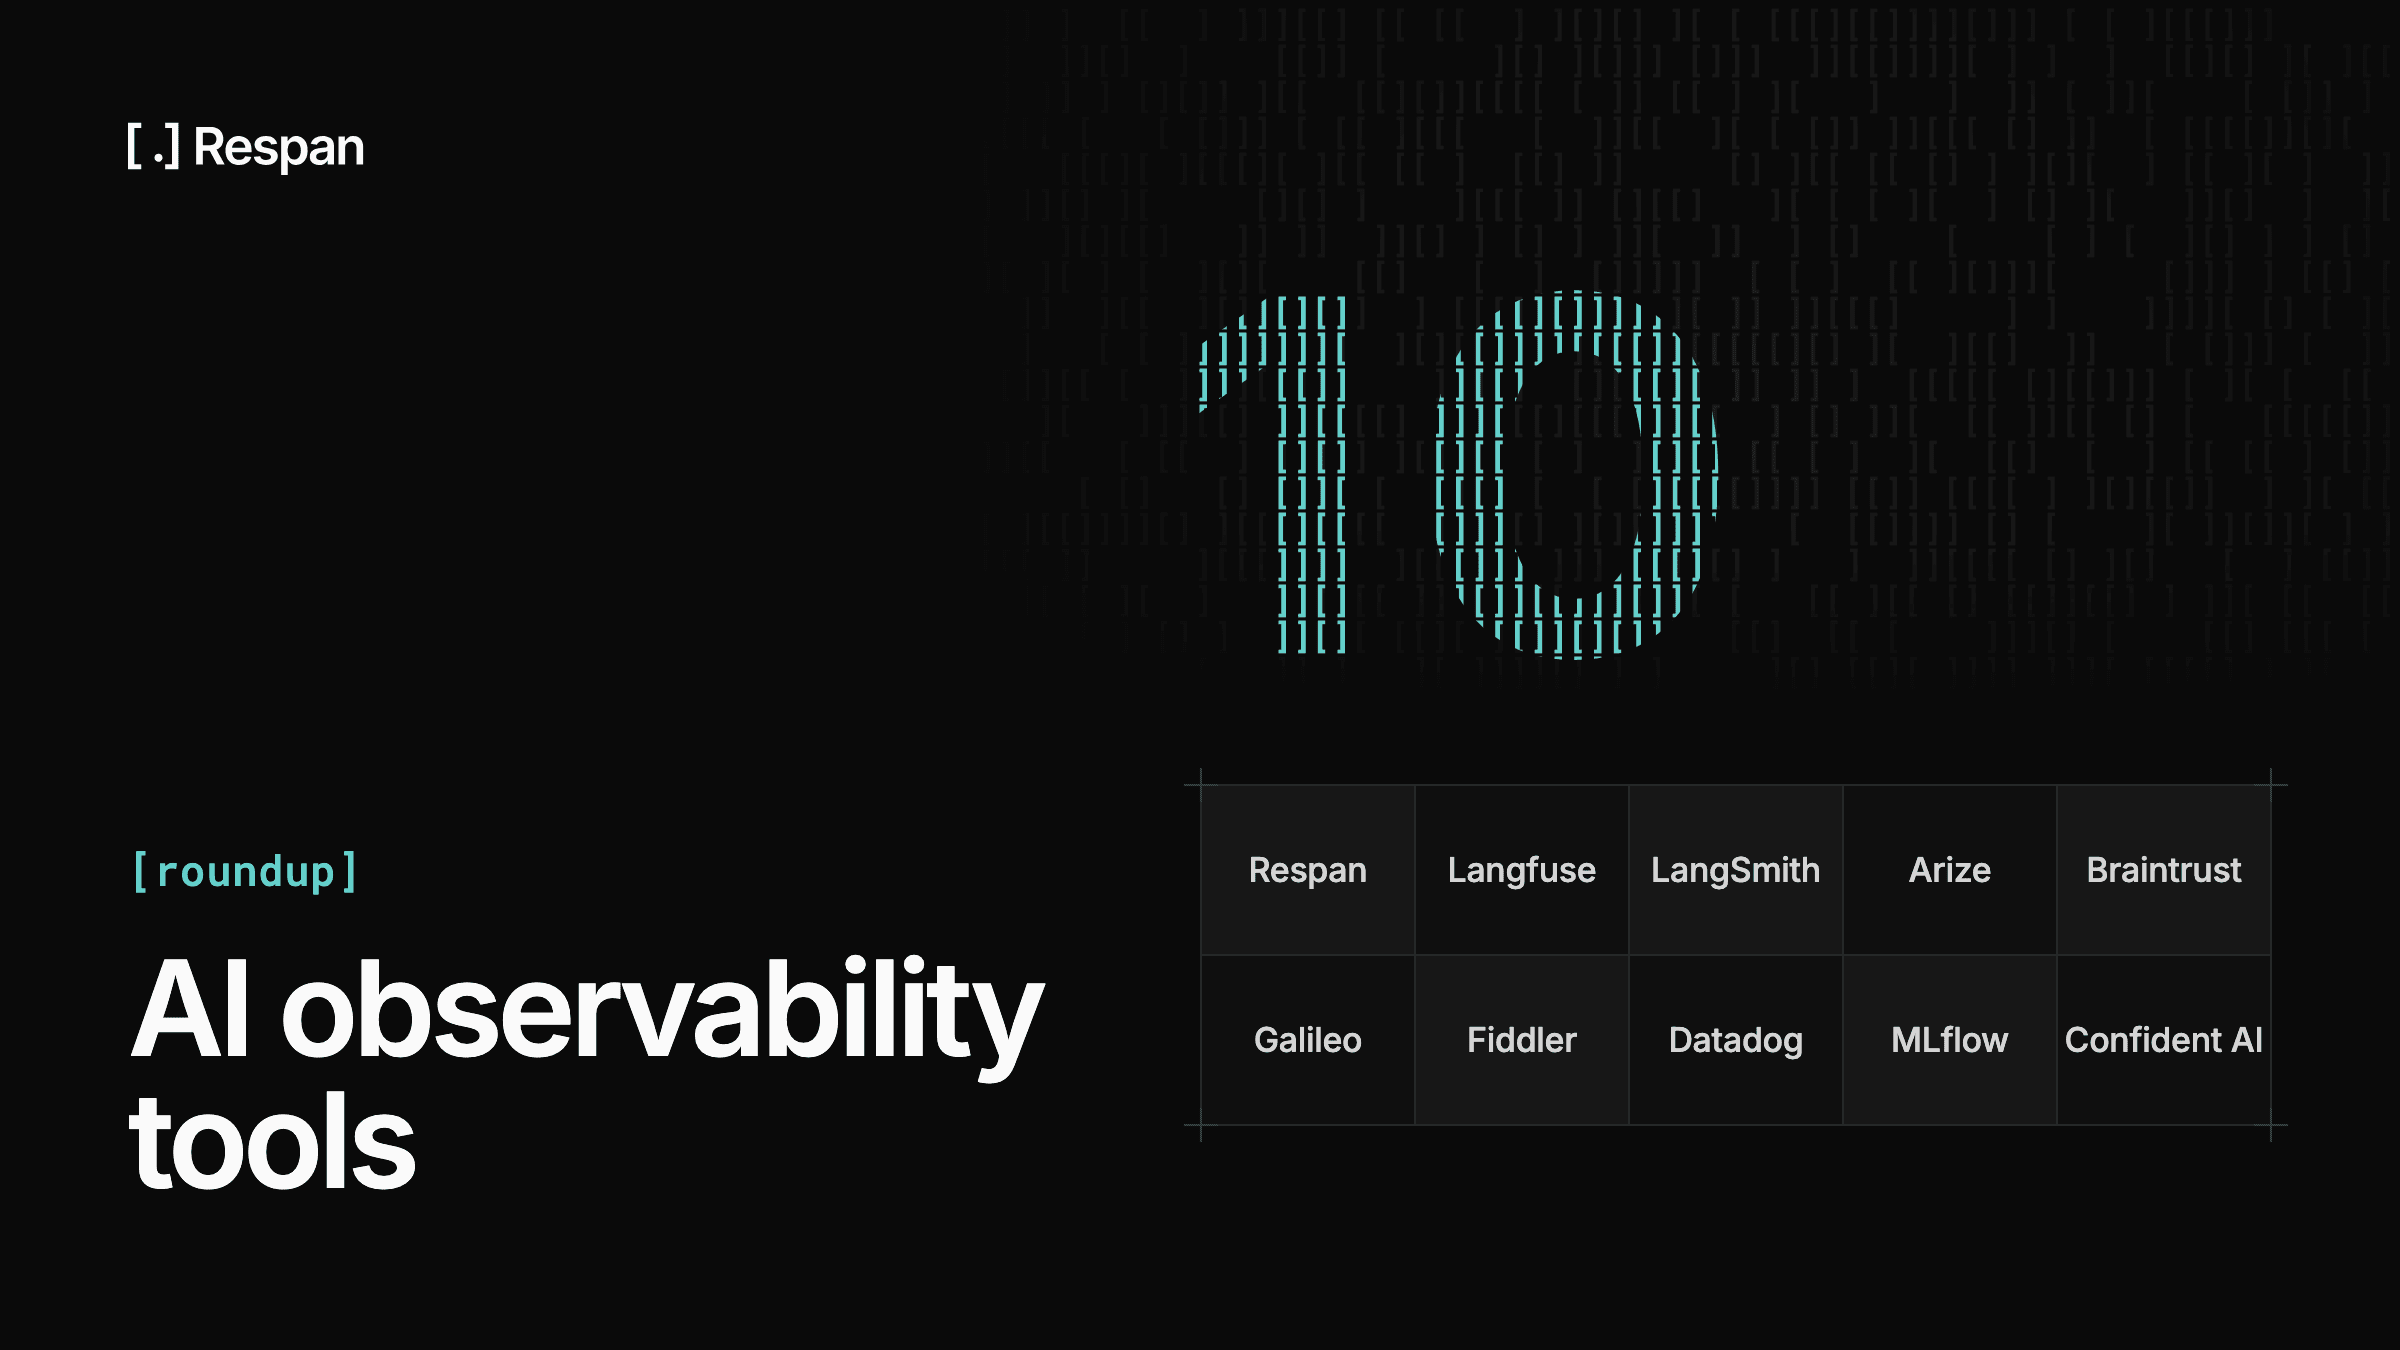
Below are the 10 best LLM observability tools and platforms in 2026, from open-source libraries to hosted platforms, compared on tracing, live scoring, and pricing.
TL;DR: Best LLM Observability Tools Compared
The short version, with each platform's starting price, open-source status, and best fit:
| Tool | Type | Starting price | Open source | Best for |
|---|---|---|---|---|
| Respan | Router, observability, and evals | Free; Team $199/mo | Open-source gateway | Production agents, one platform |
| Langfuse | Open-source LLM platform | Free; Core $29/mo | Yes, MIT | Open-source tracing and evals |
| LangSmith | Observability and evals | Free; $39/seat/mo | No | LangChain and LangGraph stacks |
| Arize Phoenix and Arize AX | ML and AI observability | Phoenix free; AX $50/mo | Phoenix, source-available | Mixed ML and LLM teams |
| Braintrust | Eval-first platform | Free; Pro $249/mo | Libraries only | Eval-driven teams |
| Opik | Open-source tracing and evals | Free; Pro $19/mo | Yes, Apache-2.0 | Low-cost hosted span volume |
| Galileo | Evals and guardrails | Free; from $100/mo | No | Splunk customers |
| Datadog | APM with agent module | Free; Pro $160/mo | No | Teams already on Datadog |
| MLflow | Open-source ML platform | Free to self-host | Yes, Apache-2.0 | MLflow and Databricks teams |
| Confident AI | Eval platform from DeepEval | Free; Starter $200/mo | DeepEval only | DeepEval users |
Starting prices are each vendor's published entry point, and most of these platforms meter on spans, traces, scores, or processed data, so the number that matters is the cost at your production volume.
What to Look for in an LLM Observability Tool
What an AI observability or LLM observability platform can report is bounded by where it sits and what it was built for, and once LLM apps and agents are in production those limits show up fast. These capabilities separate a platform you can run on from one you'll outgrow:
- Full run tracing - A failed agent run is usually a chain of reasonable-looking steps with one bad decision in it. The platform should record the whole run as one nested trace, including tool arguments, tool results, and retrieved context, so you can find the step that went wrong.
- Scoring on live traffic - Offline test sets catch what you anticipated. Scoring production traffic with LLM judges, code checks, or human review catches what you didn't, which is where unplanned failures show up.
- Cost and token attribution - Agents multiply token spend through loops and retries. Cost broken down by model, feature, and customer tells you which change doubled the bill and who it affects.
- Alerting on quality - Alerts inherited from infrastructure monitoring watch error rates and latency, and an agent that picks the wrong tool or skips a step usually moves neither. LLM monitoring that watches eval scores, cost, and token volume is what surfaces that kind of regression.
- Integration approach - Proxy integration is the fastest to set up but only sees requests passing through it. SDK instrumentation captures what happens inside the application, and OpenTelemetry-based instrumentation keeps your traces portable if you change platforms later.
- Open source and self-hosting - An open-source license lets you run the platform on your own infrastructure, but you also take on its databases, upgrades, and scaling, and the license itself varies, since some projects are OSI open source and others are source-available.
- Governance and compliance - Prompts and completions carry customer data. Look for PII masking, retention controls, access control, and the certifications your buyers ask about, such as SOC 2 and HIPAA with a BAA.
- Gateway and routing - Routing, fallbacks, and caching are often a separate purchase, which leaves the record of which model served a request apart from the record of how it performed. If you run more than one provider, keeping both in one place removes a correlation step from every incident.
The integration and self-hosting questions are worth settling early, since they're the hardest to change once traces are flowing through a platform.
How We Evaluated These Tools
Every platform was compared on the criteria above, with tracing depth and live scoring weighted most heavily, because those two decide whether a tool can show you the failure you need to debug. Pricing was judged at production volume rather than at the free tier, since an agent run can produce dozens of spans and most of these platforms meter on exactly that.
Tools that cover only one piece, like a standalone eval library or a gateway that logs requests without scoring them, were left out, because running either in production means adding a second product to fill the gap.
The 10 Best AI Observability Tools and Platforms
Respan comes first, followed by nine platforms that range from open-source libraries you run yourself to APM and ML platforms that added LLM tracing later.
1. Respan
Type: AI router with built-in observability and automated evals · Price: Free tier, Team $199/mo
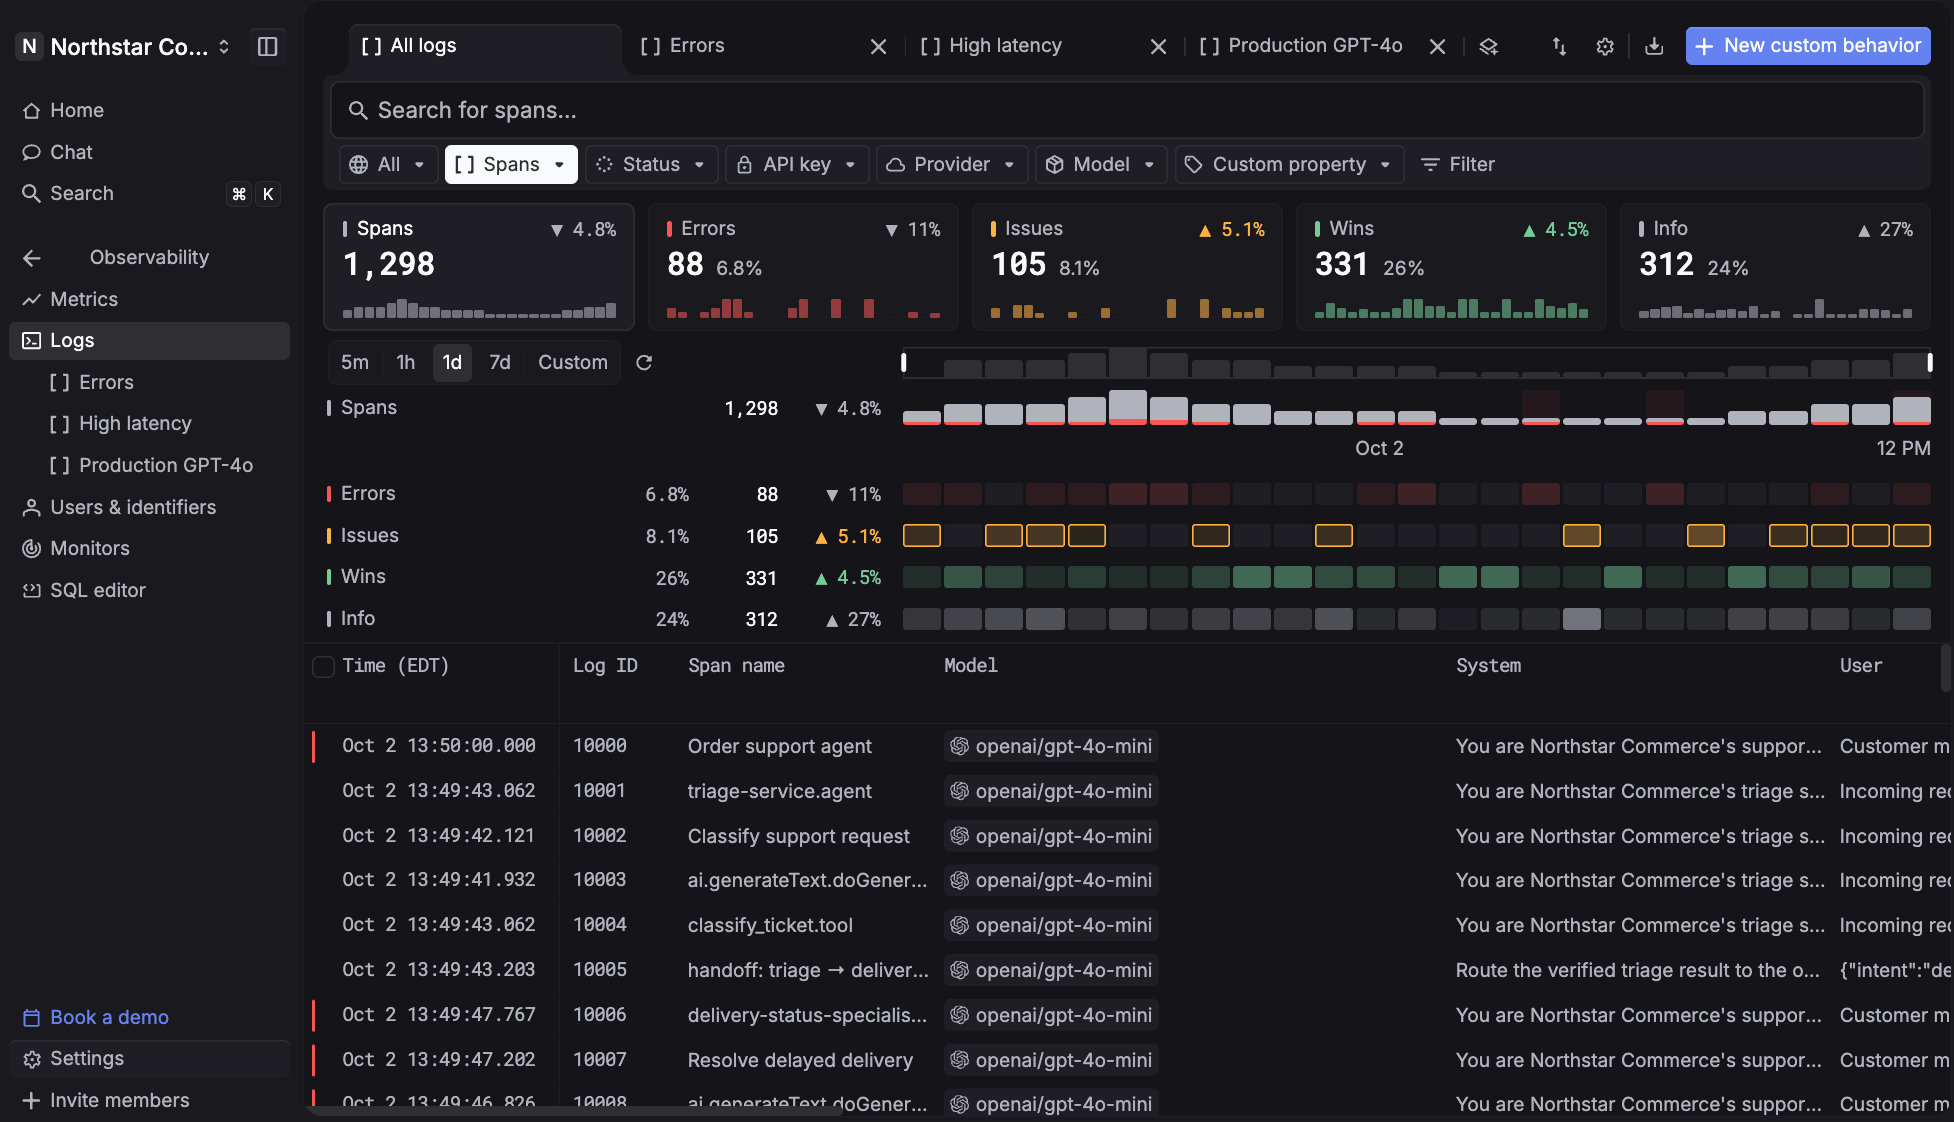
Respan sends every model call through one API and traces, prices, and scores it in the same place. Route, observe, and evaluate every LLM call, so a metric always ties back to the request or agent run behind it and a bad output leads to the step that caused it.
What that gets you:
- See every step of a run - Every LLM call, tool run, and agent step becomes a span in one nested trace, each with its own input, output, latency, and cost. Threads group a conversation's turns, so a bad answer on turn five traces back to context set on turn two, and traces can come from the SDK or any OpenTelemetry-instrumented app.
- Score quality on live traffic - Write a behavior in plain language, like a frustrated user or an agent skipping a step, and Respan scores every new span against it, with a person able to override any verdict. LLM-as-judge evaluators, datasets, and experiments cover testing before a change ships.
- Know where every dollar goes - Costs break down by model, request, and end customer. Spend limits warn and block per API key, and hard caps per customer keep one account from running up the bill.
- Hear it from Respan, not a customer - Monitors watch cost, errors, latency, or tokens and alert Slack, Microsoft Teams, email, or a webhook the moment one breaches.
- Stay up when a provider fails - The AI gateway routes to 1,000+ models. List the models to fall back to once, and traffic moves to the next one when a provider errors or rate-limits. The gateway is also available as open source under MIT or Apache-2.0, currently pre-alpha, to run on your own infrastructure and send each request into the platform as a trace.
- Close the loop - Add a bad trace to a dataset, test a fix against real cases in an experiment, and ship the winning prompt version without a code deploy.
- Pass the security review - SOC 2 and HIPAA with a BAA, with PII masking for prompts that carry customer data.
Pricing: Free covers 100k logs, 1k scores, 5 datasets, 2 evaluators, and 30-day retention with unlimited seats. Team is $199 per month billed yearly, with 10k scores, unlimited datasets, evaluators, and prompts, 30-day retention, and 5 members, with more at $15 each. Enterprise is custom. The open-source gateway is free under MIT or Apache-2.0.
Best fit: teams running LLM apps or agents in production who would rather debug one system than four.
2. Langfuse
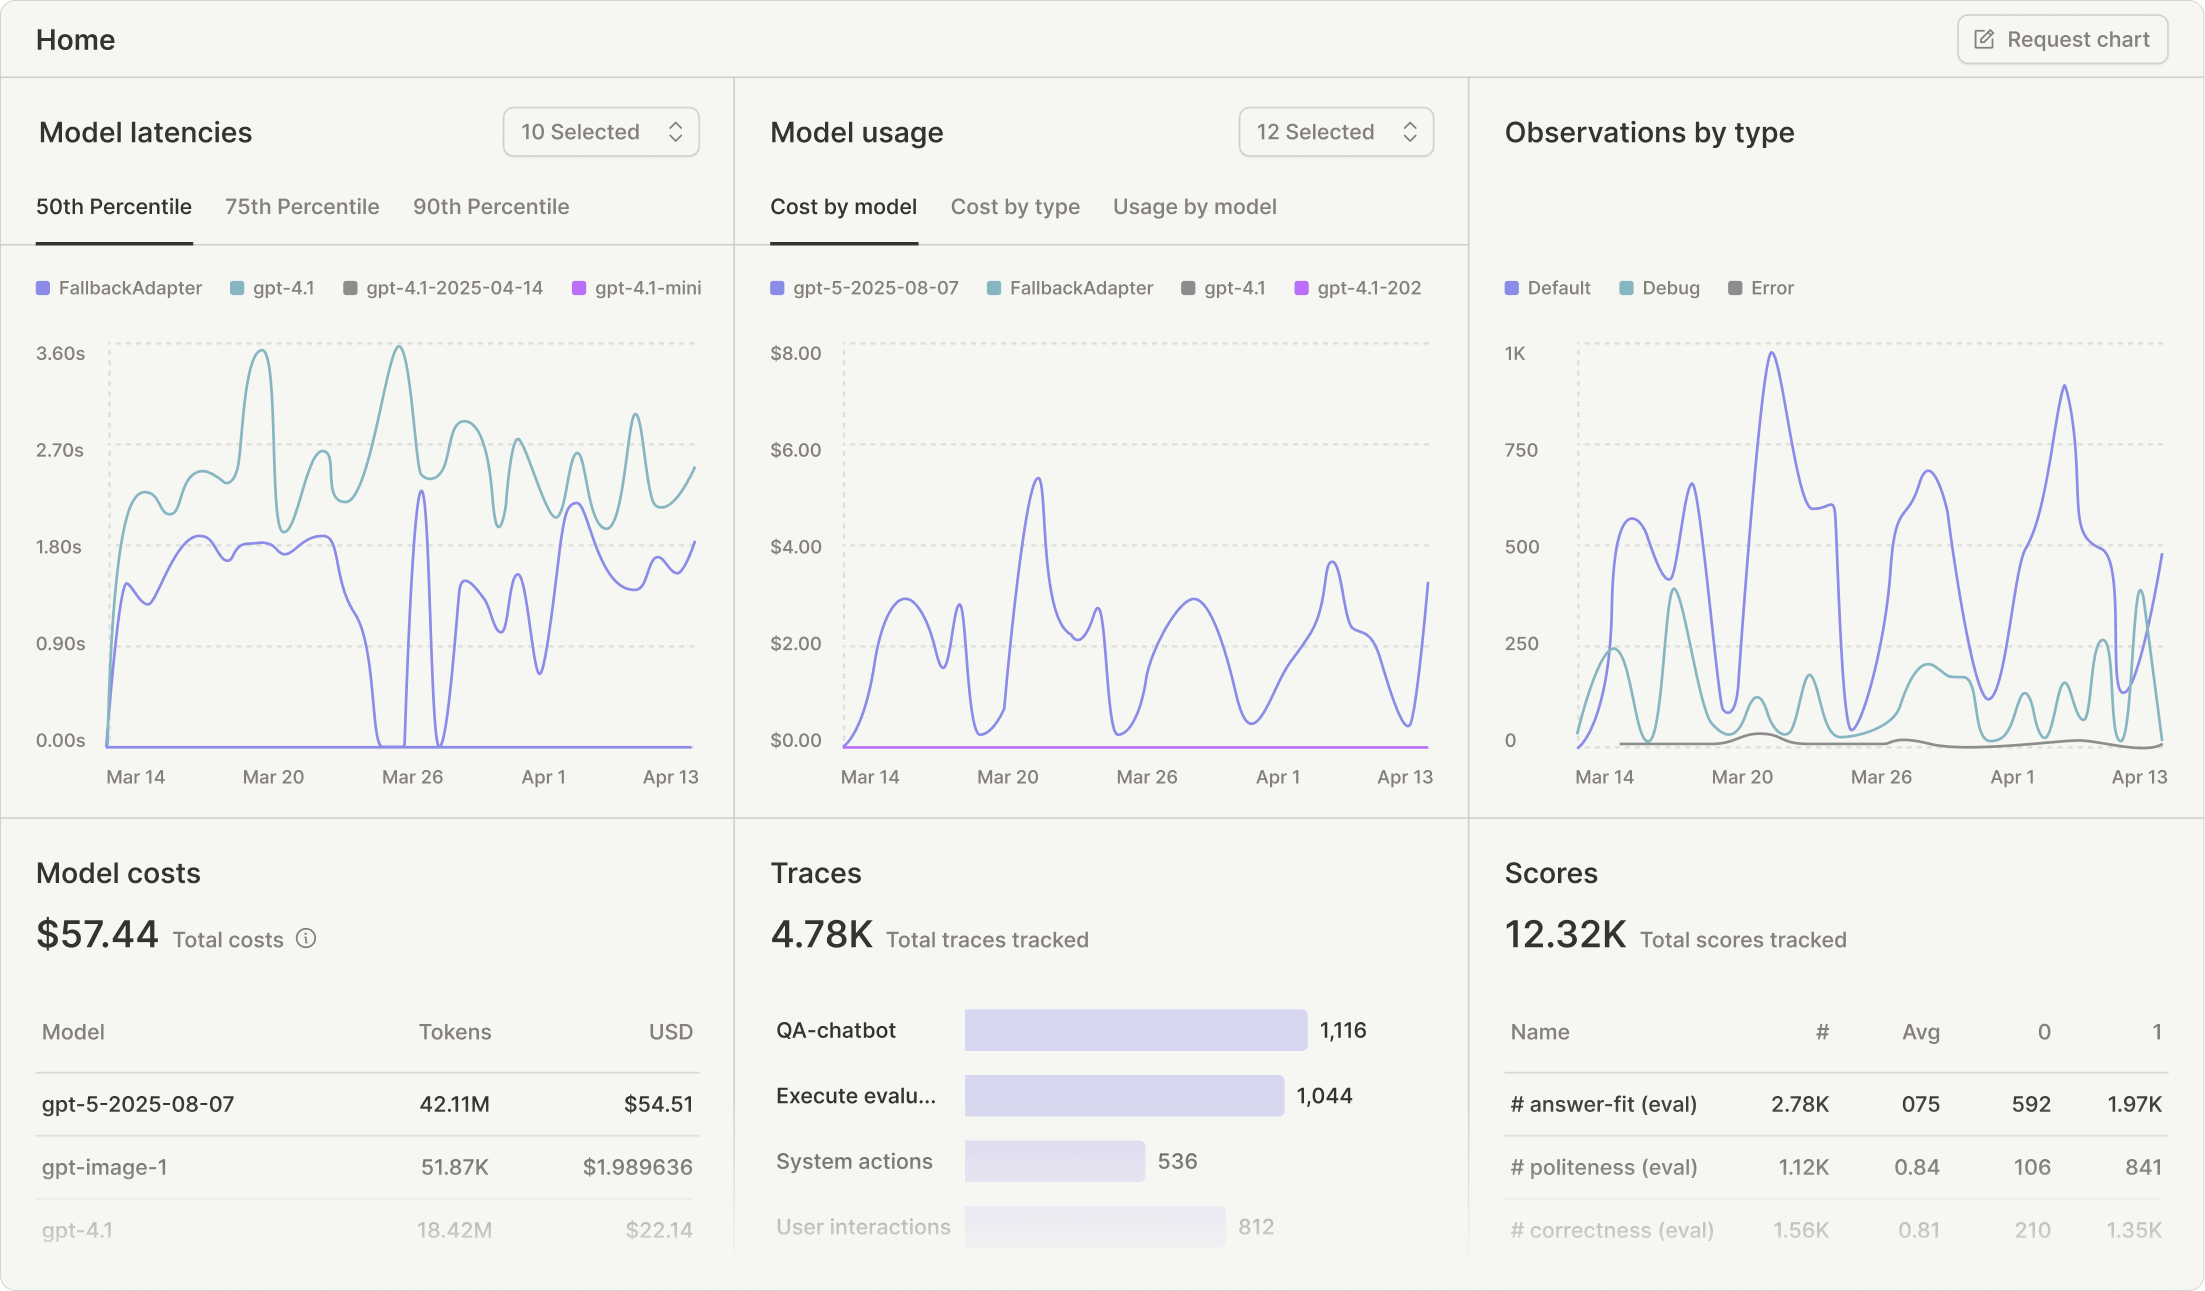
Type: Open-source LLM engineering platform · Price: Free tier, Core $29/mo
Langfuse is an open-source LLM engineering platform covering tracing, prompt management, datasets, and evaluation, with an MIT-licensed core you can run on your own infrastructure. Online evaluation runs LLM-as-a-judge against live production traffic, and alerts can fire on scores as well as on latency and cost, so a quality regression can reach someone without a second tool.
The tradeoff for open source is operational. Running it yourself means operating PostgreSQL, ClickHouse, Redis, and blob storage in production, which suits a platform team better than a small one and can push smaller teams toward the managed cloud. It also doesn't offer a gateway, so routing and fallbacks sit in a separate system, which is one of the main differences among the Langfuse alternatives worth comparing.
Pricing: Hobby is free with 50k units, 2 users, and 30 days of data access. Core is $29 per month for 100k units, then $8 per additional 100k, with unlimited users and 90 days of data access. Pro is $199 and Enterprise is $2,499. A unit is a trace, an observation, or a score, so scoring more of production costs the same as recording another step.
Best fit: teams that want open-source tracing and evals with the option to self-host.
3. LangSmith
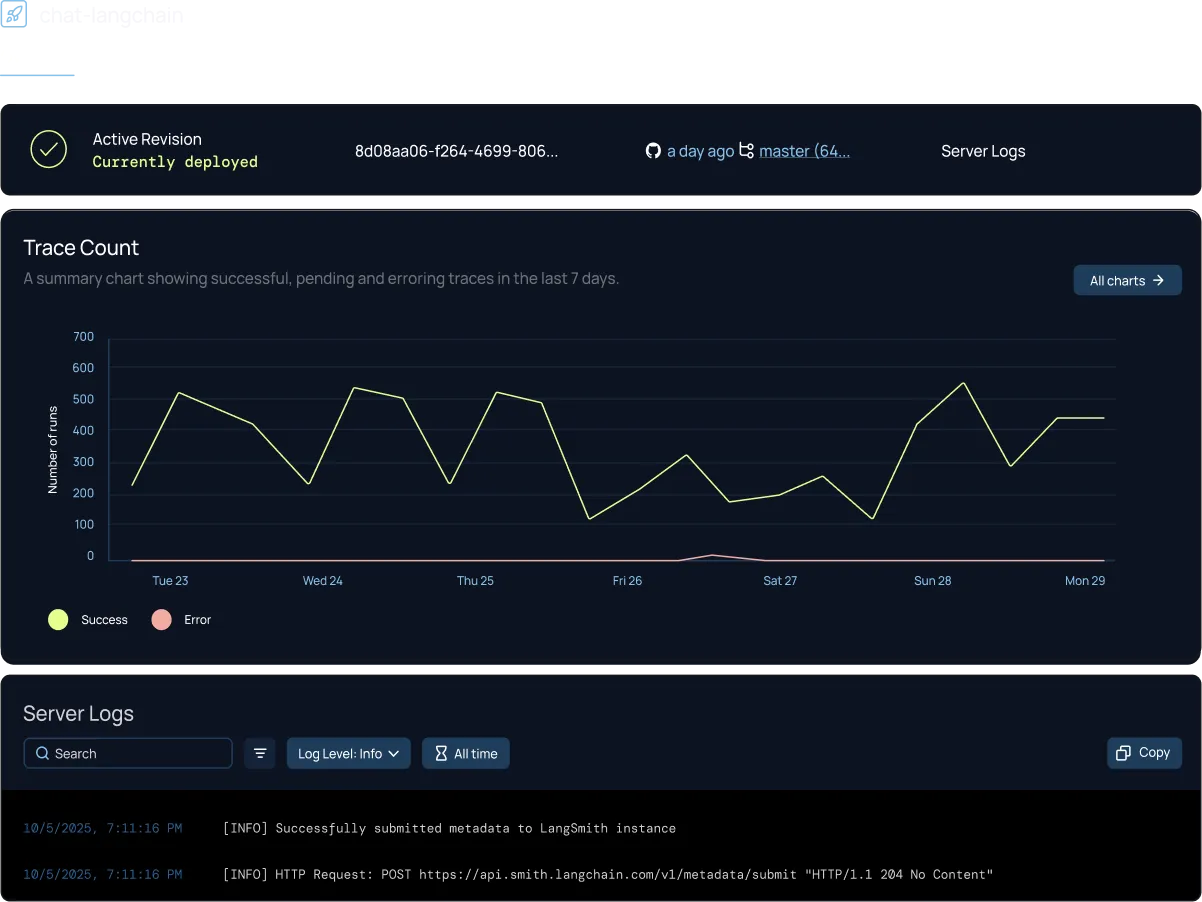
Type: Observability and evaluation platform · Price: Free tier, $39/seat/mo
Built by the LangChain team, LangSmith covers tracing, datasets, evaluation, annotation queues, and a prompt hub. For teams on LangGraph, LangSmith Studio adds an agent IDE where you visualize the graph, set breakpoints, edit state mid-run, and resume from a checkpoint, and an LLM Gateway for routing and fallbacks is in public beta on the Plus and Enterprise plans.
It traces any framework through a wrapper and supports OpenTelemetry, though the detail can be thinner outside LangChain and LangGraph, so adopting it is partly a bet on the framework. Seats and traces meter separately, so the bill tracks team size independently of usage. Base traces are also kept for only 14 days, which means reviewing an incident a few weeks later may require traces you paid to move to extended retention, and that pricing shape is one of the primary reasons people compare LangSmith alternatives.
Pricing: Developer is free with one seat and 5k base traces a month. Plus is $39 per seat per month with 10k base traces, then pay-as-you-go, and extended 180-day retention costs extra. LangSmith is proprietary, and self-hosting is only available as an Enterprise add-on.
Best fit: teams whose stack is LangChain today and will still be LangChain in two years.
4. Arize Phoenix and Arize AX
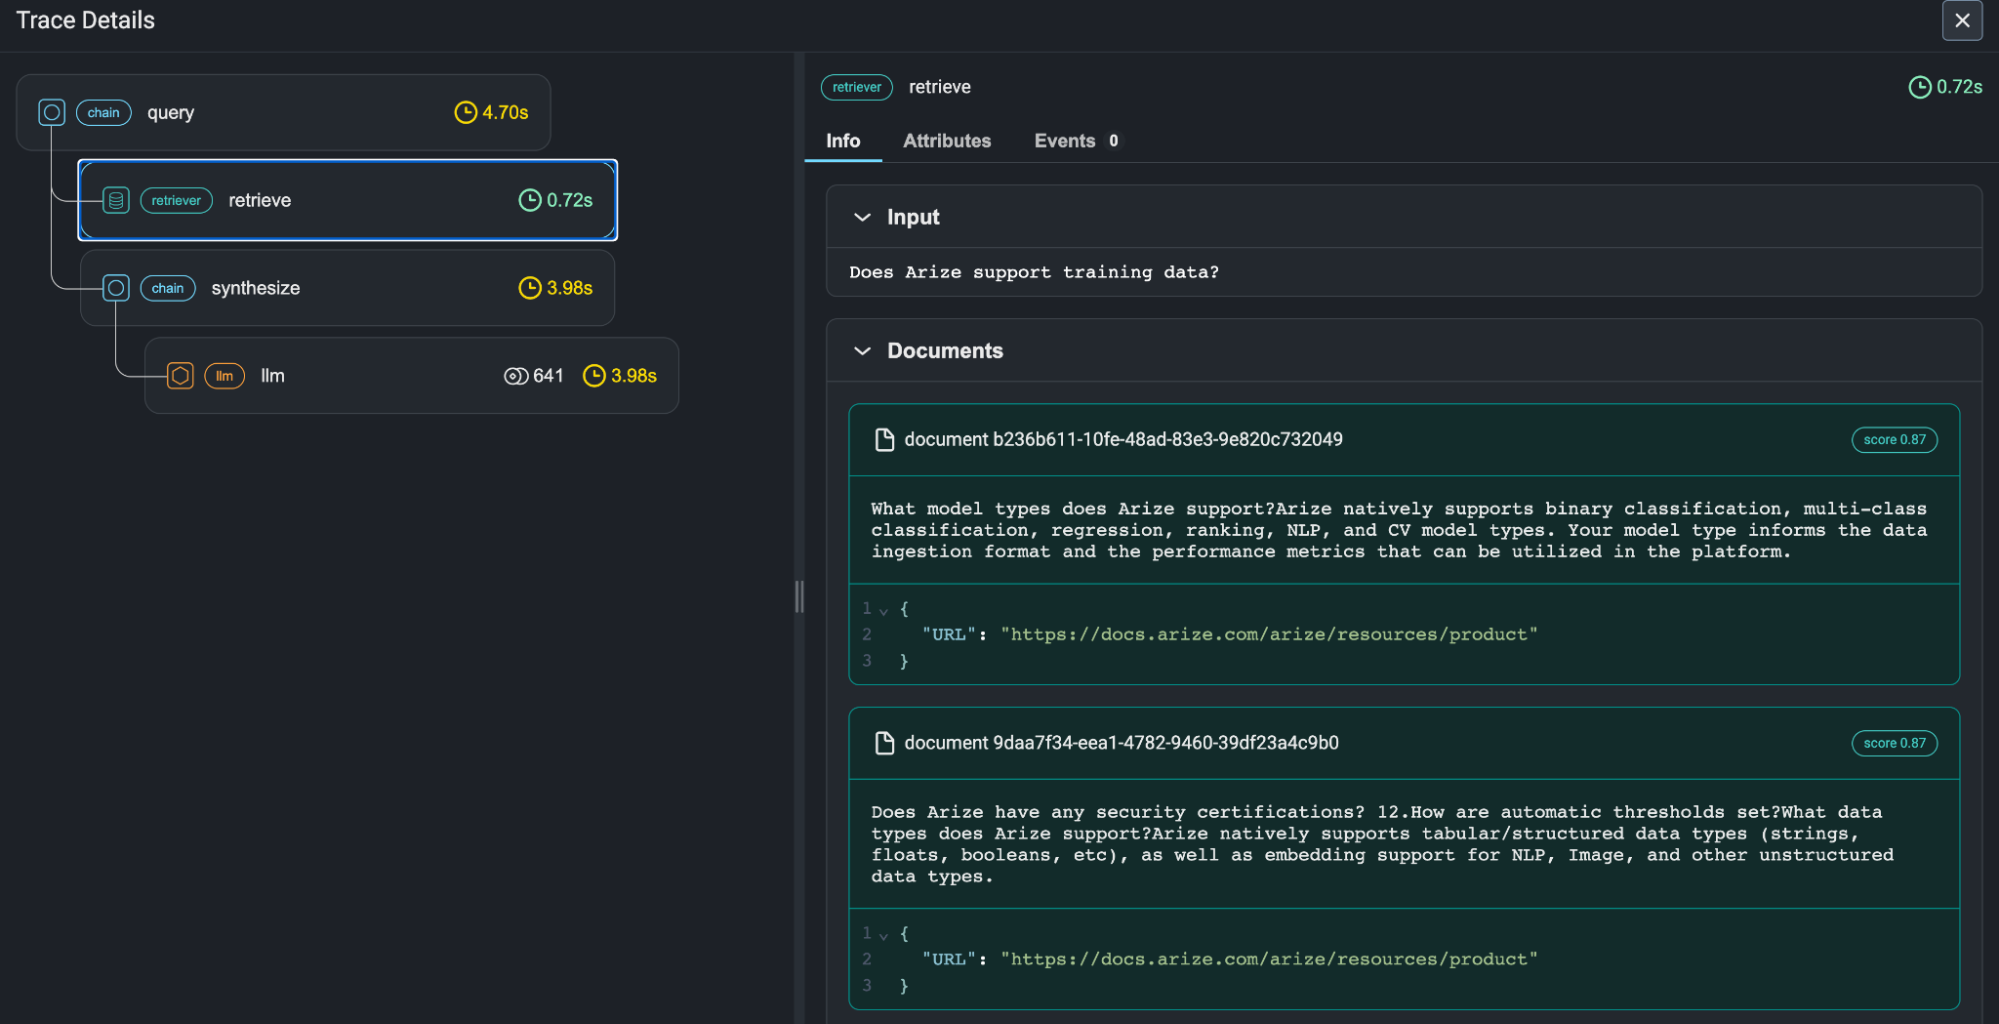
Type: ML and AI observability platform · Price: Phoenix free, AX from $50/mo
Arize comes from classical ML monitoring and extended into LLM and agent workloads through two products. Phoenix handles tracing and evaluation on top of OpenTelemetry and OpenInference, and it runs in a notebook, locally, or in Docker, which makes it useful during development. Arize AX is the managed platform, with online evals on traces included on every tier, prompt versioning, and custom monitors.
Phoenix is licensed under the Elastic License 2.0, which is source-available rather than OSI open source, so check it against your company's policy if that distinction matters. The constraint on AX is volume, since the free tier includes 25k spans a month and a single agent run can produce dozens of spans, so that allowance can go quickly once agents run at production scale.
Pricing: Phoenix is free to self-host. AX Free covers 25k spans and 15-day retention, AX Pro is $50 per month for 50k spans and 30-day retention, and AX Enterprise is custom, with self-hosting available.
Best fit: organizations running classical ML alongside LLM workloads, or teams that want OpenTelemetry-based tracing they can run themselves.
5. Braintrust
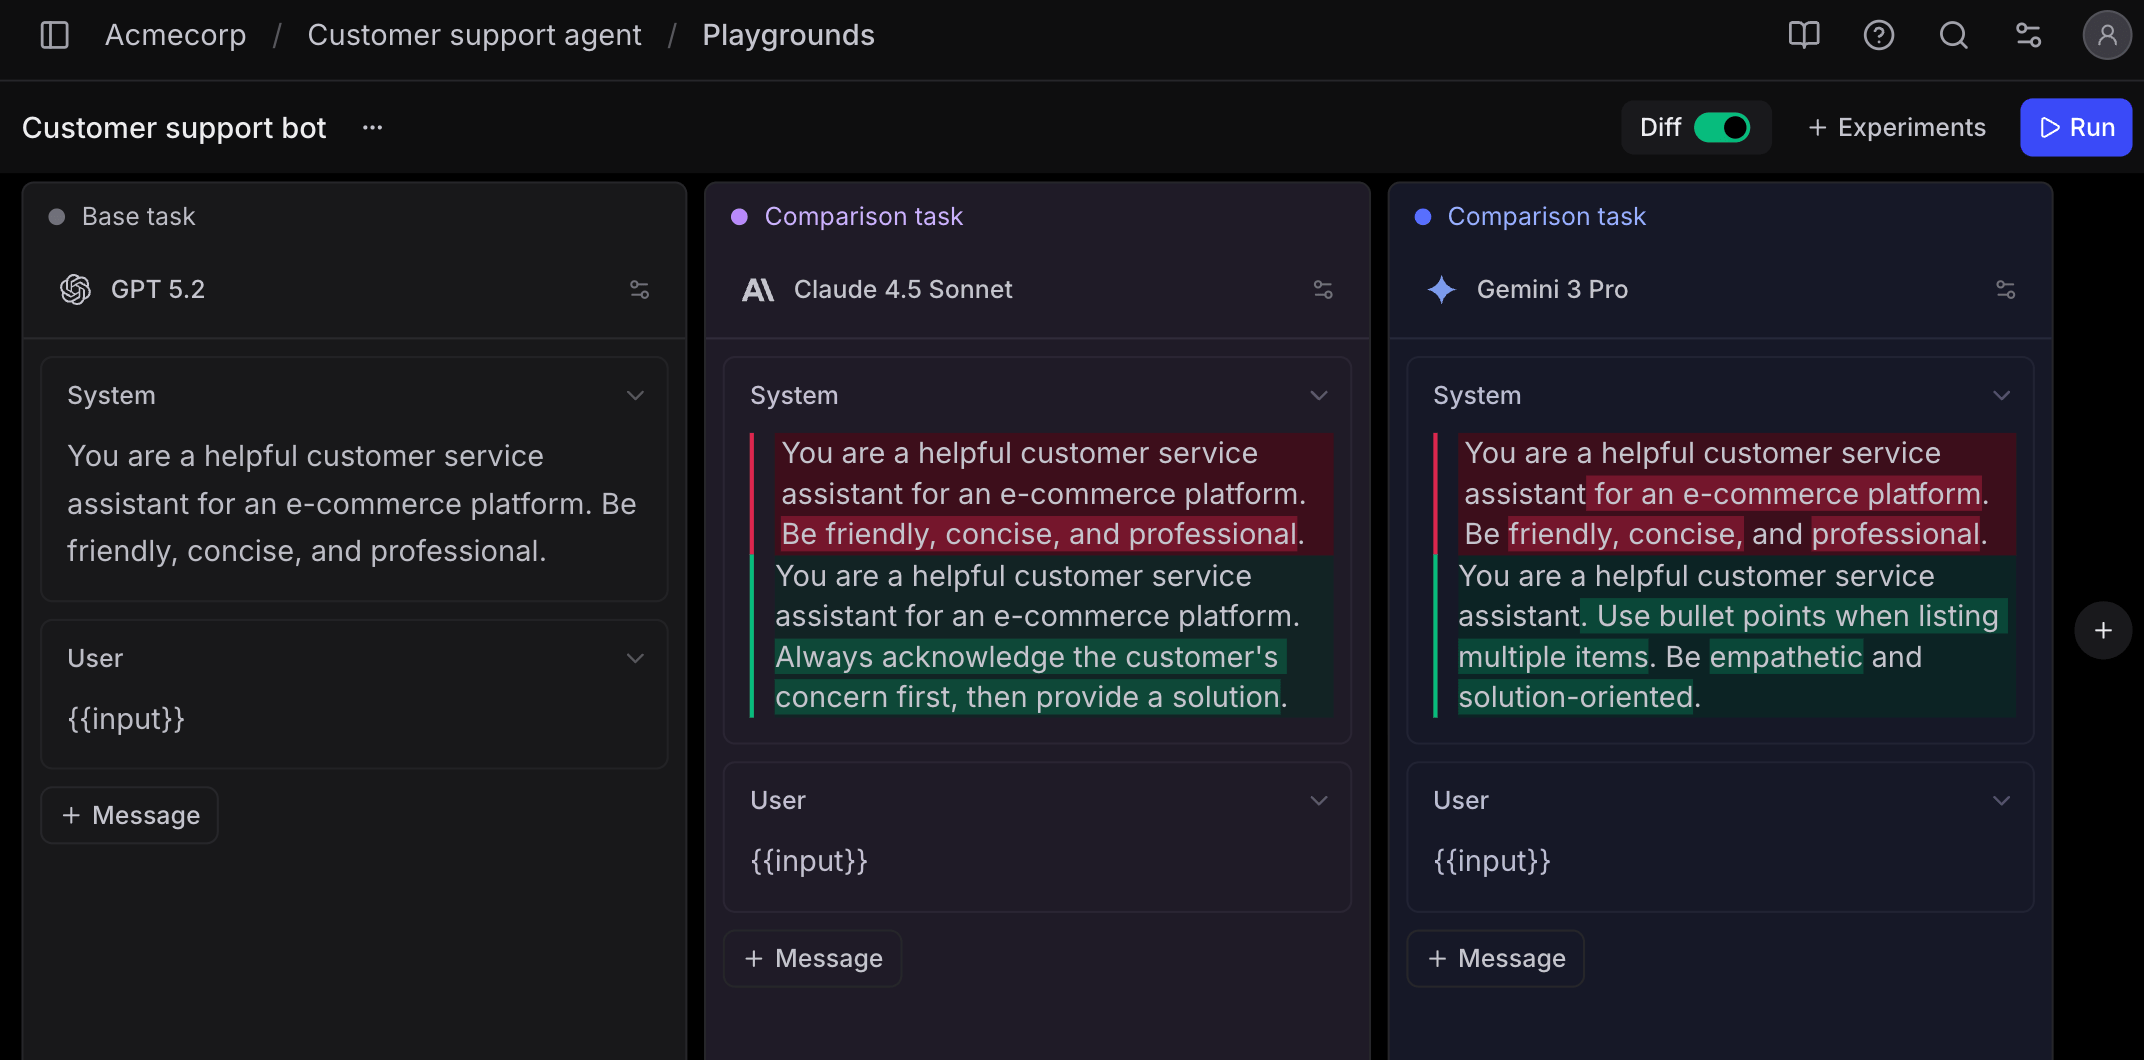
Type: Evaluation-first platform · Price: Free tier, Pro $249/mo
Evaluation is the center of Braintrust. Datasets, scorers, experiments, and regression comparisons are all first-class, and scores from LLM-as-a-judge, autoevals, or custom code can run against production traces as well as test sets. The Braintrust Gateway, in public preview, routes calls across providers with opt-in fallbacks.
Tracing exists to feed the eval workflow, so it is less developed than in platforms built for production debugging, which is the tradeoff at the center of most comparisons with Braintrust alternatives. Pricing meters on processed data and scores rather than seats, and eval volume can grow with the size of your test suite rather than with traffic, so the tier escalation might arrive earlier than what your team is planning for.
Pricing: Starter is free with 1 GB of processed data, 10k scores, and 14-day retention. Pro is $249 per month with 5 GB and 50k scores, then $3 per GB and $1.50 per 1k scores, with 30-day retention. On-prem or hosted deployment is Enterprise only.
Best fit: teams where eval discipline is the constraint.
6. Opik
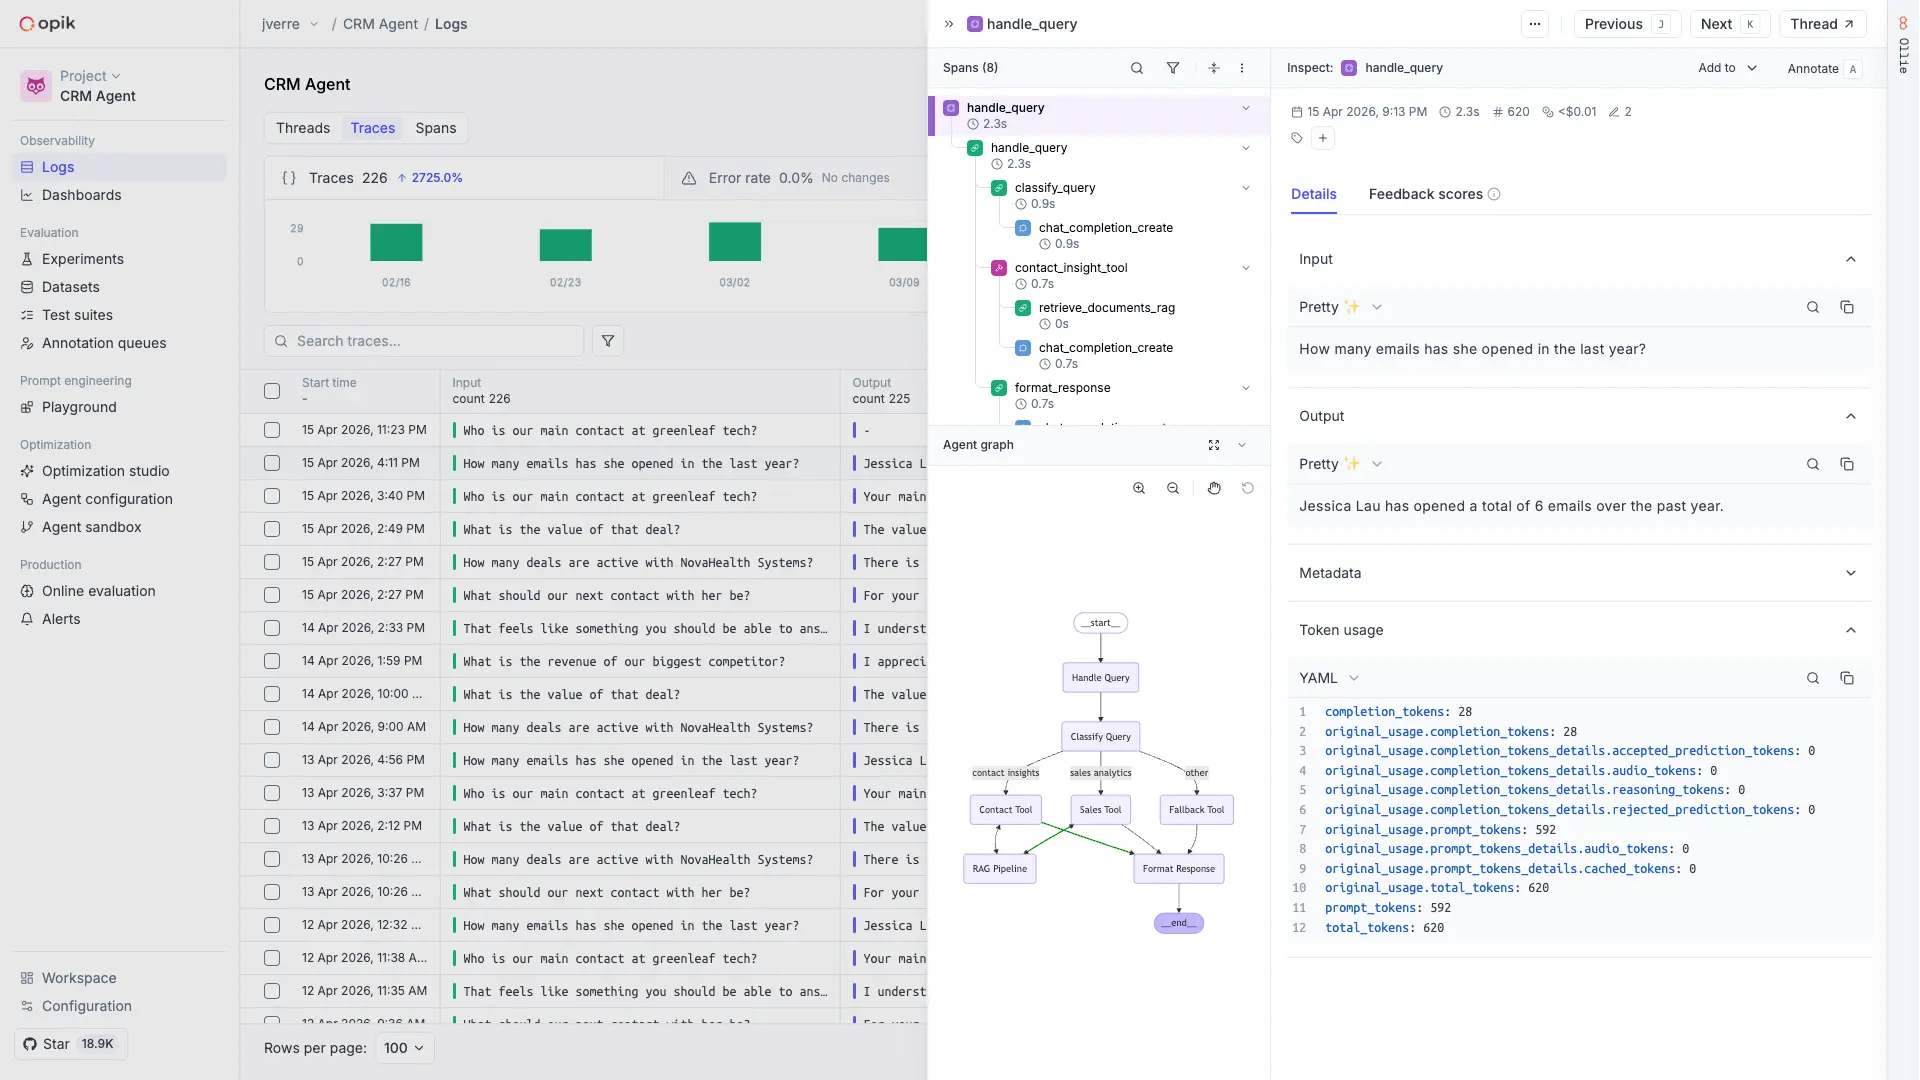
Type: Open-source tracing and evaluation platform · Price: Free tier, Pro $19/mo
From Comet, Opik is an Apache-2.0 platform for tracing and evaluating LLM apps and agents, and the open-source build is the same codebase as the hosted versions rather than a limited core. It captures full trace trees for multi-step agents and tool calls, groups chat turns into threads, and runs LLM-as-a-judge or code-based evaluators on new traces, threads, or spans as they're logged.
What you take on depends on how you run it. Guardrails for PII and topics are only available when you self-host, on every tier including Enterprise, so wanting both guardrails and managed hosting means picking one. A production self-host runs on Kubernetes with ClickHouse, MySQL, Redis, and MinIO behind it and ships without user management, which suits a platform team better than a small one.
Pricing: Free Cloud covers up to 10 members, 25k spans a month, and 60-day retention. Pro is $19 per month for up to 50 members and 100k spans, with additional spans at $5 per 100k and retention extendable to 400 days at $29 per 100k spans. Self-hosting is free.
Best fit: teams that want a fully open-source platform and low-cost hosted span volume.
7. Galileo
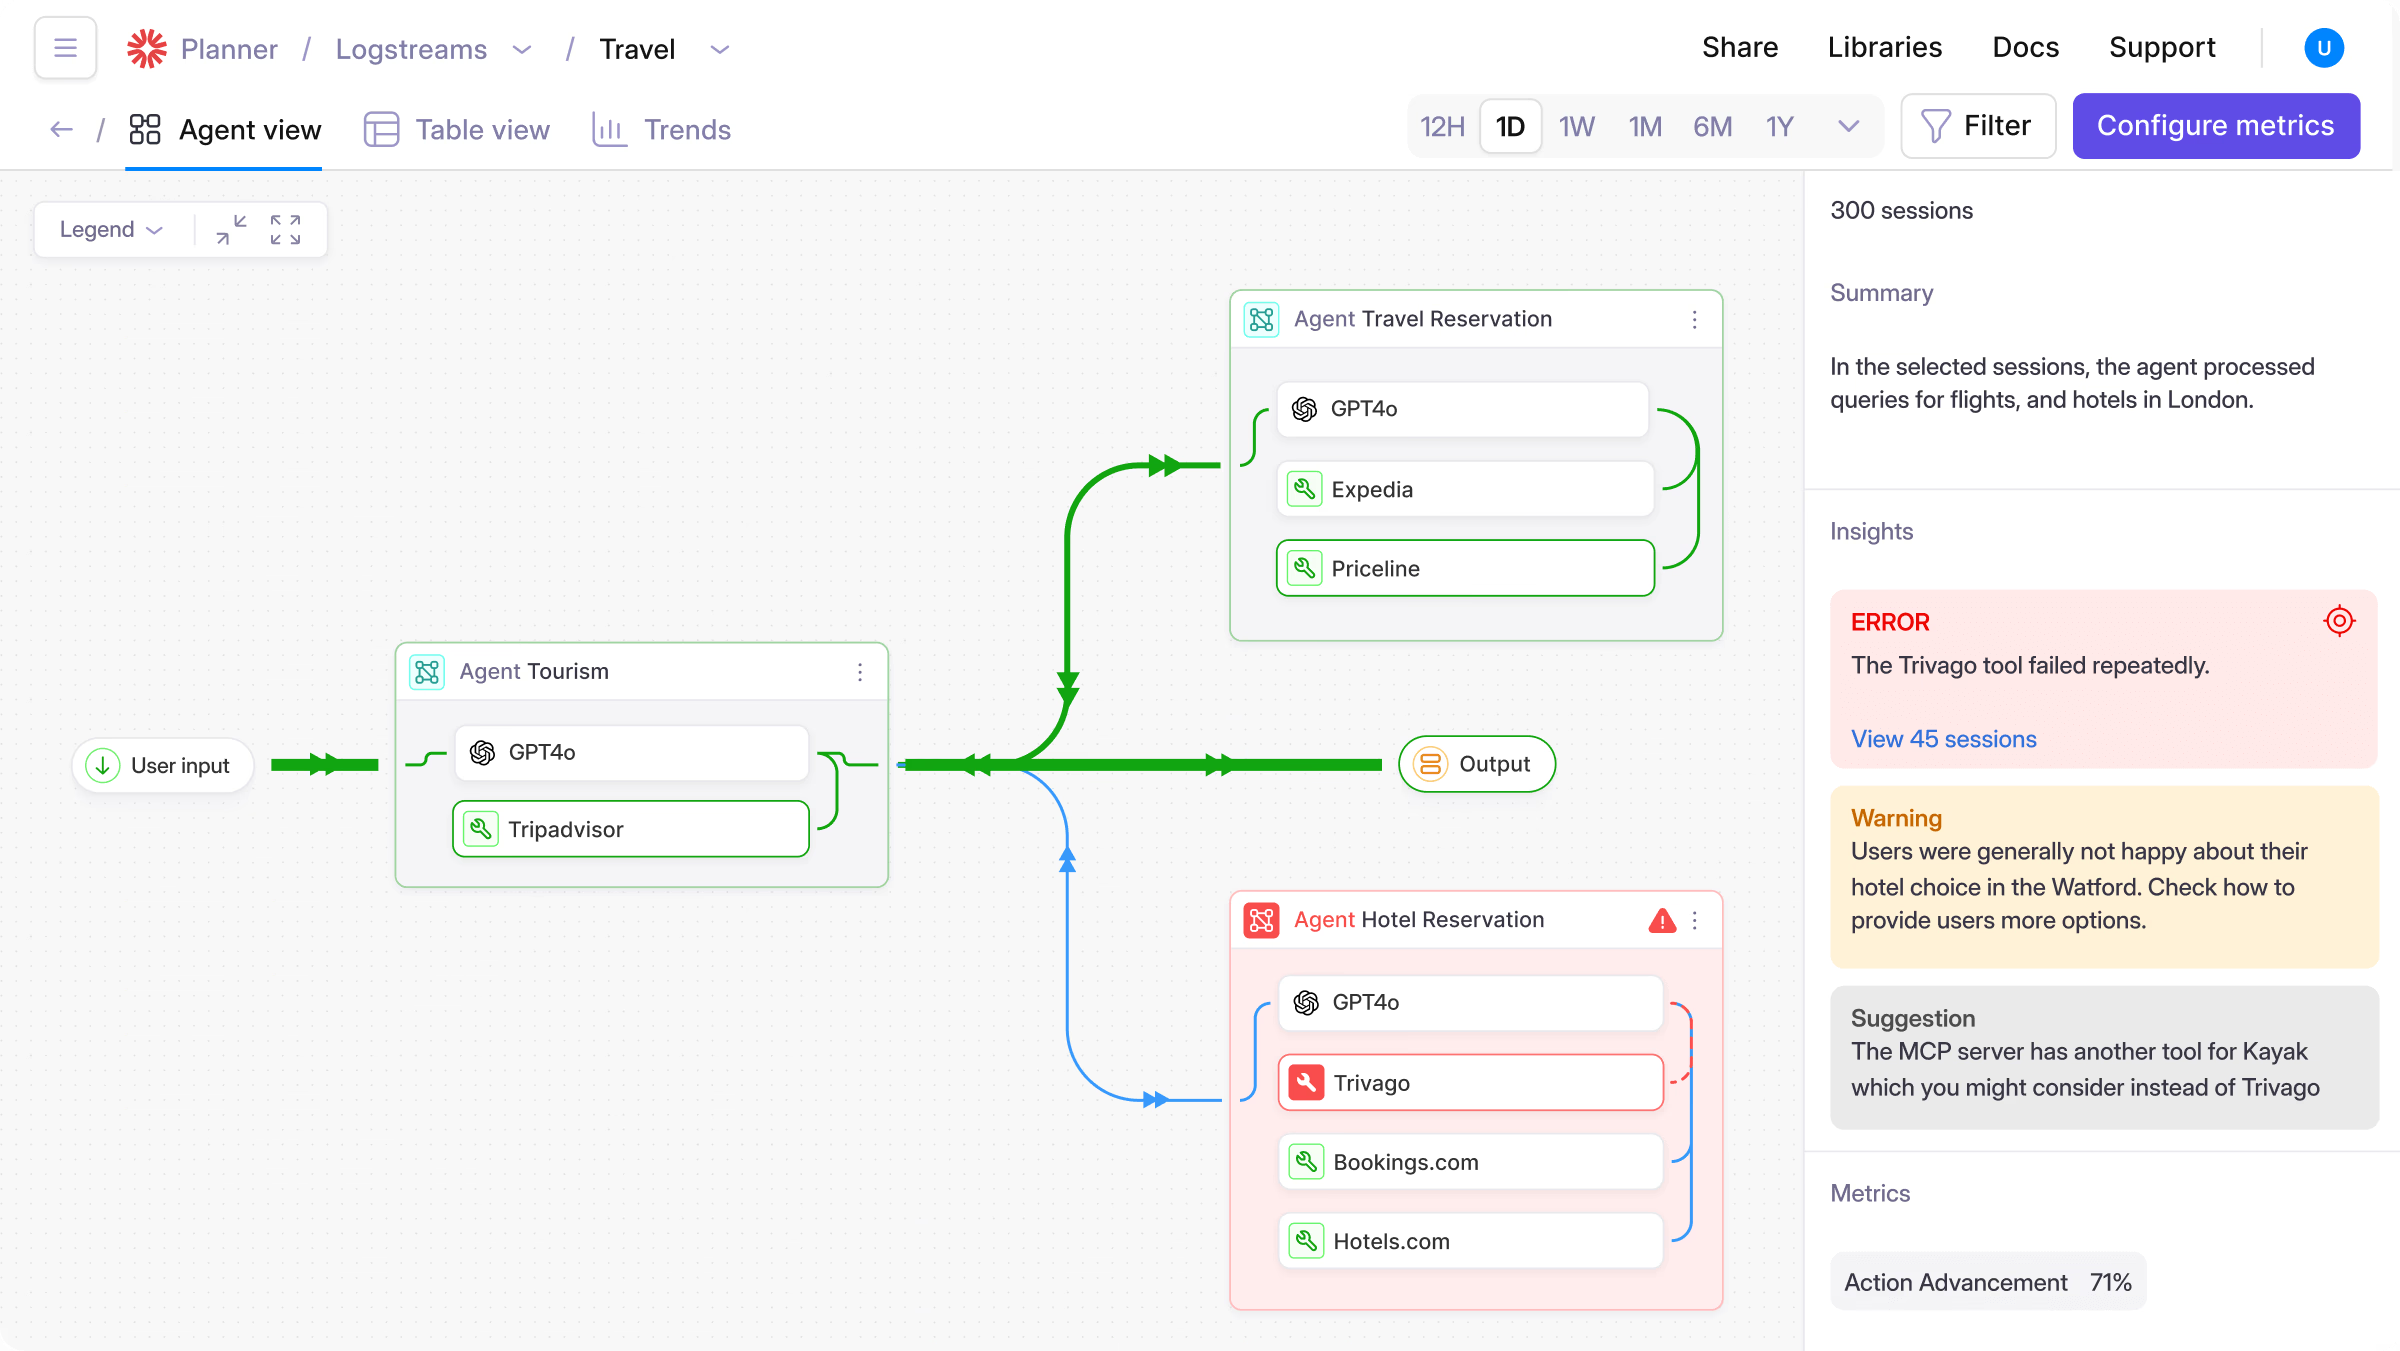
Type: Evaluation and guardrails platform · Price: Free edition, from $100/mo
Galileo focuses on evaluation and guardrails, using its Luna evaluation models to score outputs and turn offline evals into production guardrails. Following Cisco's acquisition, the product is now sold as Splunk Agent Observability, with pricing through Splunk.
That makes it a natural fit for organizations already buying from Splunk, and a heavier purchase for a small team that mainly wants to trace an agent, since paid plans bill annually on span volume. The free edition is part of Splunk Observability Cloud and is capped at 15 hosts.
Pricing: Paid plans start at $100 per month per 1.2 million spans, billed annually, with 500 million Luna tokens and 5 fine-tuning runs a year included. Extra Luna tokens and extended retention are add-ons. It deploys in Splunk Observability Cloud or self-hosted.
Best fit: teams on Splunk that want evals and guardrails in the same purchase.
8. Datadog
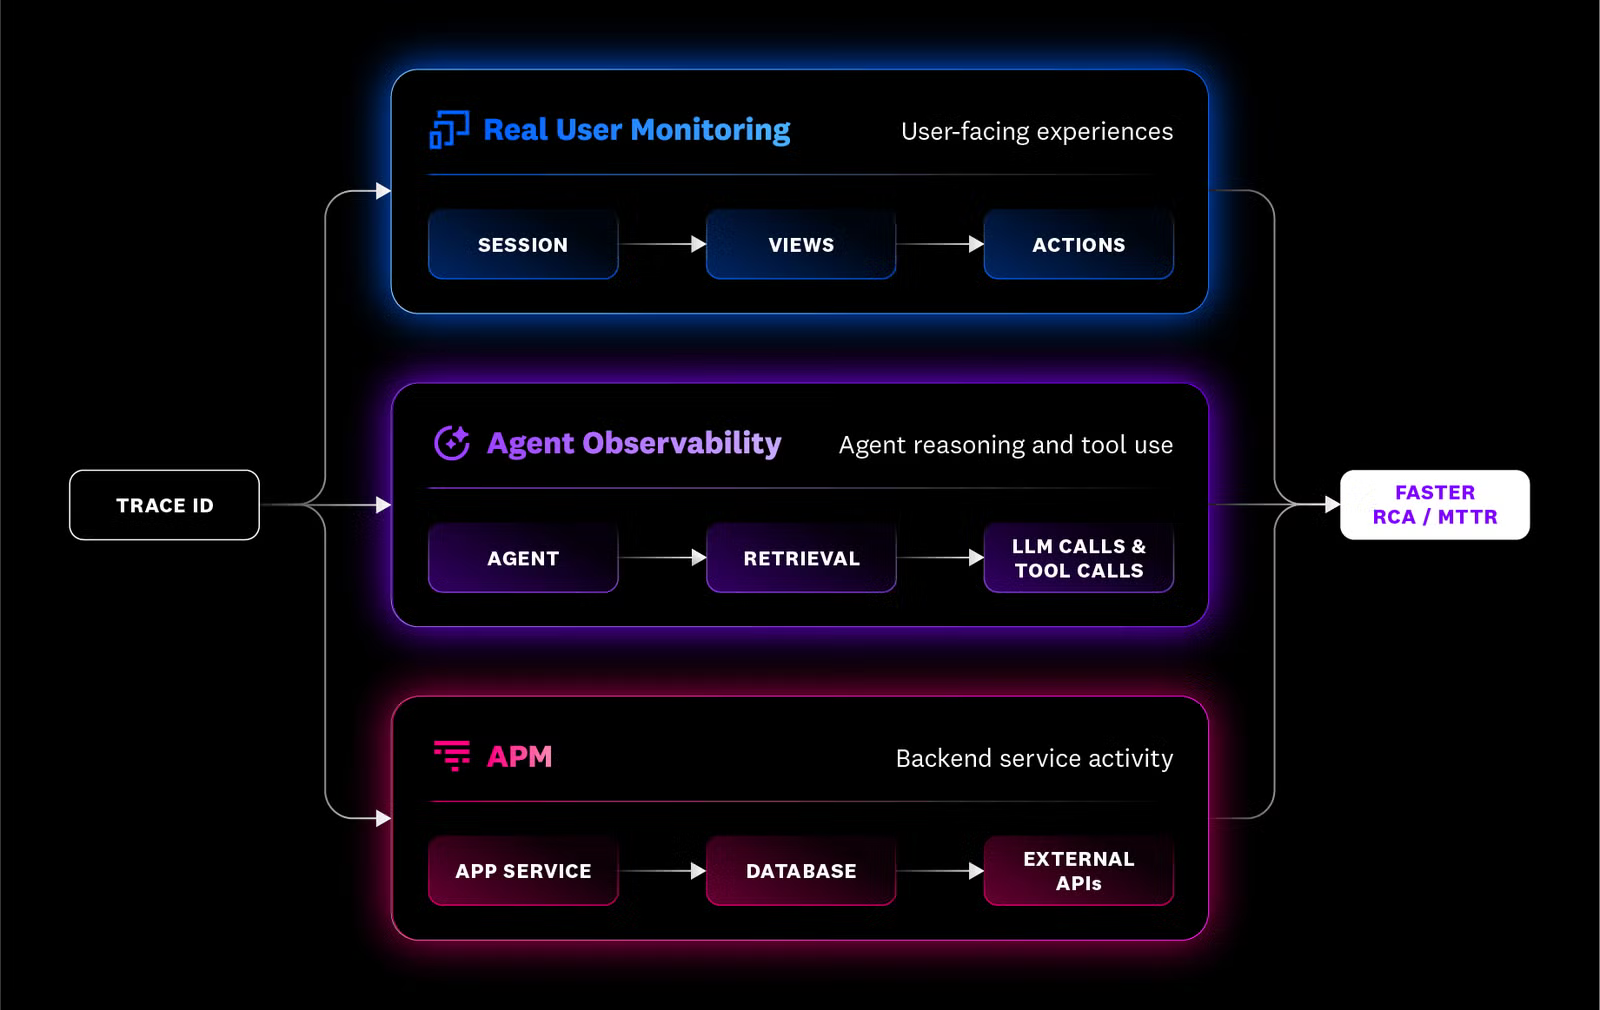
Type: APM platform with an agent observability module · Price: Free tier, Pro $160/mo
For teams already on Datadog, its Agent Observability product (formerly LLM Observability) correlates LLM and agent spans with the rest of your APM traces, so a slow agent caused by a timing-out database shows up in one view. It includes built-in evaluators and custom LLM-as-a-judge evaluations that run across traces and spans.
Only LLM spans bill, while tool, agent, workflow, and retrieval spans are free, so long agent runs cost less than their span count suggests. Evaluations carry no separate fee, but the LLM calls an evaluation makes count as LLM spans, so scoring more of your traffic uses up the allowance faster. Other Datadog products bill separately on top, and that cost structure is a common reason teams look at Datadog alternatives.
Pricing: Free covers up to 40,000 LLM spans a month with 15-day retention. Pro is $160 per month for up to 100,000 LLM spans, with on-demand usage above that and retention add-ons billed per 10,000 LLM spans.
Best fit: teams already standardized on Datadog that want agent telemetry next to their infrastructure data.
9. MLflow
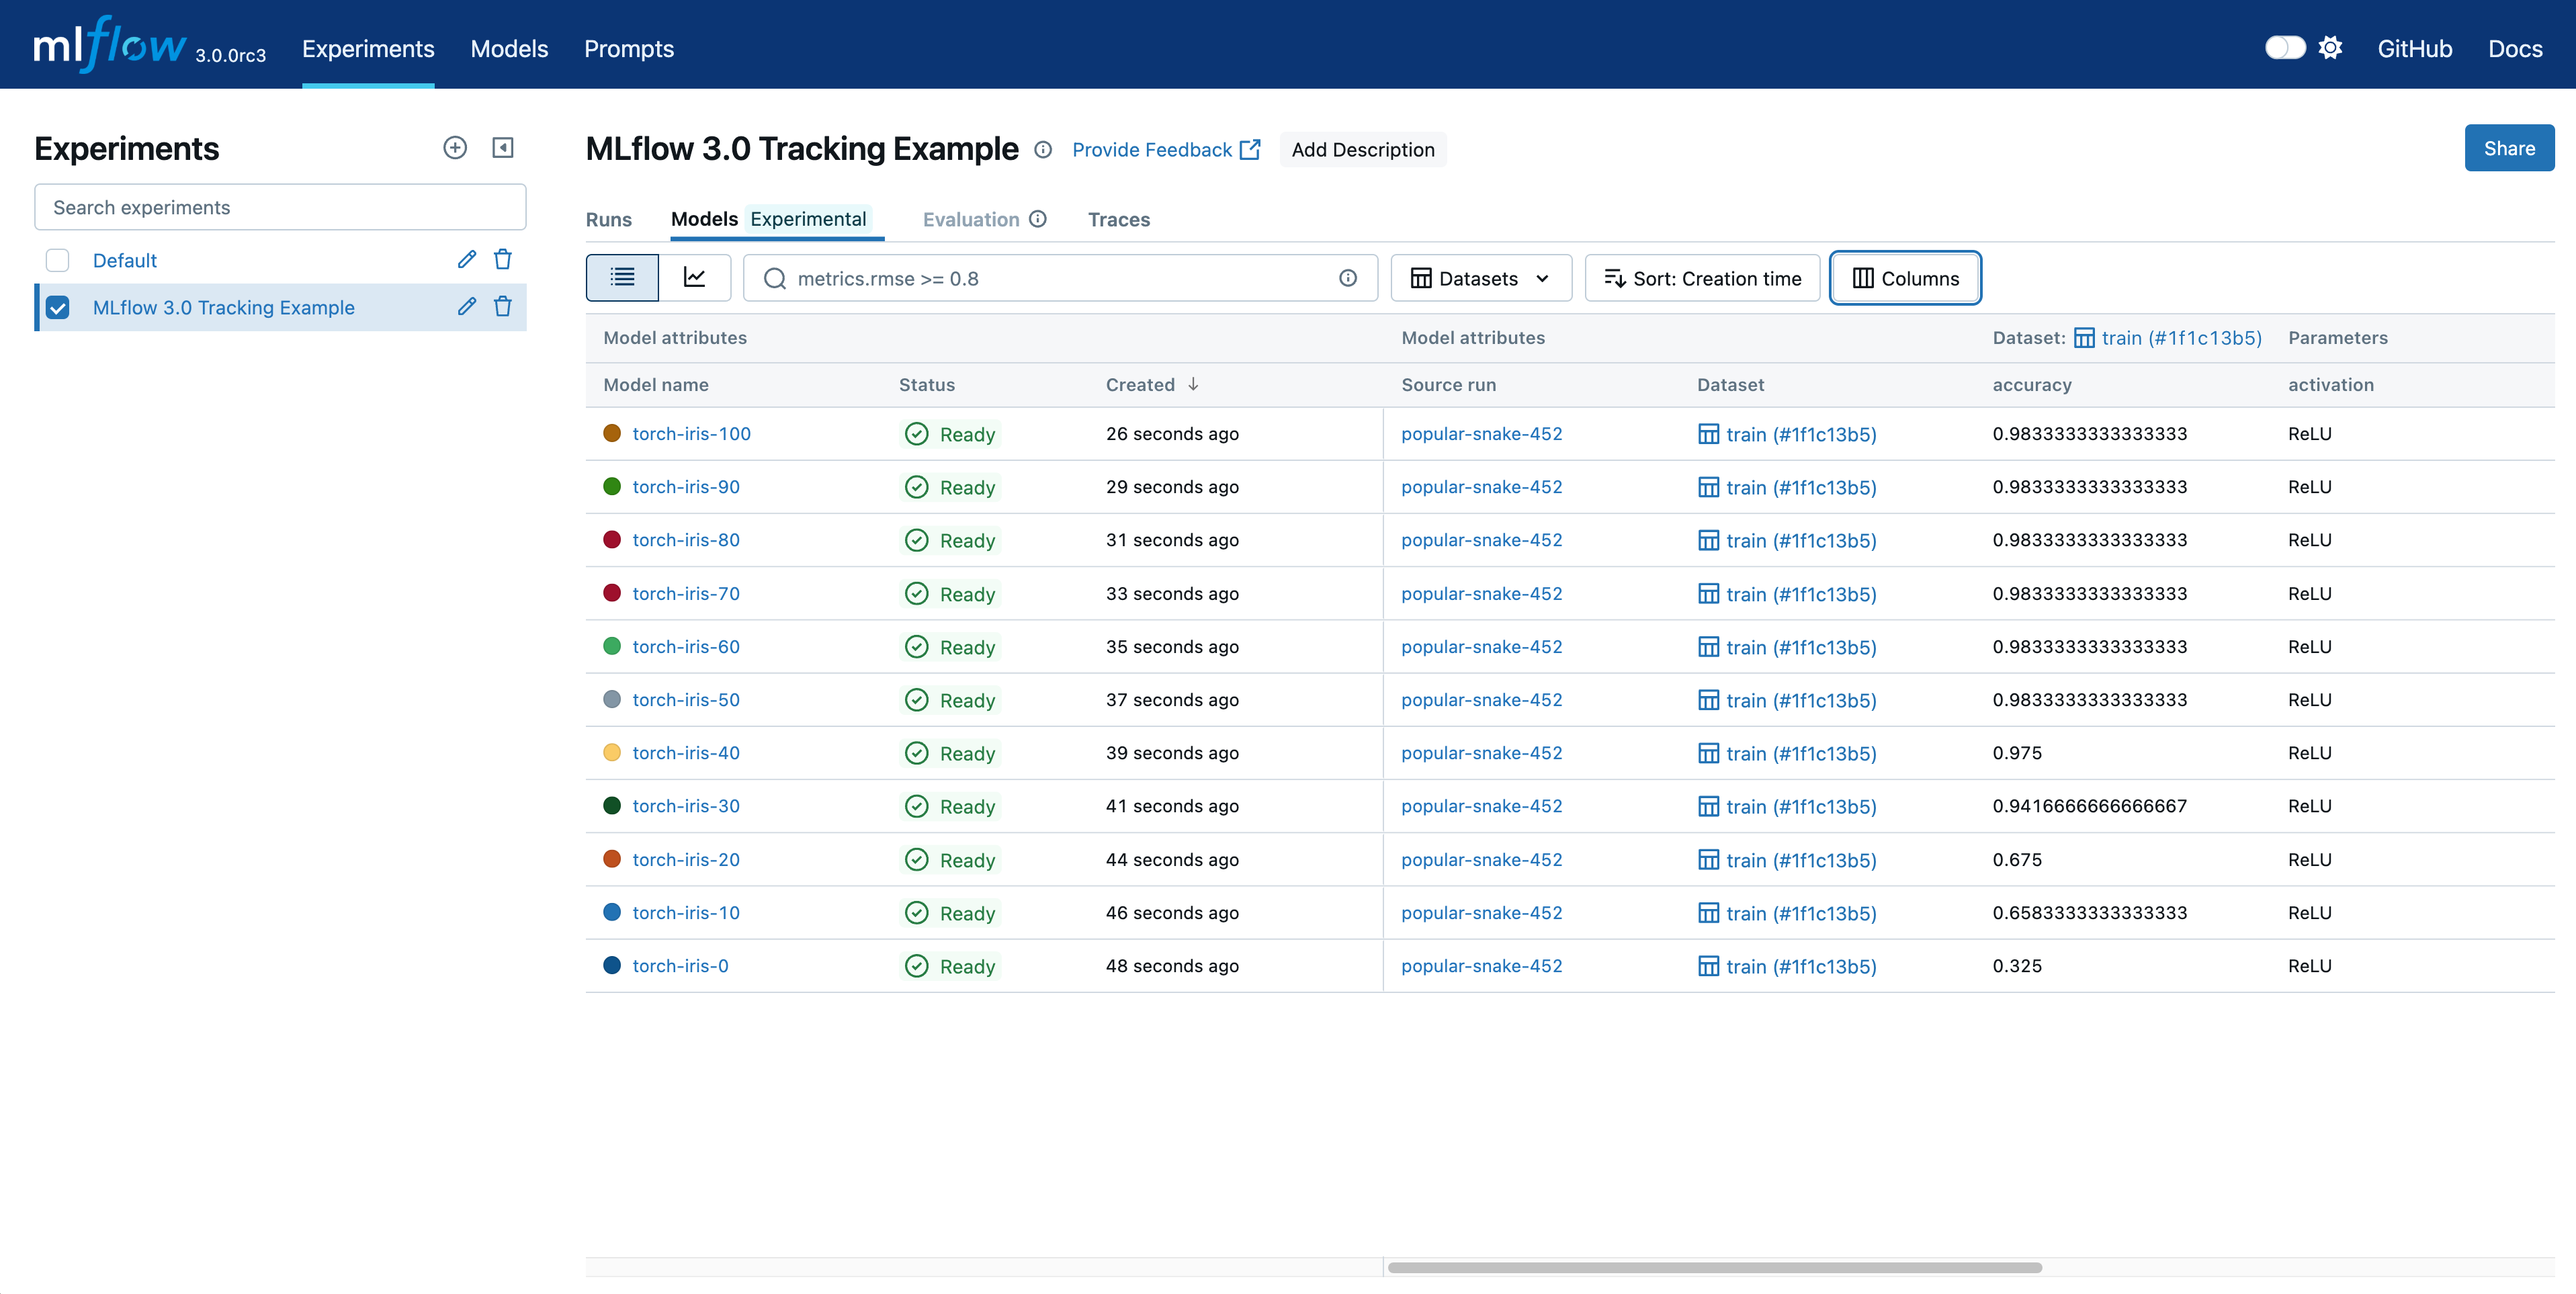
Type: Open-source ML and GenAI platform · Price: Free to self-host
MLflow is an open-source ML platform under the Linux Foundation that extended into GenAI with tracing, evaluation, a prompt registry, and an AI gateway. Tracing is OpenTelemetry-compatible with native support for the GenAI semantic conventions, LLM judges come prebuilt for metrics like relevance, groundedness, and safety or can be written custom, and the gateway handles routing, traffic splitting, and fallback chains.
Self-hosting is free, but your team operates the tracking server, the backend database, and the artifact store. The managed path runs through Databricks and other cloud platforms, which suits teams already on one of them more than teams starting fresh, and the MLflow alternatives mostly trade that operational work for a hosted product.
Pricing: Free and open source under Apache-2.0 to self-host. Managed MLflow is offered through Databricks and other cloud platforms.
Best fit: ML teams already on MLflow or Databricks that are adding LLM and agent workloads.
10. Confident AI
Type: Evaluation platform from the DeepEval team · Price: Free tier, Starter $200/mo
From the team behind DeepEval, the open-source LLM evaluation framework, Confident AI is the hosted platform that adds tracing, prompt versioning, regression testing, custom metrics, and real-time alerting on top. For teams that already write DeepEval tests, it moves the same metrics into a shared workspace.
Pricing is a flat monthly fee per organization rather than per seat, and the jumps between tiers are what to plan around. Real-time alerting starts on Starter at $200 per month, while SSO, RBAC, and SOC 2 arrive on Team at $2,000 per month, so a team with security review requirements might need the higher tier sooner than its traffic does.
Pricing: Free covers 2 seats, 1 project, and 1 GB-month of spans, with extra spans dropped and 5 test runs a week. Starter is $200 per month with unlimited seats, 5 projects, and 5 GB-months of spans, then $1 per GB-month. Team is $2,000 per month. Enterprise adds on-prem deployment and HIPAA.
Best fit: teams already using DeepEval that want hosted dashboards and alerting.
How to Choose an LLM Observability Platform
Shortlisting goes faster when you start from your workload and your constraints rather than from feature lists:
- Start with the run you need to debug - Pick a recent failure and check whether each platform could have shown you the step that caused it. A platform that only sees individual requests won't.
- Decide where scoring happens - If quality checks only run on test sets, you'll catch the regressions you predicted. Scoring live production traffic is what catches drift and edge cases.
- Check what your data requires - PII in prompts, regulated customers, and data residency rules narrow the field before features do, so confirm certifications, masking, and retention controls early.
- Decide whether routing is in scope - With one provider, it isn't. With several, a platform that also routes keeps the model decision and the trace in one record.
- Model cost on span volume - Agents produce many spans per run, and plans meter spans, traces, scores, seats, or processed data. Price each shortlisted platform at the volume your production traffic will generate rather than the volume of your pilot.
- Check who needs to read the output - If only engineers can interpret traces and scores, every quality question waits on engineering, while shared views and readable eval results spread that work across the team.
Whichever way that lands, run a pilot on real production traffic before committing, since trace fidelity and cost at volume are hard to judge from a pricing page. If your workload is mostly multi-step agents, the agent observability practices worth checking a shortlist against go further than this list, and if you only need uptime and cost alerting rather than traces and scores, AI agent monitoring tools are a narrower place to start.
FAQ
What Are LLM Observability Tools?
LLM observability tools capture, monitor, and score what LLM apps and agents do in production. They record each request or agent run as a connected trace of model calls, tool calls, and retrievals, then evaluate the output and track cost and latency alongside it. Most platforms sold as AI observability tools do the same job, and the main difference is scope, since LLM observability centers on the model call while AI observability covers the agent and the system around it.
What's the Best AI Observability Tool?
The best AI observability tool is one that traces the full run, scores output on live traffic, and attributes cost down to the feature or customer, ideally without stitching tools together. Respan does all of that on one platform, with routing built in so the model that served each request is part of the same record. If your team is already standardized on a platform like Datadog or LangSmith, the native option can be the shorter path, as long as it covers live scoring.
Which LLM Observability Tools Are Open Source?
Langfuse (MIT, apart from its enterprise folders), Opik (Apache-2.0), and MLflow (Apache-2.0) are open source and can be self-hosted. Respan's gateway is open source under MIT or Apache-2.0 and sends each request into the hosted platform for tracing and evals. Arize Phoenix is source-available under the Elastic License 2.0 rather than OSI open source, and Confident AI's open-source piece is DeepEval, its evaluation framework, rather than the platform. LangSmith is proprietary, and Braintrust publishes its SDKs and some libraries rather than the platform itself.
Can LLM Observability Tools Monitor Multi-Turn Conversations?
Most platforms here can. Respan groups a conversation's turns into a thread when each request carries the same thread identifier, so you see every turn in order and every step inside each turn as a trace. Langfuse, Arize Phoenix, and Galileo use sessions, LangSmith and Opik use threads, and Braintrust and Confident AI both score conversations across turns, while MLflow's multi-turn judges are still experimental.
How Is LLM Observability Different From APM?
APM monitors infrastructure: latency, error rates, throughput, and resource use. LLM observability monitors what the system produced and how it got there, so it can show which step of an agent run made a bad decision even when every service it touched stayed healthy. It's common to keep APM for infrastructure and add an LLM observability platform for output quality, and some APM vendors, Datadog among them, now offer agent-focused products that sit between the two.
Does an AI Gateway Replace an LLM Observability Platform?
Not on its own. A gateway sees requests passing through it, which gives you cost, latency, and model usage, but it doesn't see the reasoning between calls in an agent run and doesn't evaluate output quality. Platforms that combine both, like Respan, keep the record of which model served a request together with how that request performed. Teams that run routing themselves can keep that record too, since Respan's open-source gateway sends each request into the hosted platform for tracing and evals.