Point Codex or Claude Code at a repo and ask for a fix, and both will read the code, edit files, run your tests, and report back. On paper the two agents do the same job.
Where they differ is in the working details: how each one explores a codebase before it edits, how often it finishes a multi-file task on the first attempt, how locked down it is by default, and how much of its behavior you can script.
Since both can do the job, the better agent is the one that reliably finishes your team's kind of work at a cost you can live with. That's something you can measure on your own code instead of inferring it from a leaderboard.
For most engineering teams, the Codex vs Claude Code decision in 2026 comes down to which agent handles your repo and your tasks better.
Codex vs Claude Code: Which Is Better in 2026?
Neither is better across the board. Codex is cheaper to start, with limited access on the Free plan and on Go at $8 a month, and a sandbox that's on by default. Claude Code runs Opus 5.5 on every paid plan and offers extensive customization through hooks, skills, subagents, and plugins. At the top tier, the two agents' Terminal-Bench scores sit within half a point.
Where each one pulls ahead depends on the work. Codex pairs a cheaper recommended model with GitHub code review on Plus and above, which suits teams that hand off well-scoped tasks and review the results in pull requests. Claude Code exposes hooks, skills, subagents, and plugins, and in Respan's trace-level testing it finished more multi-file tasks, so it tends to fit repo-wide changes where the agent needs to understand the code before editing it.
| Claude Code | Codex | |
|---|---|---|
| Recommended model | Opus 5.5 (default) | GPT-6 Sol |
| Higher-capability model | Fable 5.1 | GPT-6 Astra |
| Cheapest paid plan | Pro, $20/mo | Go, $8/mo (limited) |
| Top individual plan | Max 20x, $200/mo | Pro 20x, $200/mo |
| OS sandbox | Opt-in | On by default |
| Instructions file | CLAUDE.md (reads AGENTS.md) | AGENTS.md |
Codex vs Claude Code Models
Claude Code Models in 2026
Claude Code runs Anthropic's Claude models only, and you switch between them with the /model command. Opus 5.5, Sonnet 5, and Fable 5.1 all get a 1M-token context window on every plan, Pro included.
- Claude Opus 5.5 - The default on Pro, Max, Team, Enterprise, and the Anthropic API since its September 22, 2026 release.
- Claude Fable 5.1 - A higher-capability option that's never the default, selected with
/model fable. On Max and premium Team or Enterprise seats, up to half of your weekly usage can go to Fable at no extra cost, while Pro and standard seats pay for it with usage credits. - Claude Sonnet 5 - A lower-cost option at half of Opus 5.5's API price.
- Claude Haiku 4.5 - The lowest-priced Claude model at $1 input and $5 output per million tokens, with a 200K-token context window.
Fable 5.1 bills at $10 input and $50 output per million tokens through the API, 2.5 times Opus 5.5's rate, so it's worth checking how Opus 5.5 compares to Fable 5.1 before switching a long session over.
Codex Models in 2026
Codex runs OpenAI's models, and the one you pick also sets how quickly you use up your plan, since each model gets its own usage range per five-hour window.
- GPT-6 Sol - OpenAI's recommended model for Codex.
- GPT-6 Astra - Sits above Sol as the higher-capability tier.
- GPT-6 Luna - The efficient tier, and the suggested model on the Free and Go plans.
- GPT-5.6 Sol - Still selectable from the previous Sol generation, along with GPT-5.6 Luna.
- GPT-5.4 - An older flagship still offered in Codex, alongside GPT-5.4 mini.
Choosing among the three GPT-6 tiers means trading capability against how fast a model spends your limits, which is the core of GPT-6 Sol vs Luna vs Astra. GPT-5.5 is also still available but retires on October 14, 2026, so any scripts or team defaults pinned to it will need a new model before then. Reasoning effort runs from Low through Max, plus an Ultra mode that delegates work across subagents.
Claude Code vs Codex Pricing
At the subscription level, the two price ladders line up almost exactly. The differences are at the bottom and in how usage gets counted.
| Plan | Claude Code | Codex |
|---|---|---|
| Free | Not included | Limited trial access |
| $8/mo | No equivalent | Go (limited access) |
| $20/mo | Pro | Plus |
| $100/mo | Max 5x | Pro 5x |
| $200/mo | Max 20x | Pro 20x |
| Team seat, annual | $20 standard, $100 premium | $20 standard, $100 premium |
| Enterprise | $20/seat + API usage | Custom pricing |
Claude Code Pricing
The free Claude plan doesn't include Claude Code. Pro costs $20 a month ($17 a month billed annually), Max 5x costs $100, and Max 20x costs $200. Pro and Max use a five-hour session limit plus a weekly limit, and those limits are shared across Claude and Claude Code, so a heavy day of chat leaves less room for coding.
For teams, standard seats cost $20 per user per month billed annually or $25 monthly, and premium seats with five times the usage cost $100 or $125. Enterprise charges $20 per seat billed annually plus usage at API rates, which means spend grows with how much the team actually runs the agent.
Pay-as-you-go API access is the other route. Opus 5.5 costs $4 input and $20 output per million tokens, Sonnet 5 costs $2 and $10, Haiku 4.5 costs $1 and $5, and Fable 5.1 costs $10 and $50.
Codex Pricing
Every ChatGPT plan includes Codex, though Free and Go ($8 a month in the US) come with limited trial access. Plus costs $20 a month, Pro 5x costs $100, and Pro 20x costs $200. Business seats cost $20 per user per month billed annually or $25 monthly, with a $100 premium seat that adds five times the usage and drops the five-hour limit. Enterprise pricing is custom.
Usage limits are set per model, per five-hour window, and weekly limits may also apply. On Plus, GPT-6 Sol gets 15 to 150 local messages per window and GPT-6 Astra gets 5 to 45, while Pro 20x raises Sol to 300 to 3,000. The ranges are wide because context size, reasoning effort, and tool use all change what a single message costs, and cloud chats draw down the limit faster than local messages do.
Through the API, GPT-6 Sol costs $2 input and $10 output per million tokens, GPT-6 Astra costs $10 and $50, and GPT-6 Luna costs $0.10 and $0.50. Long-context requests bill at higher rates, so large repos can cost more per token than the headline price.
Codex vs Claude Code Performance
Claude Code Performance
On Terminal-Bench 4.0, which runs coding agents through 66 terminal tasks, Claude Code with Fable 5.1 scores 57.9%. With Opus 5 it scores 53.9%, and with Sonnet 5 it drops to 12.4%. Opus 5.5 has no entry yet, so Claude Code's default model is still unscored there.
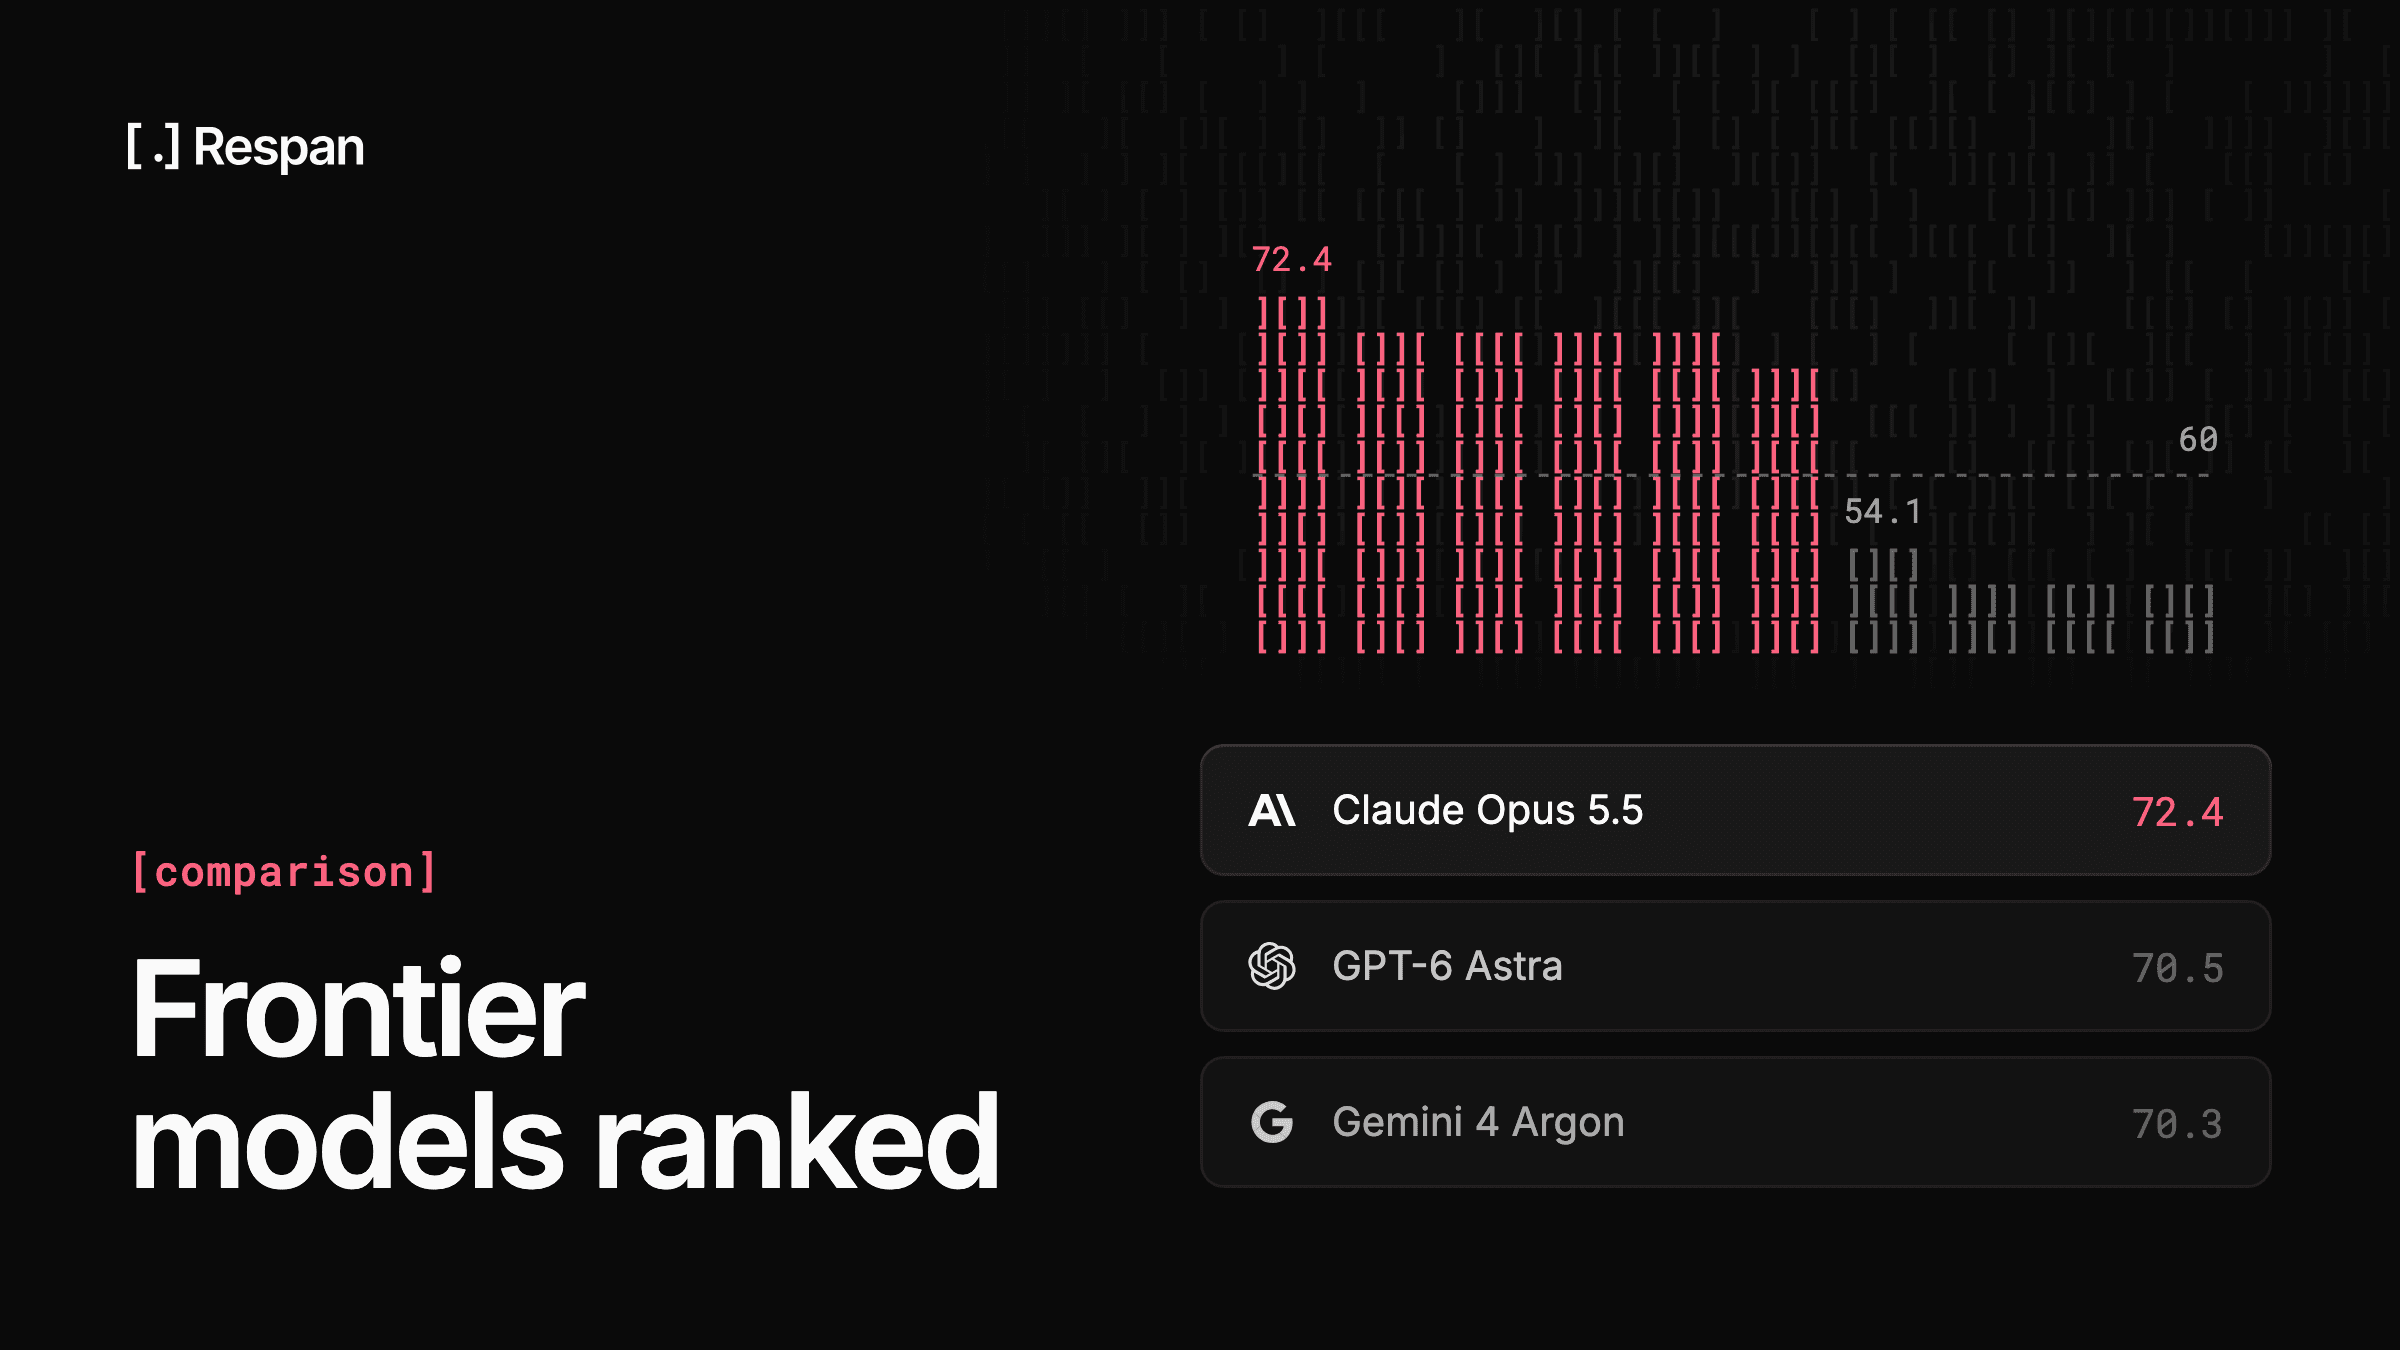
Opus 5.5 does show up on Arena's coding leaderboard, where developers vote on model outputs for coding prompts. As of September 23, 2026, it ranks first at max effort with a score of 1818, ahead of GPT-6 Astra. Keep in mind that Arena ranks the model rather than the agent wrapped around it.
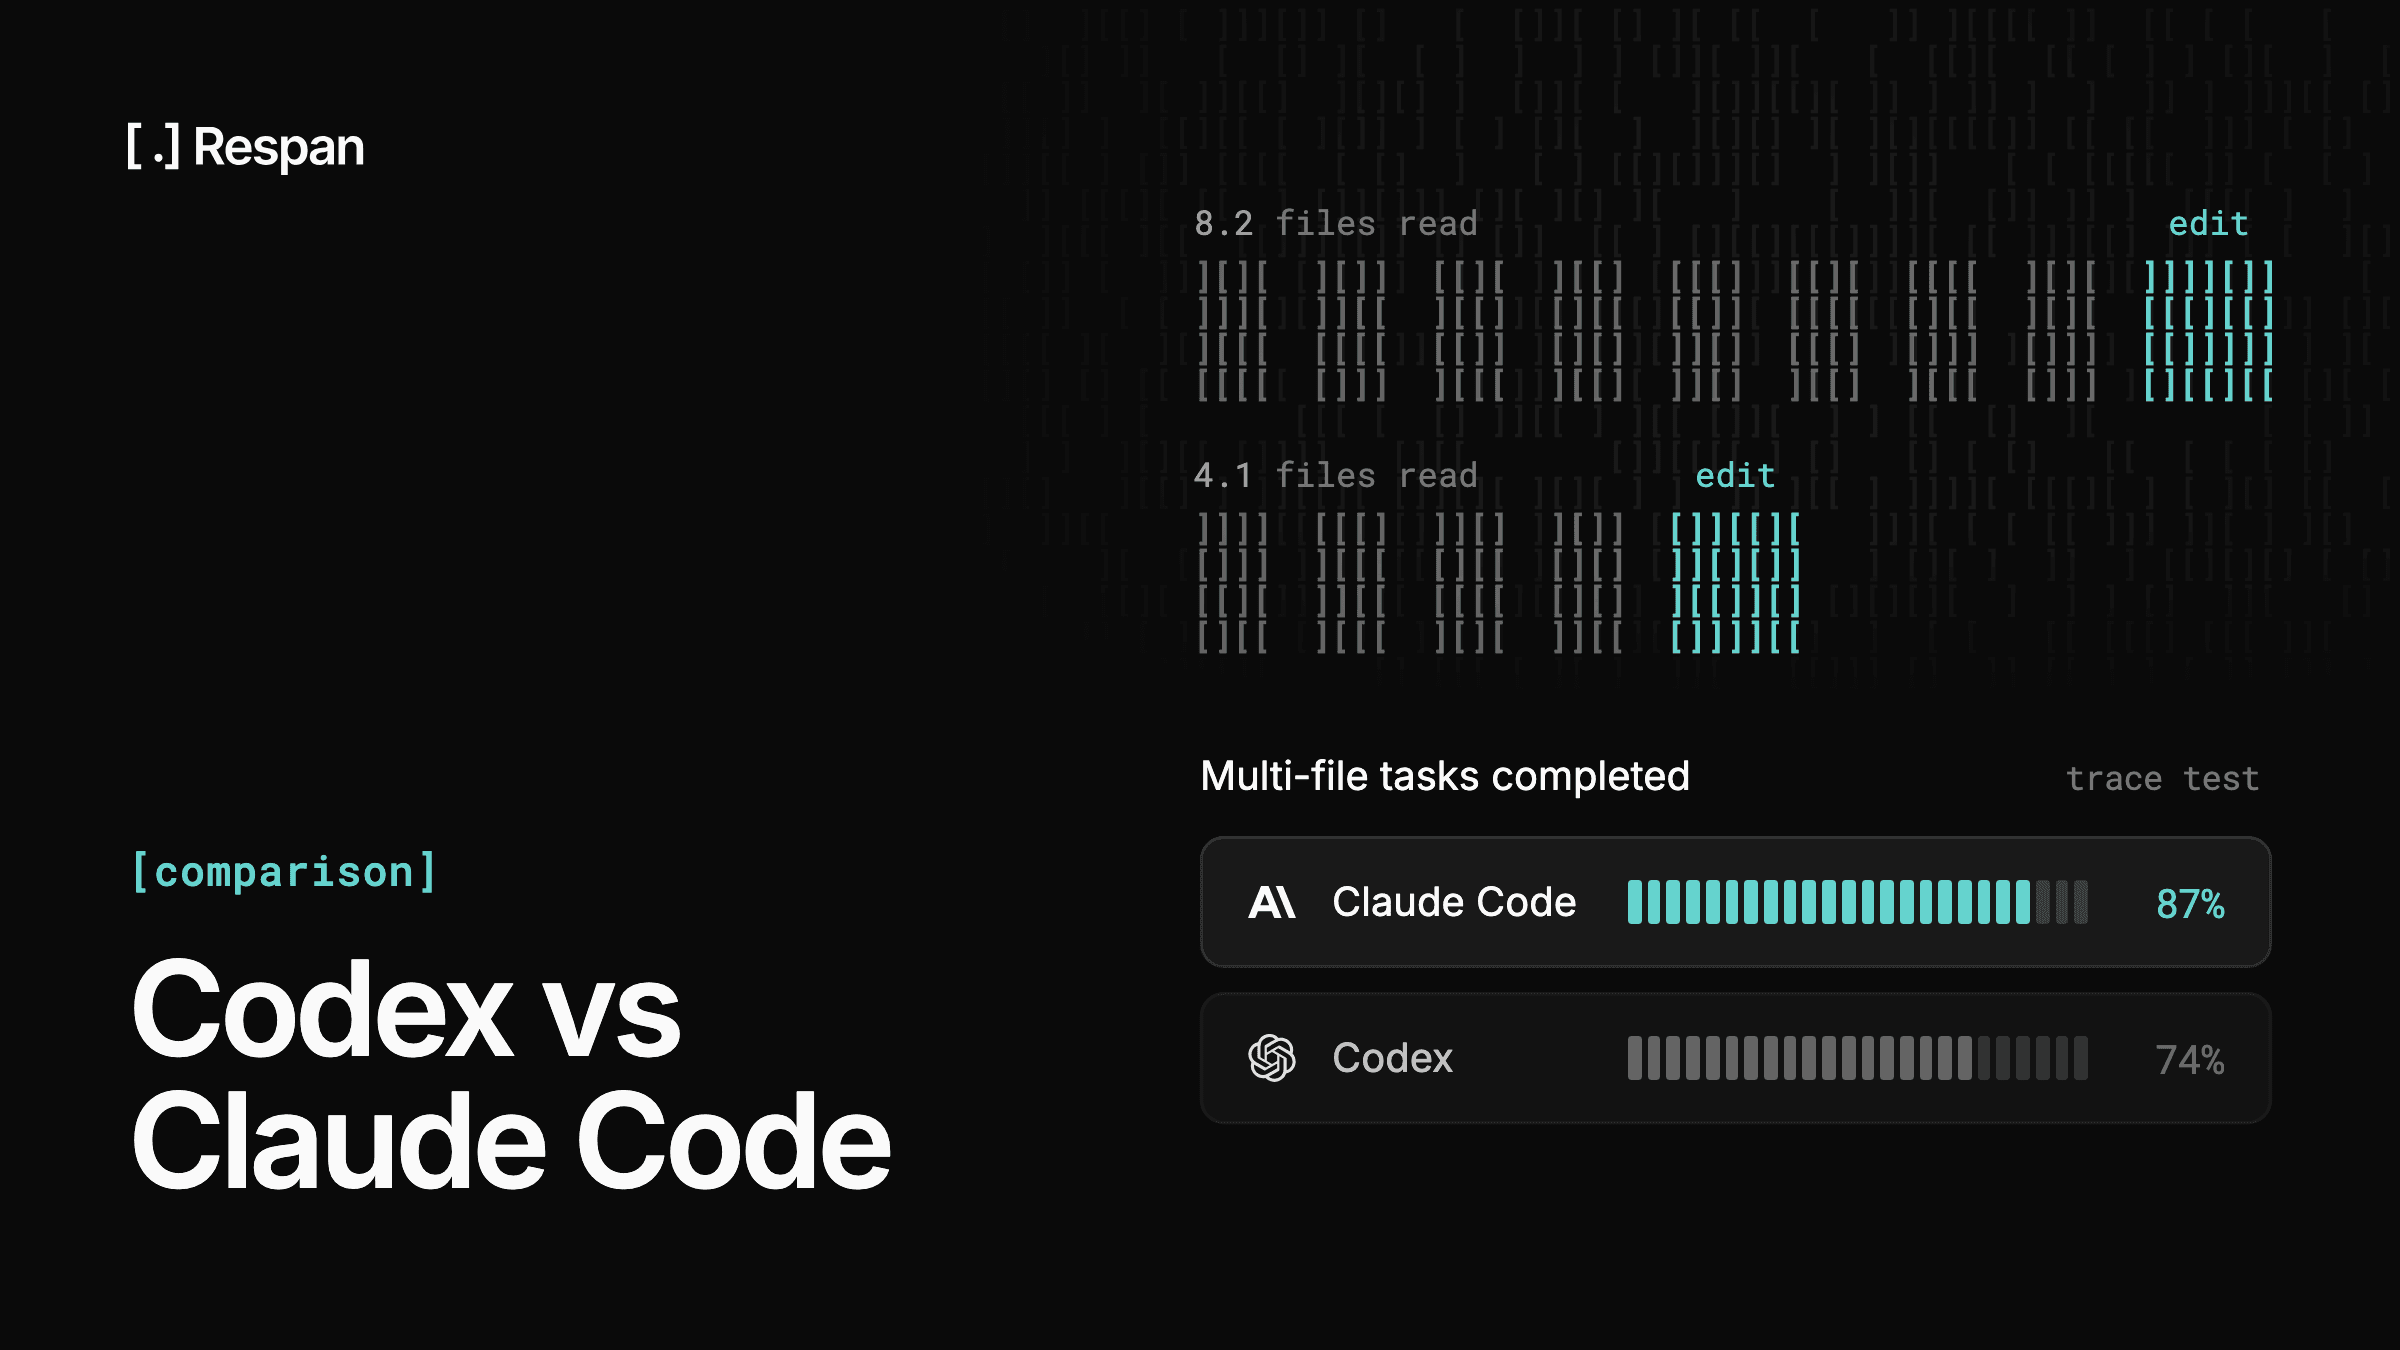
Behavior matters as much as scores. In Respan's trace-level comparison of Claude Code and Codex, run in April 2026 on earlier model versions, Claude Code read an average of 8.2 files before its first write and completed 87% of multi-file tasks. That front-loaded reading is the likely source of both its higher completion rate and its higher token count.
Codex Performance
Codex with GPT-6 Astra scores 58.2% on Terminal-Bench 4.0. The 0.3-point lead over Claude Code with Fable 5.1 sits inside both entries' margins of error. With GPT-5.6 Sol, Codex scores 37.3%, and GPT-6 Sol, the model OpenAI recommends for Codex, isn't on the leaderboard yet. On Arena's coding leaderboard at max effort, GPT-6 Astra scores 1792 and GPT-6 Sol scores 1686.
The same April trace test showed Codex working differently. It read 4.1 files before its first write, finished with a median of 17,900 tokens per task against Claude Code's 22,600, and ran faster at 41 seconds median wall-clock time against 48. It also needed more attempts to recover from errors (1.8 against 1.3) and completed 74% of multi-file tasks, which points it toward scoped tasks where speed matters more than repo-wide context.
How Codex and Claude Code Differ in Practice
Token Usage and Cost per Task
A model's per-token price is only half the cost of a task. The other half is how many tokens the agent spends finishing it.
| Claude Code | Codex | |
|---|---|---|
| Recommended model (API) | Opus 5.5, $4/$20 | GPT-6 Sol, $2/$10 |
| Higher-capability model (API) | Fable 5.1, $10/$50 | GPT-6 Astra, $10/$50 |
| Cached input, recommended model | $0.20 per 1M | $0.20 per 1M |
| Median tokens per task* | 22,600 | 17,900 |
| Multi-file completion* | 87% | 74% |
*From Respan's April 2026 trace test, run on earlier model versions.
At API rates with the recommended models, Codex costs less per task on both price and token count. Claude Code's extra reading bought a higher multi-file completion rate, though, and a failed task that has to be rerun can wipe out those savings. Cached input also narrows the gap on repeated reads, one of several discounts that can make OpenAI vs Anthropic pricing closer in practice than the list rates suggest.
On a subscription, the same math shows up as limits instead: an agent that reads more per task can hit its five-hour window sooner.
Where They Run: Codex CLI, Cloud, and IDE vs Claude Code
In the terminal, Codex CLI and Claude Code work the same way: you point the agent at a repo, and it reads, edits, and runs commands on your machine. The differences are in where else each one runs.
- Claude Code - Terminal, VS Code (the extension also installs in Cursor), JetBrains, a desktop app for macOS and Windows, claude.ai/code on the web, and the Claude mobile app, plus Slack, Chrome, and GitHub Actions integrations. Cloud sessions run in Anthropic-managed virtual machines and share your plan's limits.
- Codex - The open-source CLI, an extension for VS Code, Cursor, and Windsurf, JetBrains and Xcode integrations, a desktop app launched with
codex app, chatgpt.com/codex on the web, and the ChatGPT mobile app in preview. Cloud tasks run in OpenAI's environment, with network access only during setup.
Both agents now cover the terminal, the major IDEs, desktop, web, and mobile, so where they run is rarely what decides it. The practical difference is the account: Codex sits under your ChatGPT login, Claude Code under your Claude one.
Project Instructions and Customization: AGENTS.md vs CLAUDE.md
Both agents take instructions from a file in the repo, and a team running both can share a single AGENTS.md.
- Claude Code - Reads CLAUDE.md at the managed, user, project, and local levels with
@pathimports. It reads AGENTS.md natively when no CLAUDE.md exists, and a project setting makes it read both. You customize it through hooks, skills, subagents, plugins, MCP servers, a headless-pmode for CI, and the Agent SDK. - Codex - Reads AGENTS.md, which can also hold the review guidelines Codex applies to pull requests. MCP servers are configured in
~/.codex/config.toml, a notify hook fires on events, and Ultra reasoning mode spreads work across subagents.
Keep shared rules in AGENTS.md, and add a CLAUDE.md only for instructions specific to Claude.
Sandboxing and Permissions
Both agents can run inside an OS-level sandbox. The difference is whether it's on when a session starts.
| Claude Code | Codex | |
|---|---|---|
| OS sandbox | Opt-in with /sandbox | On by default |
| macOS | Seatbelt | Seatbelt |
| Linux | bubblewrap | bubblewrap + seccomp |
| Windows | WSL2 only | WSL2 or native |
| Network by default | Blocked when sandboxed | Off locally |
Beyond the default workspace-write mode, Codex has read-only for folders not under version control and danger-full-access with no sandbox, controlled by the on-request, never, and granular approval policies. Claude Code's permission modes are default, acceptEdits, plan, auto, dontAsk, and bypassPermissions. Auto mode is the starting mode on Pro, Max, and Team, and it uses a classifier model to review tool calls before they run.
Codex is locked down out of the box, while Claude Code's sandbox has to be switched on, although admins can enforce it for a whole organization through managed settings.
Code Review and GitHub Workflow
Both agents review pull requests on GitHub, but they're set up and billed differently.
- Codex - Comment
@codex review, or turn on automatic reviews for every new pull request. It flags only P0 and P1 issues and takes its focus from the comment or from review guidelines in AGENTS.md. It's available on Plus, Pro, Business, and Enterprise, and reviews draw on their own usage rather than your coding limits. - Claude Code - A GitHub Action responds to
@claudementions in pull requests and issues. It authenticates with an API key, a subscription token, or a cloud provider, and it costs your Actions minutes plus tokens. A managed Code Review (@claude review) is in research preview on Team and Enterprise and billed through usage credits, and on other plans/code-reviewruns locally.
Individual developers get pull request review included in Codex's $20 plan, while teams that want review they can script inside their own CI get more flexibility from Claude Code's Action.
Pros and Cons
Claude Code Pros and Cons
Claude Code's strengths come from its model defaults and its extension points, while most of its drawbacks trace back to how Anthropic meters usage.
Pros
- Opus 5.5 on every paid plan - Pro subscribers get the same default model as Max and Enterprise, with a 1M-token context window.
- Customization - Hooks, skills, subagents, plugins, and MCP servers let you script how the agent works, from blocking a risky command to running a linter before every commit.
- AGENTS.md support - Repos already using AGENTS.md work without a second instructions file, as long as no CLAUDE.md exists.
- Surface coverage - The same agent runs in the terminal, VS Code, JetBrains, a desktop app, the web, and the Claude mobile app.
Cons
- No free access - Claude Code starts at the $20 Pro plan.
- Shared limits - Chat and coding draw from the same five-hour and weekly limits on Pro and Max.
- Fable 5.1 costs extra on lower tiers - Pro and standard seats pay usage credits to use it.
- Opt-in sandbox - OS-level sandboxing exists, but you have to turn it on with
/sandboxor through managed settings. - Claude models only - Anthropic doesn't support routing Claude Code to non-Claude models.
If your team already pays for Max or premium seats, most of these drawbacks shrink, because Fable 5.1 is included and the limits get more headroom.
Codex Pros and Cons
Codex is easier to start with and more locked down by default. Its tradeoffs mostly come down to predictability.
Pros
- Low entry price - Limited access starts on the Free plan and on Go at $8 a month.
- Sandboxed by default - Local sessions run with workspace-write permissions and network access off, and cloud tasks run offline once setup finishes.
- Open-source CLI - The Codex CLI is Apache-2.0 licensed on GitHub.
- GitHub review on Plus and above -
@codex reviewflags P0 and P1 issues in pull requests without a separate product. - Cheaper recommended model - GPT-6 Sol costs half of Opus 5.5 per token through the API.
Cons
- Hard-to-forecast limits - A range like 15 to 150 messages per window makes it difficult to plan a heavy day.
- Little Astra on Plus - GPT-6 Astra gets 5 to 45 local messages per five-hour window on the $20 plan.
- Model retirements - GPT-5.5 retires on October 14, 2026, so pinned defaults need updating.
- Cloud chats cost more - They draw down plan limits faster than local messages.
For teams that mostly run GPT-6 Sol and review changes through GitHub, the limit uncertainty is the main cost to plan around.
Should I Use Codex or Claude Code?
The right agent depends less on which lab you prefer and more on what you hand it and how your team already works. Most teams will find their answer in one of the situations below.
Use Claude Code when:
- The work spans the repo - Refactors and features that touch many files benefit from an agent that reads widely before it edits, and Claude Code completed more multi-file tasks in Respan's trace testing.
- You want to shape the agent's behavior - Hooks, skills, subagents, and plugins let you enforce checks, block commands, or package team workflows.
- You already pay for Max or premium seats - Fable 5.1 is included in your usage on those plans, on top of Opus 5.5 as the default.
Use Codex when:
- You're watching cost - Go at $8 a month gets you started, and GPT-6 Sol costs half of Opus 5.5 per token when you move to the API.
- Review happens in pull requests -
@codex reviewon Plus and above flags high-priority issues without extra setup. - The repo is sensitive - Sessions start sandboxed with network access off, so you don't have to rely on someone remembering to enable it.
- Tasks are well-scoped - Codex finished faster and used fewer tokens per task in the same trace test, which fits clearly specified bug fixes and small features.
- Your company already runs ChatGPT Business or Enterprise - Codex comes with the seats you have.
If your team's work falls into both lists, running both agents on a handful of representative tasks and comparing cost per completed task will settle it faster than any leaderboard.
Compare Claude and GPT Models in Your Own Agents with Respan
The Claude versus GPT question doesn't end with your coding agent. The agents your team ships make the same choice on every request, and a leaderboard built on someone else's tasks can't tell you which model earns its price on yours.
Respan lets you route, observe, and evaluate every LLM call from one place. Respan's LLM gateway gives you one endpoint for 1,000+ models, so moving a workload from Opus 5.5 to GPT-6 Sol is a change to the model string.
- Test on real traffic - Build a dataset by sampling your production logs, then run it through each model with the same evaluators.
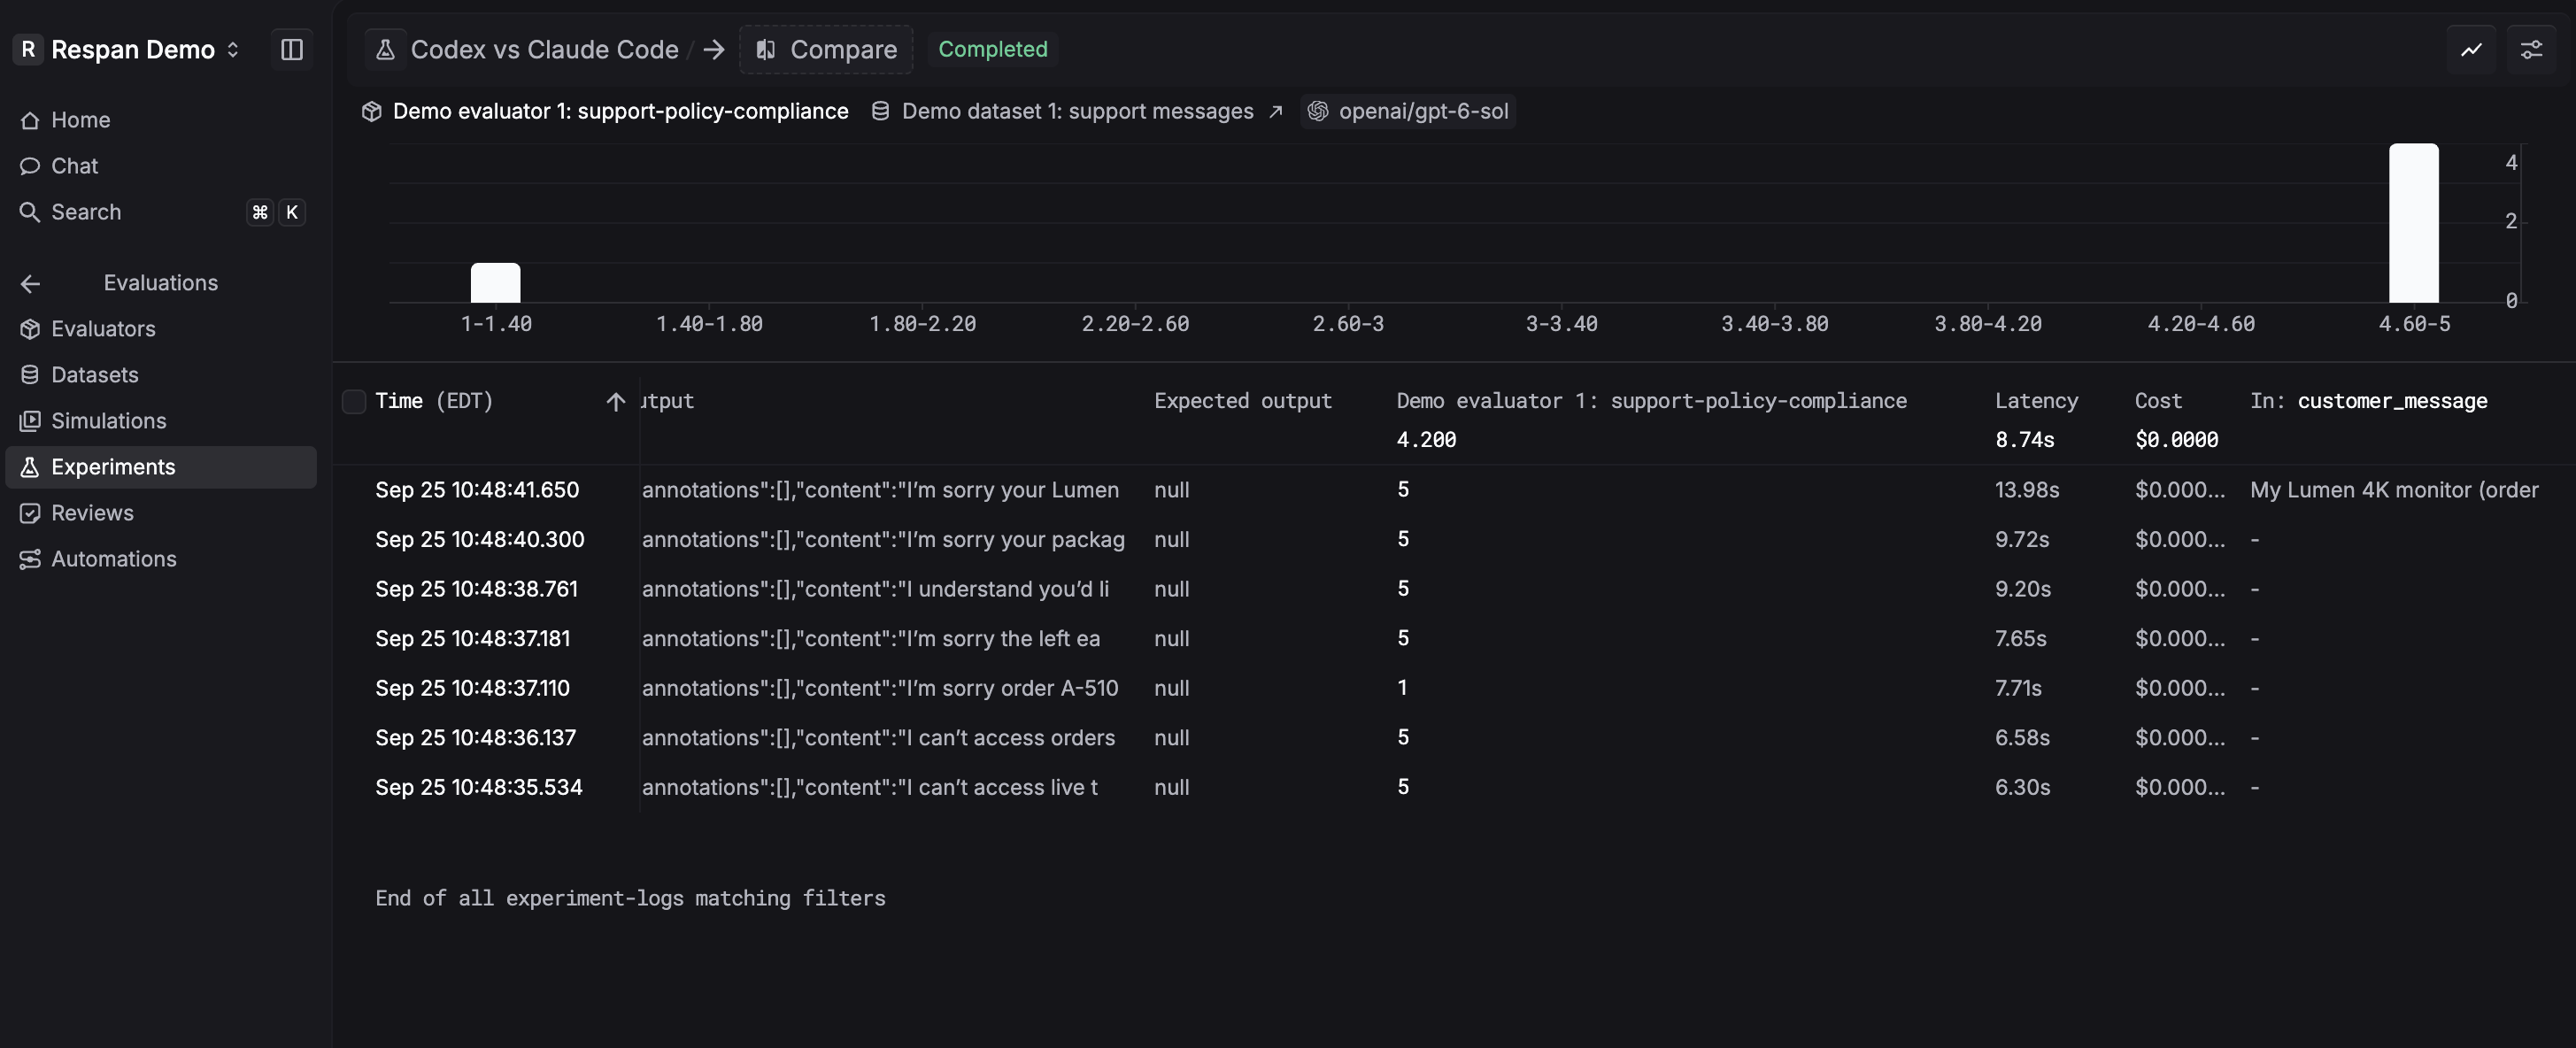
- Compare scores side by side - Respan evals chart each model's score distribution next to the other's, and any row opens the full trace behind it.
- See cost per model - Spend breaks down by model, API key, and customer, and limits can warn or block before a bill surprises anyone.
- Fall back automatically - When a provider errors or rate-limits, traffic reroutes to the fallback model you configured.
The same platform also covers the coding agents themselves. Running respan integrate claude-code or respan integrate codex-cli from the Respan CLI sends each session to Respan as a trace, with prompts, tool calls, and token counts, so you can compare cost per task on your own repo. Respan's MCP server also lets Claude Code or Codex query your traces, datasets, and experiments without leaving the terminal.
FAQ
Is Codex free to use?
Codex is included on ChatGPT's Free plan and on Go ($8 a month in the US), but both come with limited trial access, and GPT-6 Luna is the suggested model on those plans. Plus at $20 a month is the first tier with full Codex access and GitHub code review. Claude Code has no free option and starts with Pro at $20.
Can you use Codex and Claude Code together?
Yes. They're separate subscriptions, but both can work in the same repo, and since Claude Code reads AGENTS.md when no CLAUDE.md exists, one AGENTS.md file can hold shared instructions for both. With Respan tracing both agents, you can compare cost and completion on the same tasks instead of relying on impressions.
Do Codex and Claude Code send your code to the cloud?
Yes. Both run locally but send your prompts, the file contents the agent reads, and the model's outputs to the vendor for inference. Cloud sessions go further and run entirely on vendor infrastructure, in Anthropic-managed virtual machines for Claude Code and in OpenAI's cloud environment for Codex. Anthropic doesn't train on Team, Enterprise, or API data unless you opt in, while on Free, Pro, and Max it depends on your privacy setting.
Is Codex CLI open source?
Yes. The Codex CLI is Apache-2.0 licensed on GitHub, so you can read, fork, and modify it. The model still runs on OpenAI or on whichever provider you configure.
How does Cursor compare to Codex and Claude Code?
Cursor is an AI code editor, while Codex and Claude Code are coding agents that also run inside editors. Claude Code's VS Code extension installs in Cursor, and Codex's IDE extension supports Cursor, so you can run either agent there. The real choice is between Cursor's own agent and editor features and a terminal-first agent, which is the tradeoff at the center of Claude Code vs Cursor.
Can you use Claude Code with a ChatGPT subscription?
No. ChatGPT plans cover Codex only, and Claude Code runs Claude models through a Claude subscription, the Anthropic API, or a cloud provider such as Amazon Bedrock. Anthropic doesn't support routing Claude Code to non-Claude models. Codex CLI is more flexible, since it can point at a gateway like Respan and run Claude models through a provider entry in config.toml.