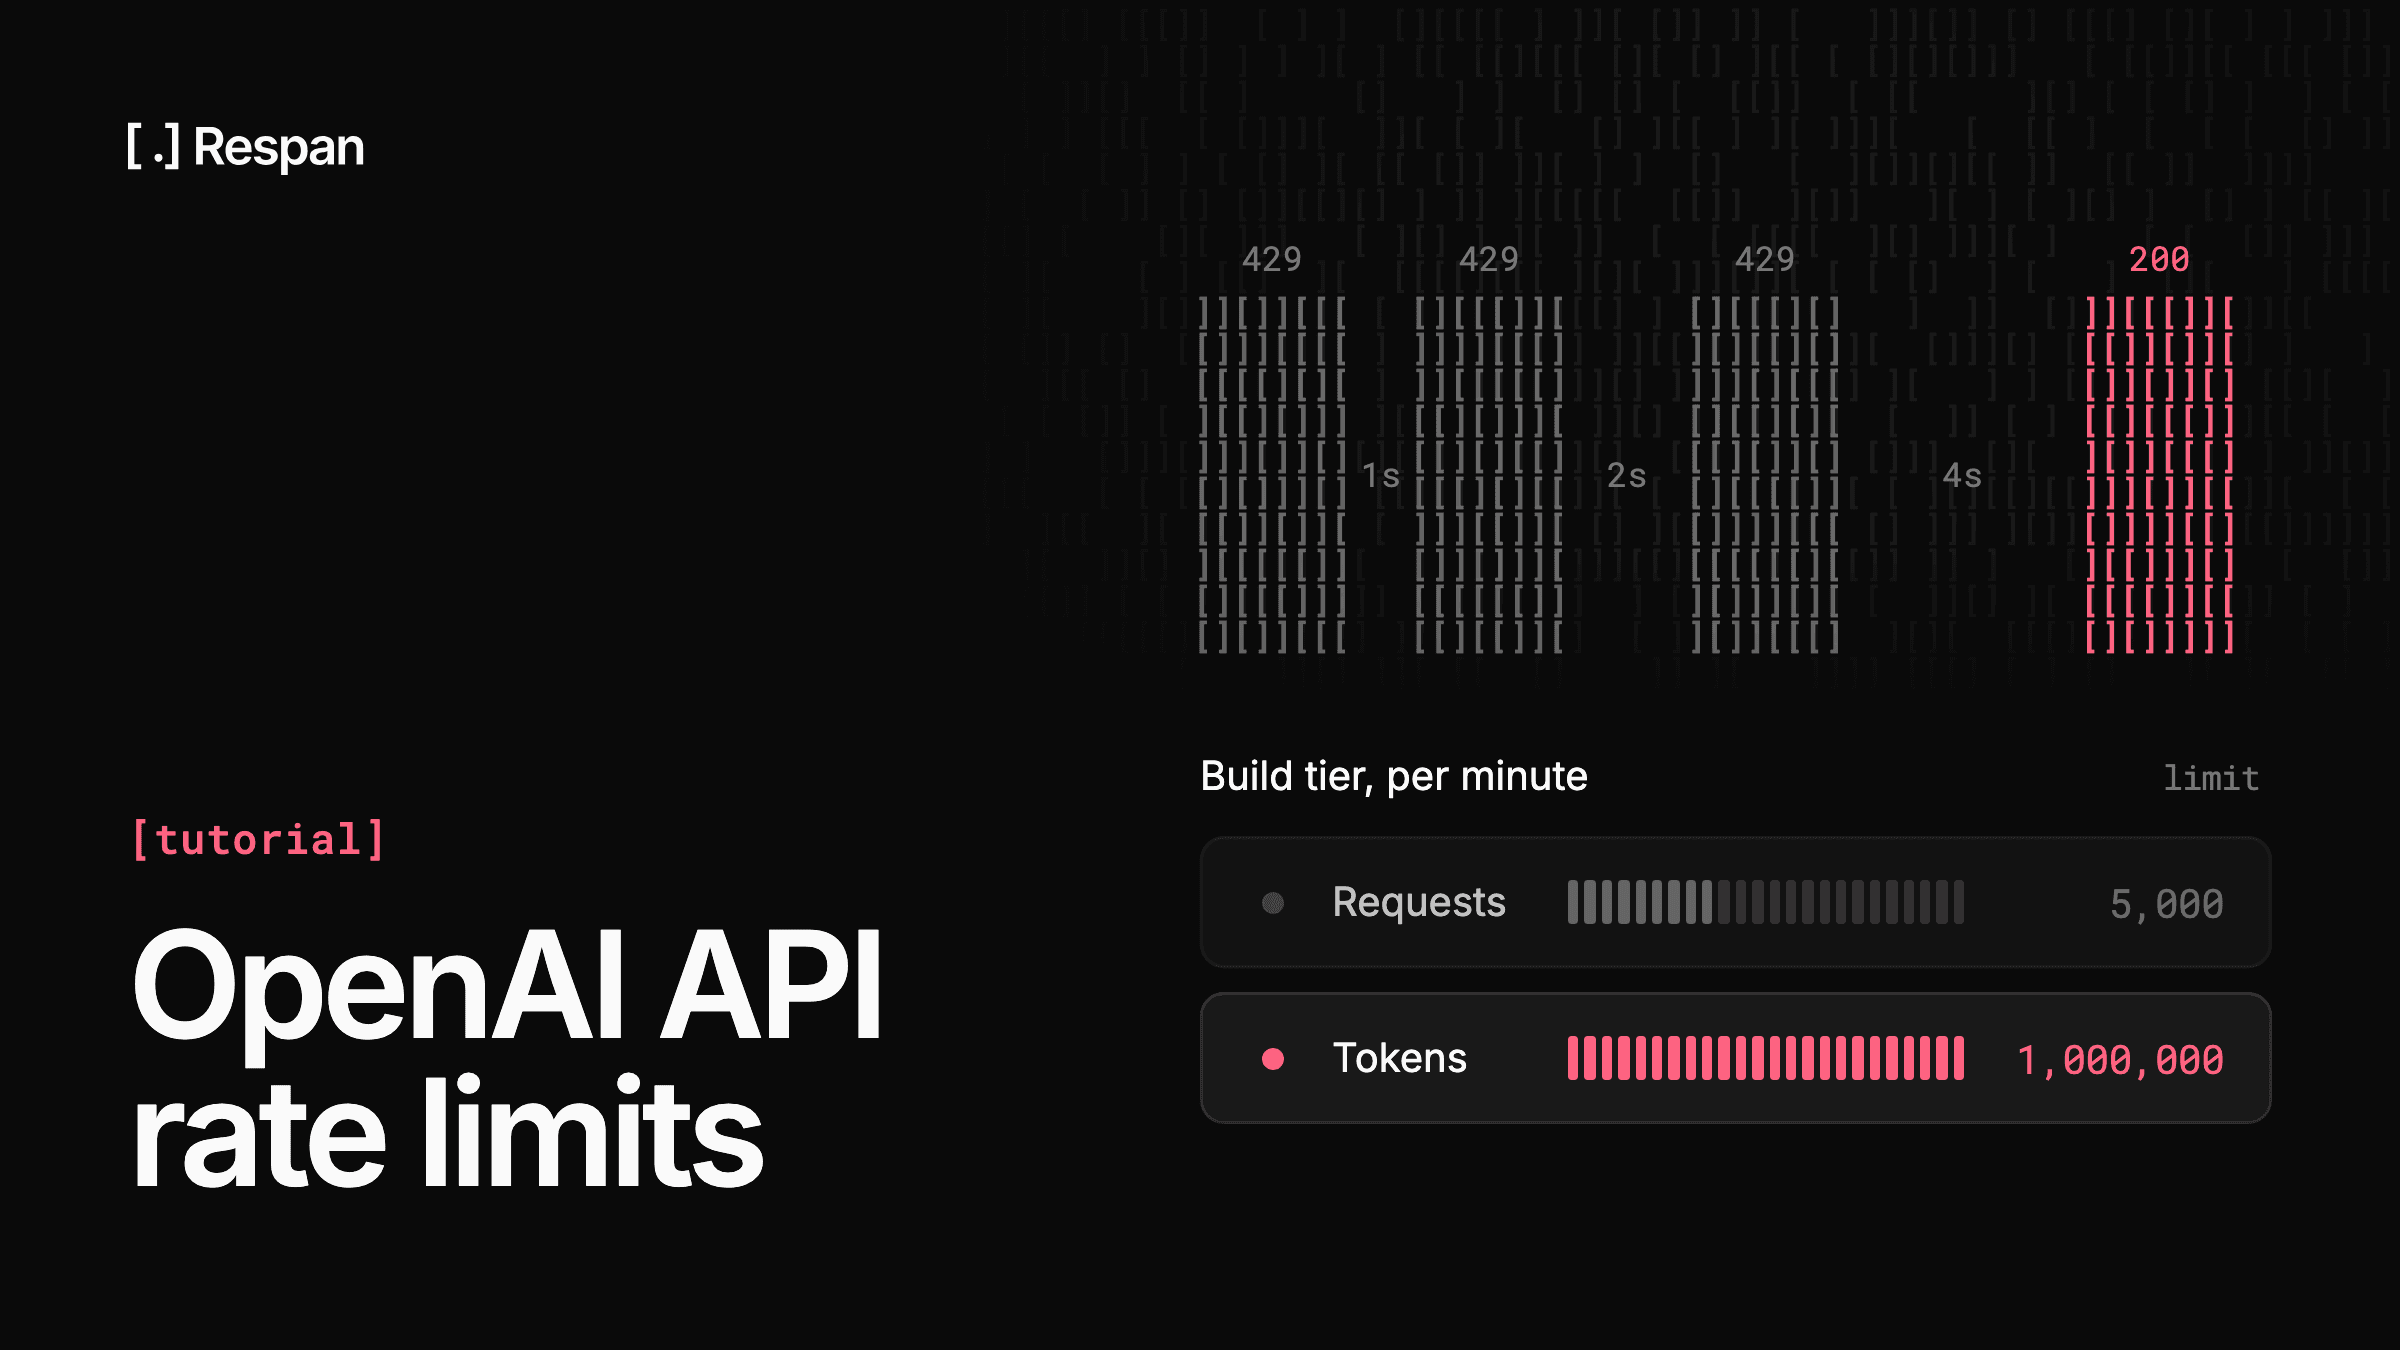
A new OpenAI organization on the Build tier gets 5,000 requests and 1,000,000 tokens per minute on its flagship models. Once the organization reaches $500 in credit purchases, the same models allow 15,000 requests and 40 million tokens per minute, and no support ticket is involved at any point in between.
Until you get there, a burst of traffic that crosses either line comes back as an HTTP 429. That response carries the signals you need to react well, including which limit you hit and when the window resets, but it also shares a status code with the error OpenAI returns when you've run out of credits, and the two need very different handling.
Backoff covers occasional throttling, while at production volume the fix that holds is a second provider behind a gateway, and knowing where your organization sits within OpenAI API rate limits tells you how soon you'll need one.
TL;DR
- OpenAI has four usage tiers based on total credit purchases: Free, Build ($5), Launch ($100), and Grow ($500). Advancement is automatic.
- Limits are enforced on RPM (requests per minute), TPM (tokens per minute), RPD (requests per day), and TPD (tokens per day), plus images per minute and audio minutes per minute on models that use them.
- A 429 response includes
x-ratelimit-*headers and aRetry-Afterheader. Always read them. Do not blindly sleep for a fixed interval. - Exponential backoff with jitter is the baseline retry strategy. The
tenacitylibrary (Python) orp-retry(TypeScript) handles it cleanly. - The real fix at scale is a gateway with provider fallback: when OpenAI is throttled, route the same request to Azure OpenAI, Bedrock, or another mirror without changing app code.
The tier system
OpenAI's rate limits scale with your organization's total credit purchases. Per OpenAI's rate limits guide, each organization's usage tier upgrades automatically as its total credit purchases reach each threshold, and each tier also carries a monthly usage limit:
| Tier | Qualification | Monthly usage limit |
|---|---|---|
| Free | Allowed geography | $100 / month |
| Build | $5 in total credit purchases | $500 / month |
| Launch | $100 in total credit purchases | $5,000 / month |
| Grow | $500 in total credit purchases | $200,000 / month |
Tier advancement is automatic. You do not file a request. You can check your current tier and limits in the platform settings under Limits.
What counts toward a tier is total credit purchases across the organization, not usage in the most recent month. Promo and grant credits also count toward tier qualification in most cases (verify on the live tier page if relying on this). Rate limits themselves are defined at both the organization and the project level, never per user.
The limit dimensions
OpenAI enforces limits on several dimensions per model. Hit any one of them and you get a 429.
- RPM (requests per minute). The number of API calls you can make per rolling 60-second window. The blunt instrument; easy to hit on bursty workloads.
- TPM (tokens per minute). The total input + output tokens you can process per rolling 60-second window. The realistic constraint for long-context work; a single call with 100k context tokens can eat a huge fraction of your TPM budget.
- RPD (requests per day). A daily request cap. Mostly enforced on free-tier accounts and on certain low-tier model snapshots.
- TPD (tokens per day). A daily token cap, applied on some models, again mostly relevant on lower tiers.
- IPM and audio minutes. Image models are limited in images per minute, and streaming audio models in audio minutes per minute.
For the GPT-6 models, OpenAI's docs list these limits by tier, with Luna on its own, higher limits (they change, so check the Limits page for your org):
| Tier | Astra, Sol, Terra RPM | Astra, Sol, Terra TPM | Luna RPM | Luna TPM |
|---|---|---|---|---|
| Build | 5,000 | 1,000,000 | 5,000 | 2,000,000 |
| Launch | 10,000 | 4,000,000 | 10,000 | 10,000,000 |
| Grow | 15,000 | 40,000,000 | 30,000 | 180,000,000 |
The right way to reason about limits: you have a token budget that refills every 60 seconds. Every request reserves tokens against that budget at submission. If your reserved tokens (estimated from input plus max_completion_tokens) would exceed the remaining TPM, the request is rejected with a 429 immediately, before any generation happens.
Reading a 429 response
When you hit a limit, the API returns HTTP 429 with a body that looks like this:
{
  "error": {
    "message": "Rate limit reached for gpt-6-astra in organization org-xxx on tokens per min. Limit: 1000000 / min. Current: 987234 / min.",
    "type": "rate_limit_exceeded",
    "code": "rate_limit_exceeded"
  }
}
The body tells you which dimension you hit. The headers tell you when to retry. Read these on every response, not just on errors:
x-ratelimit-limit-requests/x-ratelimit-limit-tokens: your current budget ceiling.x-ratelimit-remaining-requests/x-ratelimit-remaining-tokens: how much is left in the current window.x-ratelimit-reset-requests/x-ratelimit-reset-tokens: time until the window resets, formatted like6sor1m30s.x-ratelimit-limit-project-tokens/x-ratelimit-remaining-project-tokens/x-ratelimit-reset-project-tokens: the same token budget tracked at the project level.Retry-After: how long to wait before retrying a rate-limited request. This is the most useful header for retry logic.
Honor Retry-After when it's present instead of guessing a delay. OpenAI's guide also says not to use it for quota, billing, or other errors that need someone to act, which is what the next two sections cover.
Exponential backoff with jitter
When you do retry, the standard pattern is exponential backoff with jitter. Pure exponential backoff causes thundering-herd retries when many clients hit the limit at once; jitter spreads them out.
In Python with tenacity:
import openai
from openai import OpenAI
from tenacity import (
    retry,
    stop_after_attempt,
    wait_random_exponential,
    retry_if_exception_type,
)

client = OpenAI()

@retry(
    retry=retry_if_exception_type(openai.RateLimitError),
    wait=wait_random_exponential(min=1, max=60),
    stop=stop_after_attempt(6),
    reraise=True,
)
def chat(messages):
    return client.chat.completions.create(
        model="gpt-6-astra",
        messages=messages,
    )
wait_random_exponential(min=1, max=60) waits a random value in [0, min(60, 2^attempt)] seconds between attempts. After 6 attempts (about 2 minutes of total wait in the worst case), it gives up and reraises the original exception. That is the right behavior for a request-response service: surface the failure rather than block indefinitely.
The same pattern in TypeScript with p-retry:
import OpenAI from "openai";
import pRetry, { AbortError } from "p-retry";

const client = new OpenAI();

async function chat(messages: any[]) {
  return pRetry(
    async () => {
      try {
        return await client.chat.completions.create({
          model: "gpt-6-astra",
          messages,
        });
      } catch (err: any) {
        // Only retry 429 and 5xx. Abort on auth, bad request, etc.
        if (err.status && err.status < 500 && err.status !== 429) {
          throw new AbortError(err);
        }
        throw err;
      }
    },
    {
      retries: 5,
      factor: 2,
      minTimeout: 1_000,
      maxTimeout: 60_000,
      randomize: true,
    }
  );
}
Two refinements that pay off:
- Honor
Retry-Afterwhen present. Instead of jittered exponential, sleep for exactly that duration on the first retry. Fall back to jittered exponential if the header is missing or after the first retry. - Do not retry idempotently unsafe operations. Chat completions are safe to retry. A fine-tune job submission is not. Check the endpoint.
What not to retry
A 429 is retryable. These are not:
- 401 Unauthorized. Your API key is wrong. Retrying does not fix it.
- 403 Forbidden. Your account or org cannot access this model or endpoint.
- 400 Bad Request. Your payload is malformed. Schema, parameter, or content-policy issue.
- 429 with
credit_balance_exhausted. This is the "you ran out of credits" 429, not the rate-limit 429. Itserror.typecan still readinsufficient_quota, so checkerror.code; do not retry, top up. - 429 with a spend or usage limit code.
organization_spend_limit_exceeded,project_spend_limit_exceeded, andorganization_usage_limit_exceededmean a cap was reached, and retrying won't help until the limit changes.
The credits case trips people up. A rate-limit 429 is a "wait and try again" condition, while a credit_balance_exhausted 429 is "you are out of money," and backing off does not help; you need someone to add credits. See OpenAI API Credits for the billing side. One more 429 code is retryable: slow_down, which OpenAI returns when your request rate rises too quickly even inside your RPM and TPM limits, so ramp traffic up gradually and retry with backoff.
Estimating tokens before you send
The cleanest way to avoid 429s is to track your own usage and slow yourself down before OpenAI does. Before each request, estimate token count (input tokens via tiktoken plus your max_completion_tokens setting), check against a local token bucket sized to your TPM, and sleep if you are about to exceed it.
A single-process bucket is a fine first pass. At scale across multiple processes or services, you need a shared bucket in Redis, a sidecar, or a gateway. That is where most teams move to a gateway.
Advancing through the tiers
Because advancement follows total credit purchases and happens automatically, the practical levers are about how and where you buy credits:
- Advancement tracks purchases, not usage. Buying $500 in credits moves an organization to Grow, whether it arrives in one top-up or several.
- Keep auto-recharge on. An organization with an empty balance returns
insufficient_quota429s regardless of tier, so a higher tier doesn't help once the credits run out. - Concentrate spend in one org. Tier qualification is per organization. Spreading $500 across three orgs leaves each one on Launch instead of Grow.
- Watch the monthly usage limit. Each tier also caps monthly usage, at $500 on Build and $5,000 on Launch, so a fast-growing product can hit that ceiling before it hits its per-minute limits.
- Do not ask support to upgrade you manually. OpenAI does not generally process manual tier upgrade requests in 2026; advancement is automatic once you meet the threshold.
Provider fallback: the real fix at scale
Past about 100 RPS sustained, in-process backoff is not enough. The right architecture is multi-provider: OpenAI as primary, Azure OpenAI as secondary mirror (same models, separate rate-limit pool), Bedrock or Vertex as tertiary for non-OpenAI models. When primary throttles, you fall over to a mirror with the same model name, transparently.
An LLM gateway is the natural place to implement this, since the app code calls one endpoint. With Respan's AI gateway, you define the fallback chain once, at the org level or per request. Respan tries OpenAI first, retries per your rules when it returns a 429 or a 5xx, and if OpenAI is still failing, reroutes the request to Azure. The client sees a successful response, and the 429 becomes a logline instead of a failed call.
import os
from openai import OpenAI

# Point your client at the gateway, not OpenAI directly.
client = OpenAI(
        base_url="https://api.respan.ai/api/",
    api_key=os.environ["RESPAN_API_KEY"],
)

# Fallback configured in Respan:
# primary: openai/gpt-6-astra
# fallback: azure/gpt-6-astra
# on: [429, 500, 502, 503, 504]
client.chat.completions.create(
    model="gpt-6-astra",
    messages=[...],
)
The fallback is invisible to your code. Respan logs every request as a span with latency and cost, so you can see how often the secondary is firing; if it is more than 5 percent of traffic, you have a real capacity problem and should advance tiers or split traffic.
For a reliability reference point, Mem0 built a 99.99% reliable memory layer for AI agents on Respan.
Common gotchas
- Retrying on 4xx errors that are not 429. A 400 is permanent. Retrying wastes time and clutters your logs.
- Fixed
time.sleep(5)between retries. Works for one client; thunders the herd when many clients hit the limit simultaneously. Use jittered exponential. - Not capping retry count. A retry loop with no
stop_after_attemptwill block your request handler indefinitely on a sustained outage. Always cap. - Ignoring
Retry-After. It comes from the server, so it beats any fixed delay you pick. Use it on the first retry. - Per-process token bucket in a multi-process service. Each process thinks it has the full quota; combined, you blow past the limit. Use a shared bucket or a gateway.
- Conflating
insufficient_quotawith rate limits. Different problem, different fix. Check the error code forcredit_balance_exhausted.
FAQ
How do I check my current rate limits?
The platform Limits page lists every model and your current RPM/TPM/RPD/TPD. The response headers (x-ratelimit-limit-*) on every successful call also tell you live.
Can I ask OpenAI for higher limits?
Limits scale automatically with spend and tier. There is no manual override request for standard models. For enterprise contracts, your account manager handles it.
Why does Azure OpenAI say I've exceeded the token rate limit?
Azure OpenAI enforces its own TPM and RPM quota, separate from OpenAI's usage tiers, so an Azure 429 has nothing to do with your openai.com tier. Quota is set per model and deployment type and tracked at the subscription level, and since May 2026, Global Standard deployments of the same model share one pool across every region in a subscription. Microsoft also notes that you can get 429s while your usage metrics still look under quota. The fixes are the same as on openai.com: retry with backoff, request more quota, move latency-critical traffic to provisioned throughput, or let a gateway like Respan fall back to another deployment or to OpenAI directly when Azure throttles.
Does prompt caching count against TPM?
Cached tokens still count as input tokens for TPM accounting (you pay less for them, but they consume budget). Plan capacity accordingly.
Are batch API calls subject to rate limits?
Batch has its own queue limit, separate from synchronous RPM/TPM. Submitting a batch with 100,000 requests does not block your live traffic.
What is the difference between rate_limit_exceeded and insufficient_quota?
Both return HTTP 429. The first is "wait, then retry, you will succeed." The second, which carries the code credit_balance_exhausted, is "you are out of credits, retrying will not help." Check the error.code field.
Should I retry on 500 errors?
Yes, with backoff. 500s are typically transient. Use the same retry policy as 429.
How do I shape traffic so no single feature starves the others?
OpenAI does not natively offer sub-account limits beyond projects. In Respan, you can give each feature its own API key and set soft and hard caps on spend or rate per key or per customer, so one feature hits its own ceiling instead of draining the shared budget.
Related
- What Is an LLM Gateway? Architecture and When to Use One
- Anthropic API Rate Limits + 429/529 Handling Guide (2026)
- OpenAI API Credits Explained
- Anthropic Message Batches API: 50% Off Async Jobs (2026)
- Claude Prompt Caching: 90% Cost Reduction Guide (2026)
- How to Evaluate an LLM
- How to Reduce OpenAI API Costs in 2026