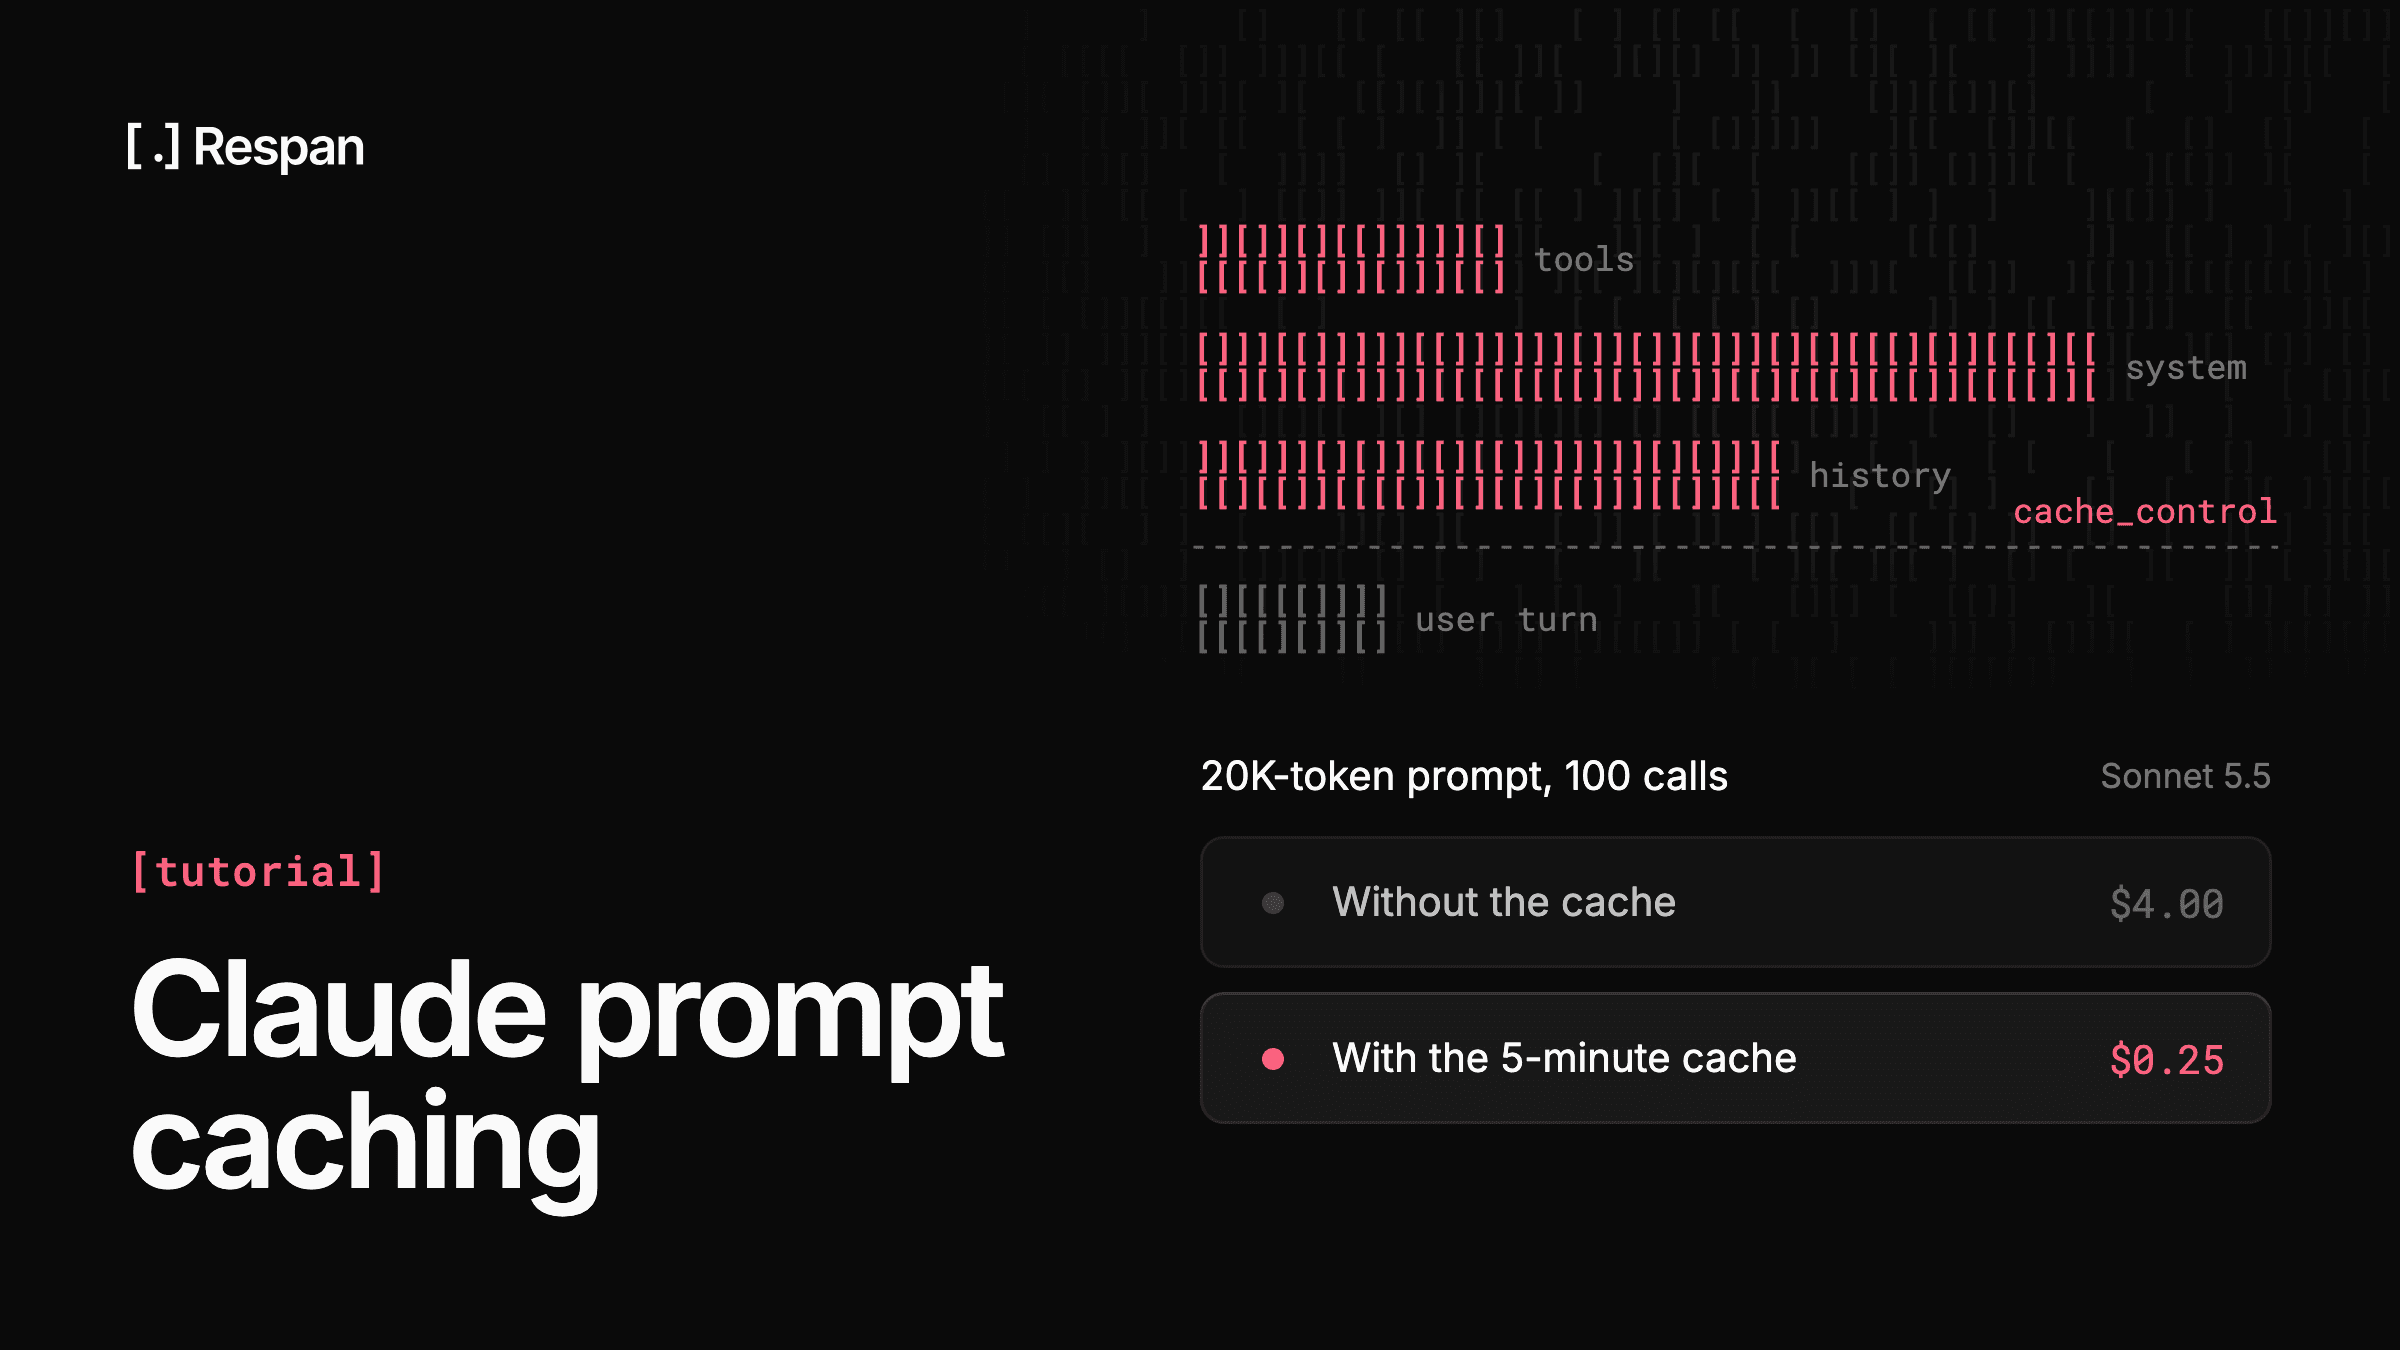
A 20K-token system prompt sent 100 times in five minutes costs $4.00 in input tokens on Claude Sonnet 5.5. Cache that prompt and the same traffic costs about $0.25, because every call after the first reads the prefix at a twentieth of the input price instead of paying for it again.
The savings depend on getting the details right. Breakpoints are positional, and small changes like a reordered tool definition break the cache without returning an error. The 1-hour cache also costs more to write than the 5-minute default, and whether that premium pays off comes down to how far apart your requests land.
Claude prompt caching is worth turning on for any prompt with a long stable prefix, and the decision that actually moves your bill is which TTL fits your traffic pattern.
TL;DR
- Mark up to 4 stable prefixes with
cache_control: { type: "ephemeral" }, or add one top-levelcache_controland let automatic caching place the breakpoint for you. - 5-minute cache (default): writes cost 1.25x base input price.
- 1-hour cache (
ttl: "1h"): writes cost 2x base input price, and reads cost the same as the 5-minute cache. - Reads cost 0.1x base input on most models, 0.05x on Opus 5.5 and Sonnet 5.5, and 0.025x on Fable 5.1 and Mythos 5.1.
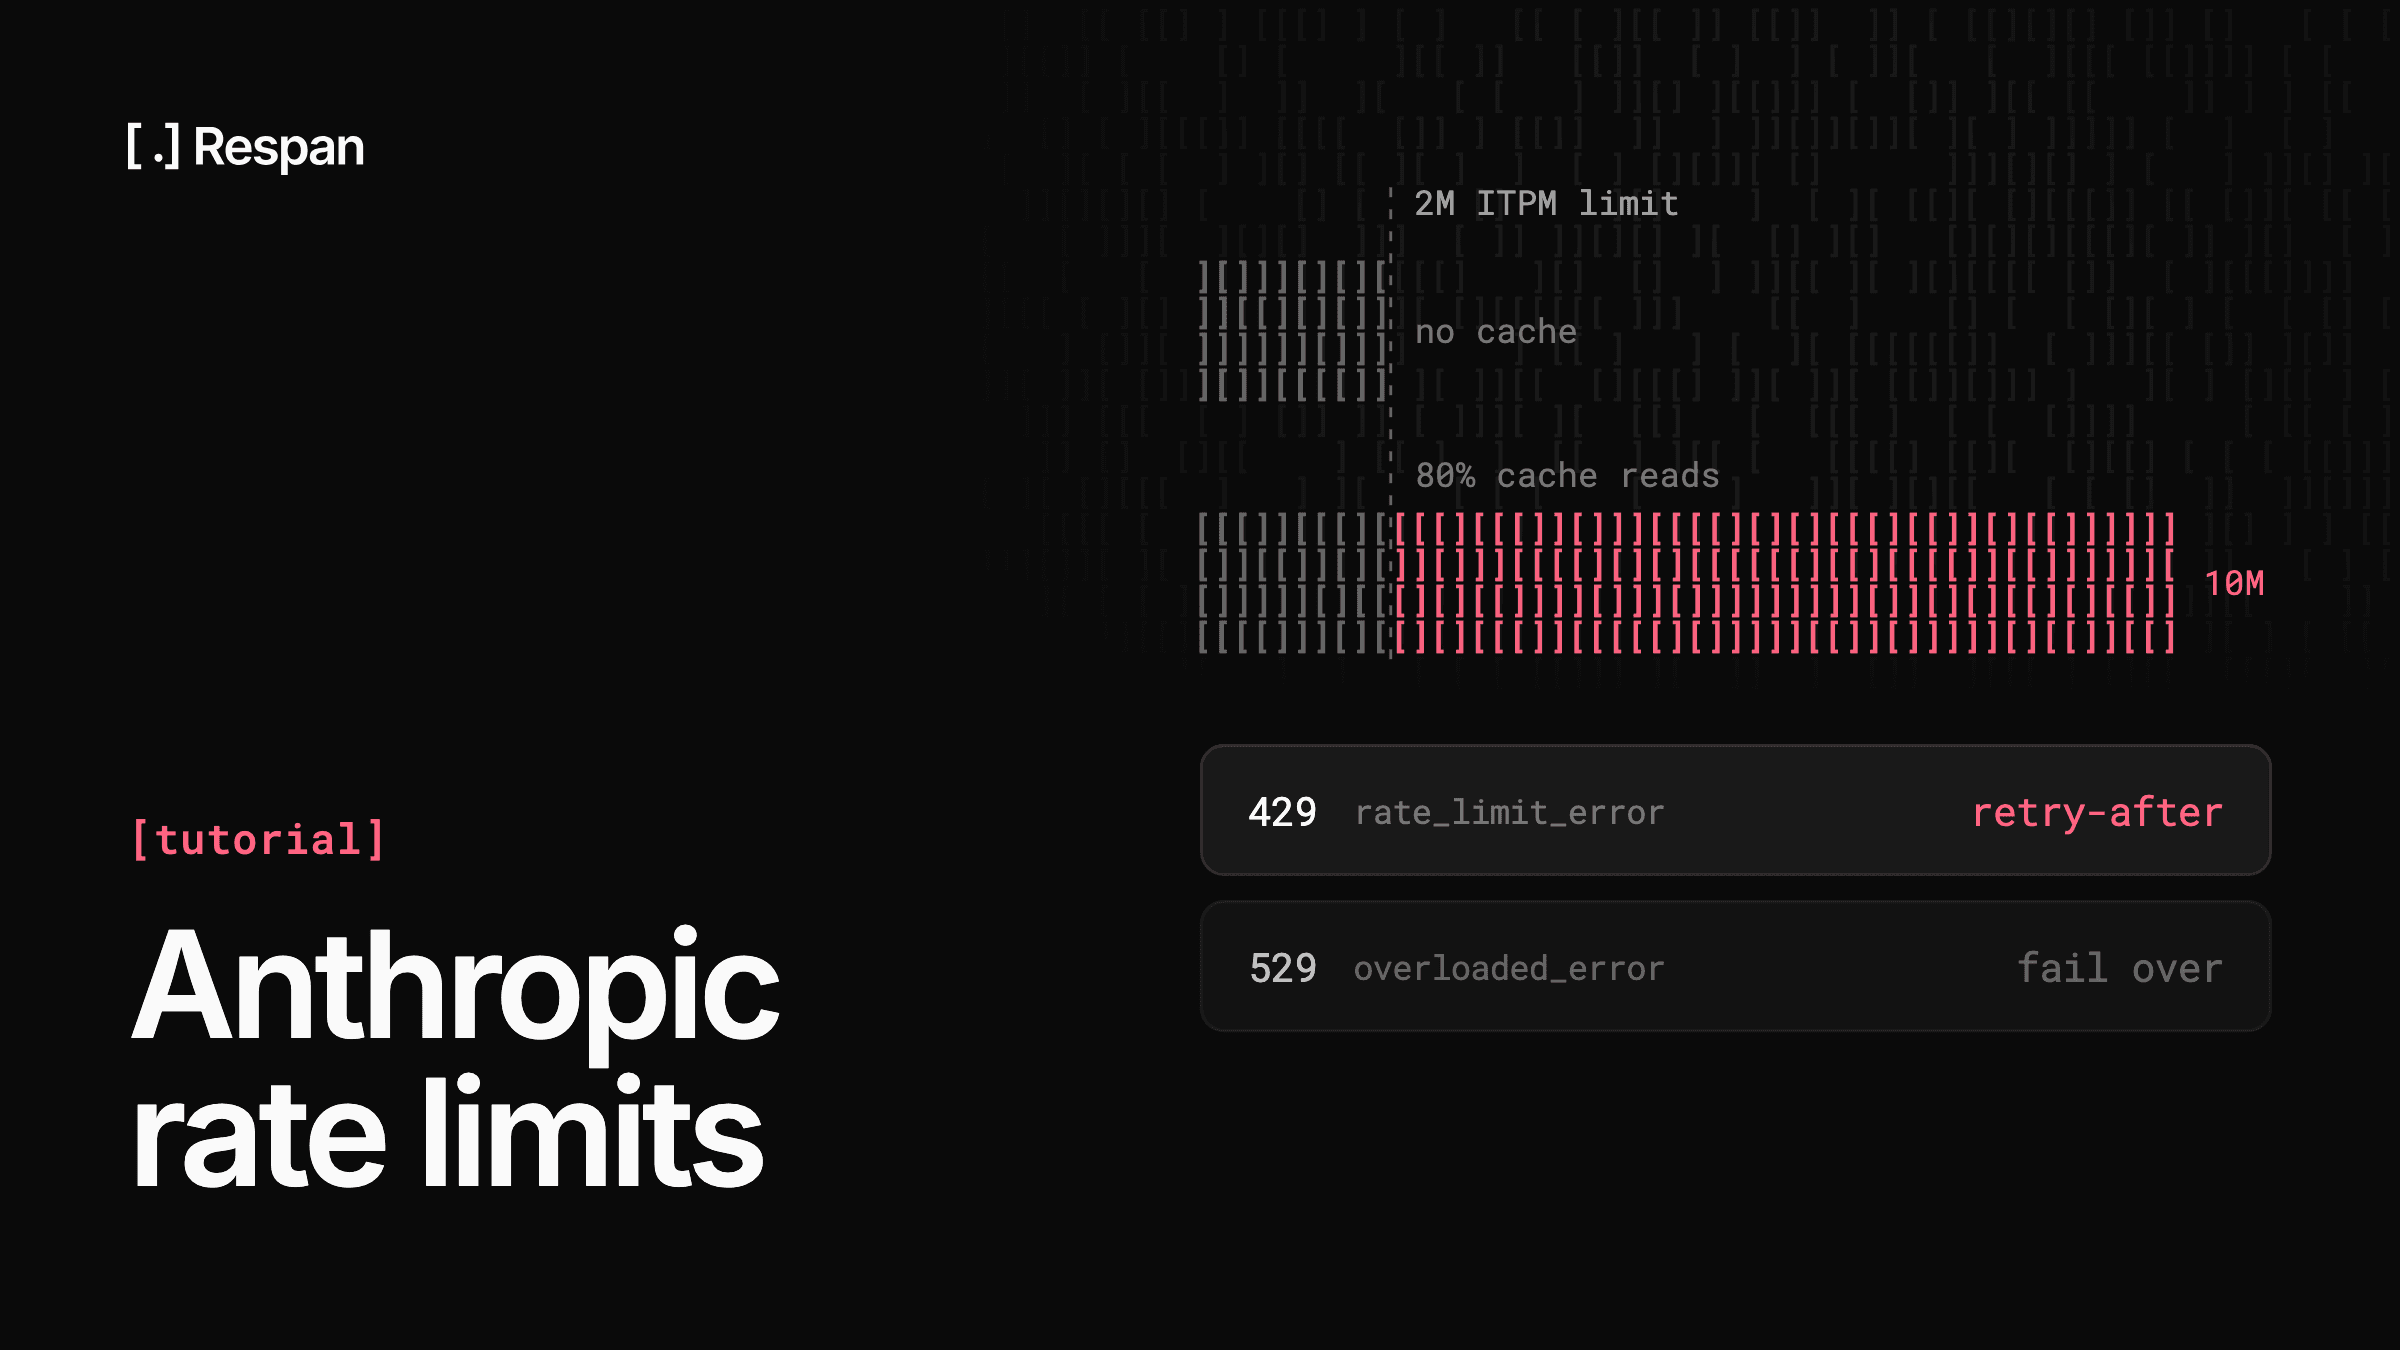
- Cache reads do not count toward your ITPM rate limit on current models. Caching is also a rate-limit multiplier.
- Order matters: the cache follows the hierarchy tools, then system, then messages, and it's matched as a prefix, not a substring.
- Watch the response's
cache_creation_input_tokensandcache_read_input_tokensfields to confirm hits.
What prompt caching actually does
A Claude request looks roughly like: tool definitions, system prompt, conversation history, current user message. Most of that is the same on the next call. The system prompt does not change. The conversation history is the same plus one new turn. Anthropic's API lets you mark up to 4 points in that prompt with cache_control. Each marked block becomes a cache breakpoint.
On the first call that creates the cache, you pay a premium (cache write). On any subsequent call within the TTL whose prompt has the same prefix up to that breakpoint, you pay a small fraction of the input price for the cached tokens (cache read). The model sees the same content; you pay much less.
A cache entry is keyed on the exact token sequence leading up to the breakpoint. Any change to that prefix, including whitespace, invalidates the cache.
The price math
On Claude Sonnet 5.5, base input is $2 per million tokens (MTok). The 5-minute cache writes at $2.50/MTok and reads at $0.10/MTok. So a 20K-token system prompt that is hit 100 times within 5 minutes pays:
- Without cache: 100 calls x 20K x $2/MTok = $4.00
- With 5-min cache: 1 write (20K x $2.50/MTok = $0.05) + 99 reads (99 x 20K x $0.10/MTok = $0.198) = $0.248
That is roughly a 94% reduction on input tokens for the system prompt portion. At current prices from Anthropic's pricing page, the rest of the lineup works out like this:
| Model | Base Input | 5-min Write | 1-hour Write | Cache Read |
|---|---|---|---|---|
| Fable 5.1 | $10/MTok | $12.50/MTok | $20/MTok | $0.25/MTok |
| Opus 5.5 | $4/MTok | $5/MTok | $8/MTok | $0.20/MTok |
| Sonnet 5.5 | $2/MTok | $2.50/MTok | $4/MTok | $0.10/MTok |
| Haiku 5.5 | $0.10/MTok | $0.125/MTok | $0.20/MTok | $0.01/MTok |
Haiku 5.5's rates apply to prompts up to 100K tokens. Past that, every rate rises fivefold, to $0.50 base input, $0.625 and $1.00 for writes, and $0.05 for reads, and a request over the threshold pays the higher rates even when part of its prompt is a cache hit.
Write multipliers are the same on every model, at 1.25x base input for the 5-minute cache and 2x for the 1-hour cache. Read multipliers vary, though: 0.1x on Haiku 5.5, 0.05x on Opus 5.5 and Sonnet 5.5, and 0.025x on Fable 5.1 and Mythos 5.1, which makes cached reads on the current Fable, Mythos, Opus, and Sonnet models even cheaper relative to their input price.
The 5-minute write premium pays back on the second request. On a model with a 0.1x read multiplier, two calls cost 1.35x base input with caching against 2x without, so anything that repeats inside a 5-minute window is worth caching.
Where to place cache breakpoints
You get up to 4 cache_control markers. The cache follows a fixed hierarchy of tools, then system, then messages, and a change at any level invalidates that level and everything after it. The standard arrangement:
- Tool definitions (stable across the session)
- System prompt (usually the longest stable text)
- Conversation history up to the last user turn
- (Reserve) for a fourth layer if needed
Anything after the last breakpoint is treated as fresh input on every call.
If you'd rather not place breakpoints by hand, automatic caching does it for you. Add a single cache_control field at the top level of the request, and Claude applies the breakpoint to the last cacheable block and moves it forward as the conversation grows:
resp = client.messages.create(
    model="claude-sonnet-5-5",
    max_tokens=1024,
    cache_control={"type": "ephemeral"},
    system=SYSTEM_PROMPT,
    messages=messages,
)Python example: system prompt caching
import os
import anthropic

client = anthropic.Anthropic(api_key=os.environ["ANTHROPIC_API_KEY"])

SYSTEM_PROMPT = open("system_prompt.md").read()  # imagine this is 15K tokens

def ask(user_message: str):
    resp = client.messages.create(
        model="claude-sonnet-5-5",
        max_tokens=1024,
        system=[
            {
                "type": "text",
                "text": SYSTEM_PROMPT,
                "cache_control": {"type": "ephemeral"},
            }
        ],
        messages=[{"role": "user", "content": user_message}],
    )
    print("cache_creation_input_tokens:", resp.usage.cache_creation_input_tokens)
    print("cache_read_input_tokens:", resp.usage.cache_read_input_tokens)
    print("input_tokens:", resp.usage.input_tokens)
    return resp

ask("First question")   # writes cache
ask("Second question")  # reads cache
On the first call you should see cache_creation_input_tokens populated with the system prompt token count. On the second, cache_read_input_tokens carries that count and cache_creation_input_tokens is zero or near it.
TypeScript example: RAG context caching
The same pattern in TypeScript, applied to a long RAG context block. The context is large (say, 50K tokens of retrieved chunks) and reused for follow-up questions about the same document.
import Anthropic from "@anthropic-ai/sdk";

const client = new Anthropic({ apiKey: process.env.ANTHROPIC_API_KEY });

async function askWithContext(ragContext: string, userMessage: string) {
  const resp = await client.messages.create({
    model: "claude-sonnet-5-5",
    max_tokens: 1024,
    system: [
      {
        type: "text",
        text: "You are a research assistant. Answer based on the provided context.",
        cache_control: { type: "ephemeral" },
      },
    ],
    messages: [
      {
        role: "user",
        content: [
          {
            type: "text",
            text: `<context>\n${ragContext}\n</context>`,
            cache_control: { type: "ephemeral" },
          },
          {
            type: "text",
            text: userMessage,
          },
        ],
      },
    ],
  });

  console.log("cache_read:", resp.usage.cache_read_input_tokens);
  console.log("cache_create:", resp.usage.cache_creation_input_tokens);
  return resp;
}
Two breakpoints here: one on the system role, one on the RAG context. The user's actual question is outside both breakpoints, so it varies freely without disturbing the cache. Five follow-up questions on the same document pay for one cache write plus five cache reads on the 50K context block.
5-minute vs 1-hour cache
The default TTL is 5 minutes, and every cache hit refreshes it at no extra cost, so an actively used cache can live well past 5 minutes of wall-clock time. Per Anthropic's prompt caching docs, the lifetime is measured from the start of the request that writes or reads the entry, not from the end of its response. Streaming time counts against it, so if a response takes 4 minutes to stream, the next request that reuses the prefix has to start within about a minute of that response finishing.
The extended 1-hour cache is the right choice when:
- A user session is bursty (questions arrive every 8-15 minutes).
- You serve the same system prompt across many users and want shared cache stability.
- You run nightly evals that reuse the same context across many test cases over a longer window.
The 1-hour cache writes at 2x base input instead of 1.25x, and reads cost the same on both TTLs. The math favors the 1-hour cache whenever the gaps between requests run longer than 5 minutes, because each request after a long gap is a fresh 1.25x write on the 5-minute cache, while the 1-hour cache pays 2x once and reads after that. At a 0.1x read multiplier, the 1-hour cache is cheaper than the 5-minute cache from the second request onward in that pattern, and cheaper than not caching at all from the third. When requests land less than 5 minutes apart, stay on the 5-minute cache, since its write premium is lower and the reads cost the same.
Specify it with the TTL field:
system=[
    {
        "type": "text",
        "text": SYSTEM_PROMPT,
        "cache_control": {"type": "ephemeral", "ttl": "1h"},
    }
]
Cache invalidation gotchas
None of these return an error, so they tend to show up as a higher bill rather than a failed request:
- Whitespace changes break the cache. A trailing newline difference between two clients invalidates the cache.
- Tool definitions sit at the top of the prefix. Reordering tools, renaming a parameter, or tweaking a description string invalidates the entire cache.
- Image content can be cached, but only when bytes are identical. Re-encoded JPEGs from different clients differ at the byte level.
- Thinking and speed settings. The thinking configuration is rendered into the prompt, so changing it invalidates message blocks, and switching between fast and standard speed invalidates both system and message caches.
- The
systemfield type matters. Passing system as a string vs an array of typed blocks is a different shape and produces different cache keys. - Cache is scoped per workspace. On the Claude API, caches are isolated per workspace within an organization, so keys in the same workspace share cache while a second workspace starts cold. Bedrock and Google Cloud isolate at the organization level instead.
- Short prompts are never cached. Anything under 512 tokens is processed without caching on every current model, including Haiku 5.5. Older models set the floor higher, up to 4,096 tokens on Haiku 4.5 and Opus 4.5.
A practical guardrail: log cache_read_input_tokens and cache_creation_input_tokens as separate metrics. If creation suddenly spikes while you expected reads, something just changed in your prefix.
Caching across an agent loop
For agents that loop (tool call, observe, tool call, observe, etc), each iteration appends one more turn. The cache pattern that wins: put a cache_control on the second-to-last turn, so each new iteration writes a small delta and reads the much larger prefix. Automatic caching handles this for you, while the manual version below is useful when you want exact control over where the breakpoint sits.
def chat_step(history, user_input):
    # cache the prior history (stable), append fresh turn outside cache
    messages = []
    for i, turn in enumerate(history):
        block = {"role": turn["role"], "content": turn["content"]}
        # mark the last turn of history as the cache breakpoint
        if i == len(history) - 1:
            block["content"] = [
                {
                    "type": "text",
                    "text": turn["content"],
                    "cache_control": {"type": "ephemeral"},
                }
            ]
        messages.append(block)
    messages.append({"role": "user", "content": user_input})

    return client.messages.create(
        model="claude-sonnet-5-5",
        max_tokens=2048,
        messages=messages,
    )
Each iteration recreates the cache one step further along the conversation. A 20-step agent loop on a 1M-context Claude run can pay 90% or less than the normal input price on the bulky prefix.
How Claude Code uses prompt caching
Claude Code handles caching on its own. It re-sends the full conversation on every turn and orders each request so the system prompt and tool definitions come first, project context like CLAUDE.md second, and the conversation last. The same prefix rules apply, so a change high in that order rebuilds everything below it, and the first turn after the change runs slower and costs more.
The cache TTL depends on how you pay, according to Claude Code's prompt caching docs. On a Claude subscription within your plan's usage, the main conversation gets the 1-hour cache, while subagents, compaction, and other background requests get 5 minutes. With an API key, a cloud provider, or once a subscription moves onto usage credits, everything defaults to 5 minutes. You can set it yourself with the promptCacheTtl setting or the CLAUDE_CODE_PROMPT_CACHE_TTL environment variable, which take 5m or 1h and need Claude Code v2.1.242 or later, and subagentPromptCacheTtl does the same for requests outside the main conversation.
The actions that break the cache in Claude Code are mostly ones you can schedule around:
- Switching models - Each model has its own cache, so
/modelmid-session rereads the whole history, and theopusplansetting switches models every time you enter or leave plan mode. - Changing effort - This invalidates the cache on most models, though Opus 5.5, Sonnet 5.5, Haiku 5.5, and Fable 5.1 keep it with an API key or a Claude subscription.
- Turning on fast mode - The first fast-mode request misses the cache, once per conversation.
- Adding or removing tools - Connecting an MCP server or denying a whole tool invalidates the cache only when tool search is off, since tool search keeps the tool list fixed by default on supported models.
- Compacting -
/compactreplaces the history by design, and it costs the most on a session resumed after the cache expired. - Upgrading Claude Code - A new version usually changes the system prompt, so the first conversation after an upgrade builds its cache from the top.
Editing CLAUDE.md mid-session keeps the cache, but the edit doesn't take effect until /clear, /compact, or a restart. Changing permission mode, invoking skills, and /rewind keep the cache as well. To check how a session is doing, run /usage, which shows a Prompt cache (main) line with the hit ratio and, on recent versions, the likely cause of the last miss.
Caching plus the 1M context window
Every current Claude model supports a 1M-token context window, and Fable 5.1, Opus 5.5, and Sonnet 5.5 bill it at a flat rate, while Haiku 5.5's rates rise past 100K tokens. Without caching, a 500K-token prompt every turn would shred your budget. With caching, the 500K is paid once at the write rate then read cheaply for the rest of the session. Caching is what makes the 1M context window financially viable for anything beyond a one-shot question.
Monitoring cache hits in production
Cache metrics come back on every response, but they only help if something collects them across calls. Routing Claude traffic through Respan's AI gateway logs every request as a span with latency and cost attached, so cost per call shows whether a deploy kept hitting cache or started rewriting it. Monitors watch cost and tokens over any window and alert Slack, email, or a webhook the moment one breaches, which turns a silent cache break into an alert.
For major providers, Respan passes requests through unmodified, so your cache_control markers reach Anthropic exactly as you wrote them. That matters because a gateway that strips or rewrites those markers bills the whole prompt as uncached input on every turn. Respan also runs its own exact-match cache with a configurable TTL (30 days by default), which serves an exact repeat request near-free and instantly, as a separate layer in front of Claude's prompt caching.
FAQ
How much does Claude prompt caching cost?
Cache writes cost 1.25x base input for the 5-minute TTL and 2x for the 1-hour TTL. Reads cost 0.1x base input on most models, 0.05x on Opus 5.5 and Sonnet 5.5, and 0.025x on Fable 5.1 and Mythos 5.1, so each cache read saves 90% or more against the normal input price.
Is prompt caching worth it?
Yes, for any prompt with a stable prefix that repeats within the cache's lifetime. The 5-minute cache pays for itself on the second request, since two calls cost 1.35x base input with caching against 2x without on a model with a 0.1x read multiplier, and the 20K-token Sonnet 5.5 example above cuts input cost on the cached prefix by about 94%. It isn't worth it when the prefix changes on every call, when the prompt falls under the 512-token minimum, or when requests land further apart than the TTL you chose, since every call then pays a write premium with no read to recover it. Respan logs every Claude call with its cost, so you can see on your own traffic whether caching is paying off.
How long does the cache last?
5 minutes by default, or 1 hour with ttl: "1h", and every hit refreshes the timer at no cost. The lifetime counts from the start of the request that wrote or read the entry, so time spent streaming a long response eats into it.
How many cache breakpoints can I have?
Up to 4 cache_control markers per request, or a single top-level cache_control to let automatic caching place the breakpoint.
Why is my cache_read always zero?
Most common causes: whitespace difference between calls, tool definitions reordered, system content type mismatch (string vs typed array), the 5-minute TTL elapsed, or the prompt falling under the model's minimum cacheable length, which skips caching without an error.
Do cached tokens count toward rate limits?
Not for current models. cache_read_input_tokens are excluded from ITPM. This is a free rate-limit multiplier on top of the cost savings. See Anthropic API rate limits.
Can I cache tool use definitions?
Yes. Tool definitions come first in the cache hierarchy, so a breakpoint on the last tool caches them, and any change to them invalidates everything after.
Should I use 5-min or 1-hour caching?
Use the 5-minute cache when requests reuse a prefix less than 5 minutes apart. Switch to the 1-hour cache when the gaps run longer, since it beats the 5-minute cache from the second request in that pattern and beats no caching from the third.
Related
- AI gateway
- AI evaluation platform
- Anthropic API Rate Limits + 429/529 Handling Guide (2026)
- Anthropic Message Batches API: 50% Off Async Jobs (2026)
- Claude Opus vs Sonnet: The Honest 2026 Comparison
- Anthropic API vs AWS Bedrock Claude (2026): Which to Use
- Claude vs ChatGPT: The Honest 2026 Comparison
- How to Evaluate an LLM