A RAG pipeline is the end-to-end system that combines a knowledge source with a large language model to produce grounded, cited answers. Documents in, embeddings out, retrievals at query time, augmented prompts, generated answers: that's the loop. Building a working RAG pipeline is the first thing many engineering teams ship in their LLM journey; building one that survives production is where most stumble.
This guide is the architectural map. For specific implementation choices, see the related guides linked throughout.
TL;DR
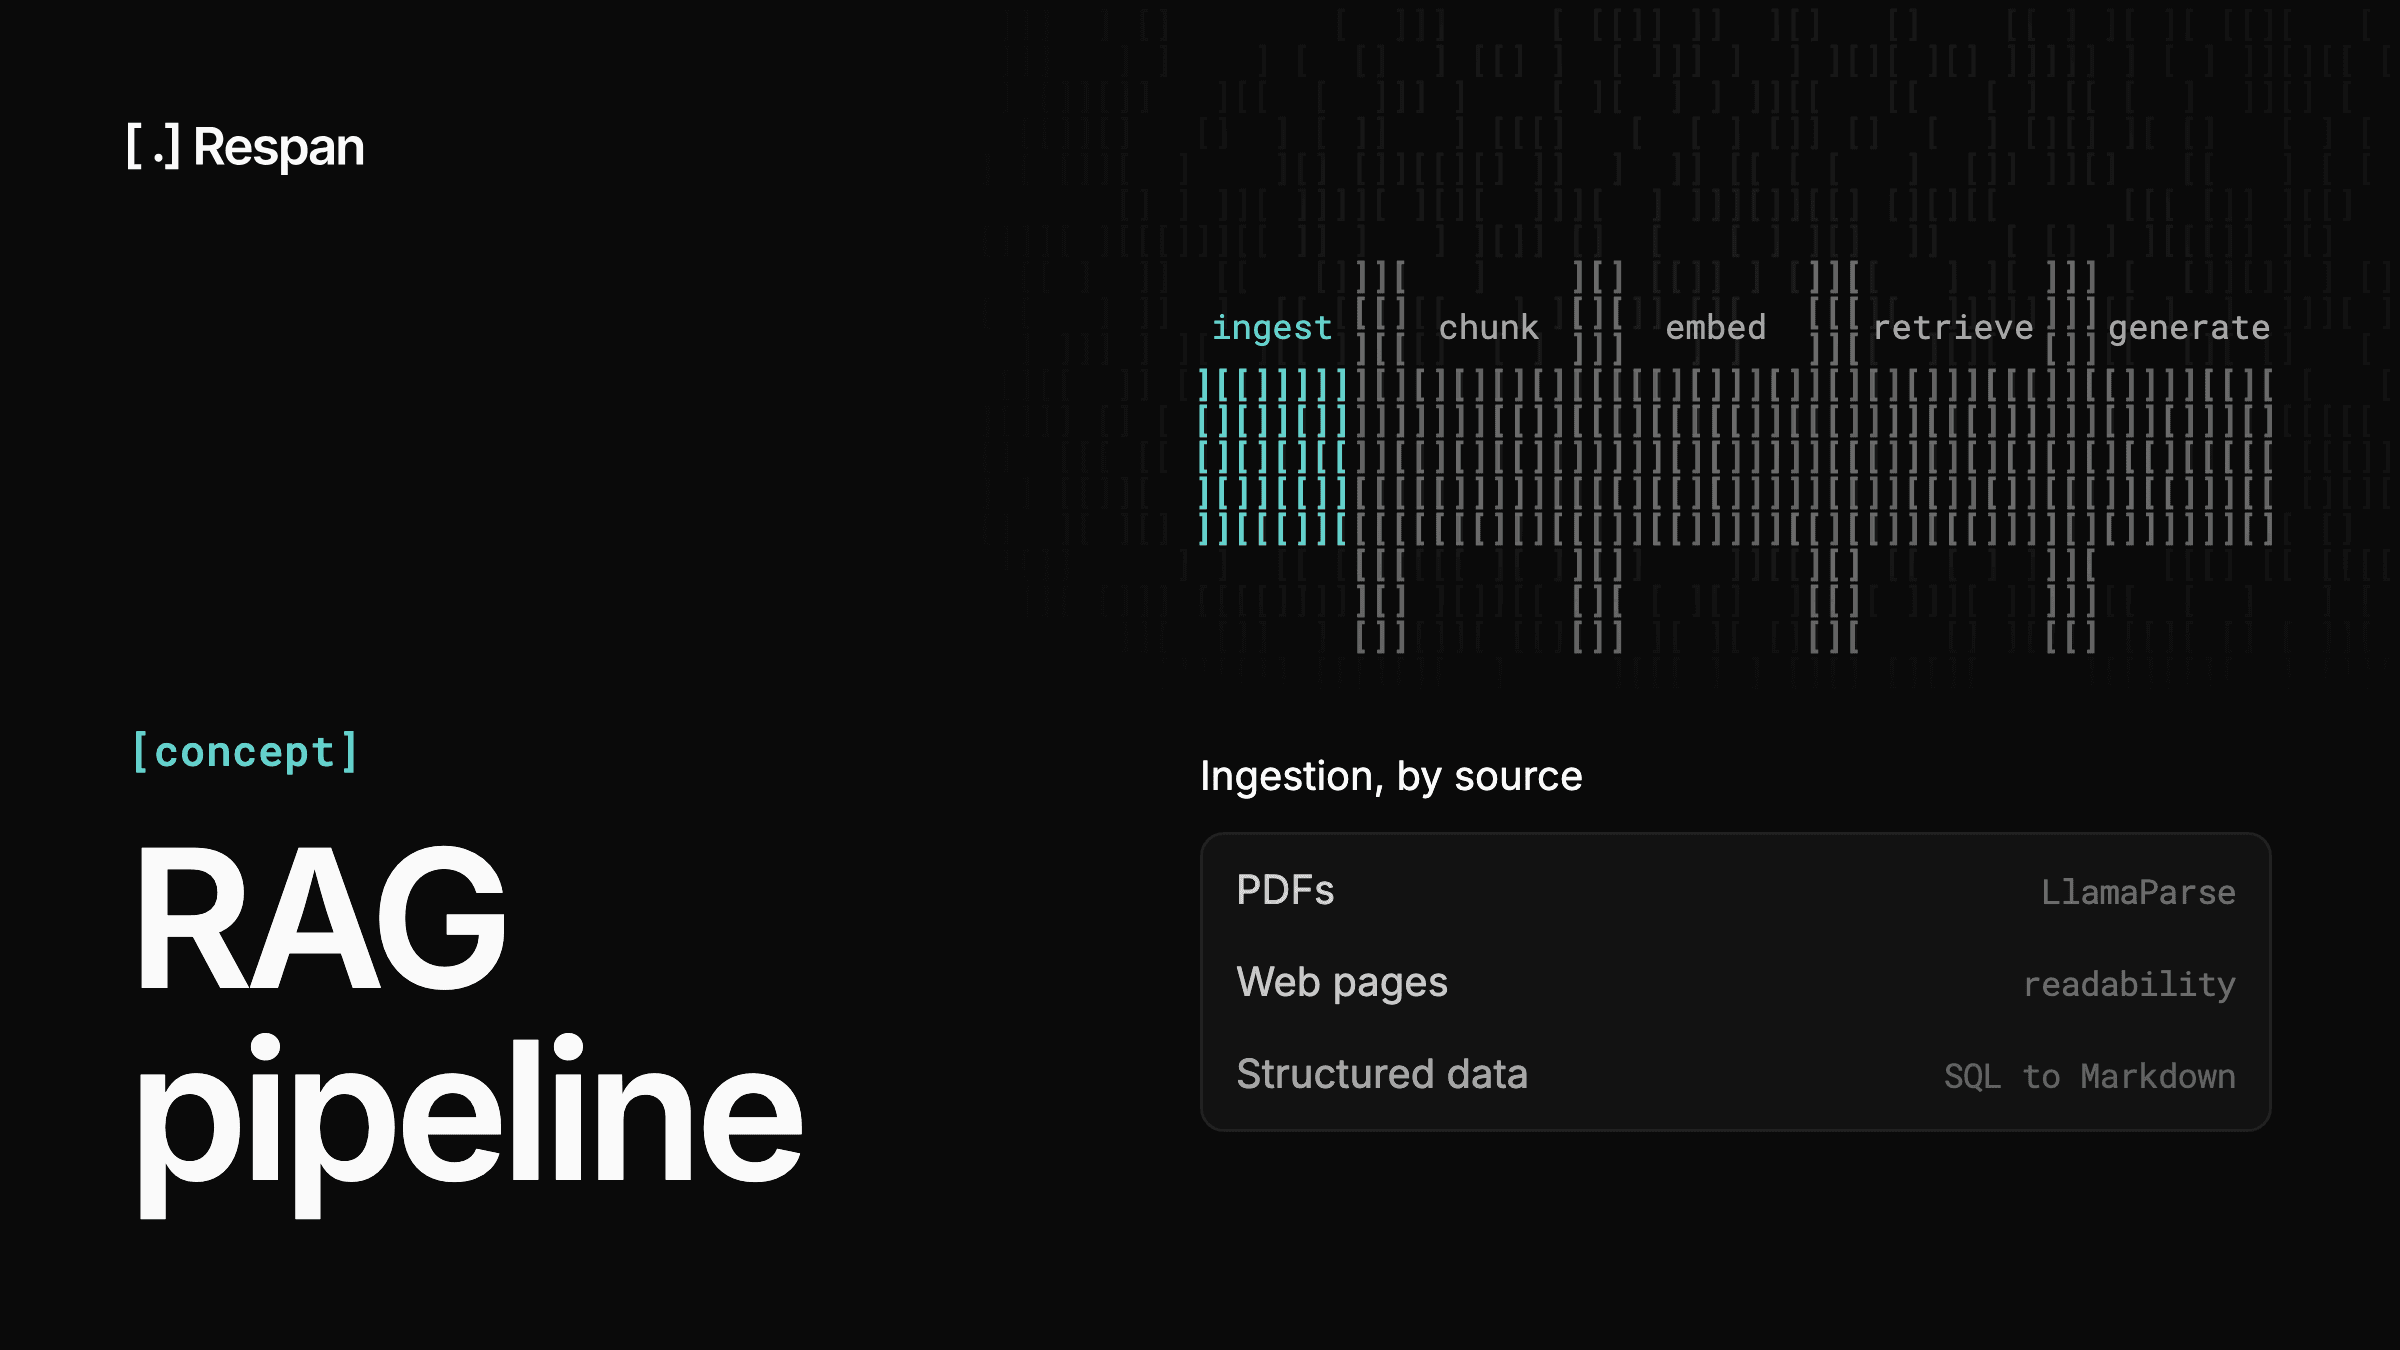
A RAG pipeline has five components:
- Document ingestion: load and clean source documents
- Chunking: split documents into retrievable pieces
- Embedding: convert chunks to vectors and store in a vector DB
- Retrieval: at query time, embed the query and find relevant chunks
- Generation: pass retrieved chunks + user query to an LLM, return grounded answer
That's the basic shape. Production systems add re-ranking, hybrid search (vector + keyword), agentic retrieval loops, citation tracking, and evaluation pipelines. The classic pattern works for simple Q&A; complex domains need the additions.
The five components
1. Document ingestion
Load your source data (PDFs, web pages, internal docs, transcripts, code, structured data). Each source has its own ingestion pattern:
- PDFs: parsing libraries (
pypdf,pdfplumber, LlamaParse for complex layouts) - Web: HTML cleaners + readability extraction
- Structured data: SQL or API → Markdown
- Multimodal: separate pipeline for image OCR, video transcript, audio transcript
The hardest part is the long tail of document types. Multi-column PDFs, scanned tables, embedded images: these break naive parsers. Most production RAG pipelines spend more engineering time on ingestion quality than on any other component.
2. Chunking
Split documents into retrievable units (chunks). Common strategies:
- Fixed-size: N tokens per chunk, with overlap (simplest, often good enough)
- Semantic: split on natural boundaries (paragraphs, sections, code blocks)
- Hierarchical: chunks at multiple granularities (full doc, section, paragraph)
- Late chunking: embed full document, then derive chunk embeddings (newer technique, better recall)
Chunk size matters. Too small: chunks lack context. Too large: retrieval is imprecise. Common sweet spot: 200-500 tokens per chunk with ~50-token overlap.
3. Embedding
Convert chunks to dense vectors using one of the best embedding models (OpenAI text-embedding-3-large, Cohere, Voyage, or open-source like BGE). Store in a vector database:
- Pinecone: managed, simple
- Weaviate: open source, hybrid search built in
- Qdrant: open source, performant
- pgvector: Postgres extension, simplest if you already use Postgres
- Turbopuffer: newer, cost-effective
Choice depends on scale, cost sensitivity, existing infrastructure. For most teams, pgvector or Pinecone is the starting point.
4. Retrieval
At query time:
- Embed the user query with the same embedding model
- Vector search to find top-k similar chunks
- Optionally re-rank with a cross-encoder for higher precision
- Optionally hybrid search (combine vector with BM25 keyword search)
Top-k is usually 5-20. Re-ranking with a model like Cohere Rerank or BGE Reranker meaningfully improves answer quality but adds 100-300ms latency.
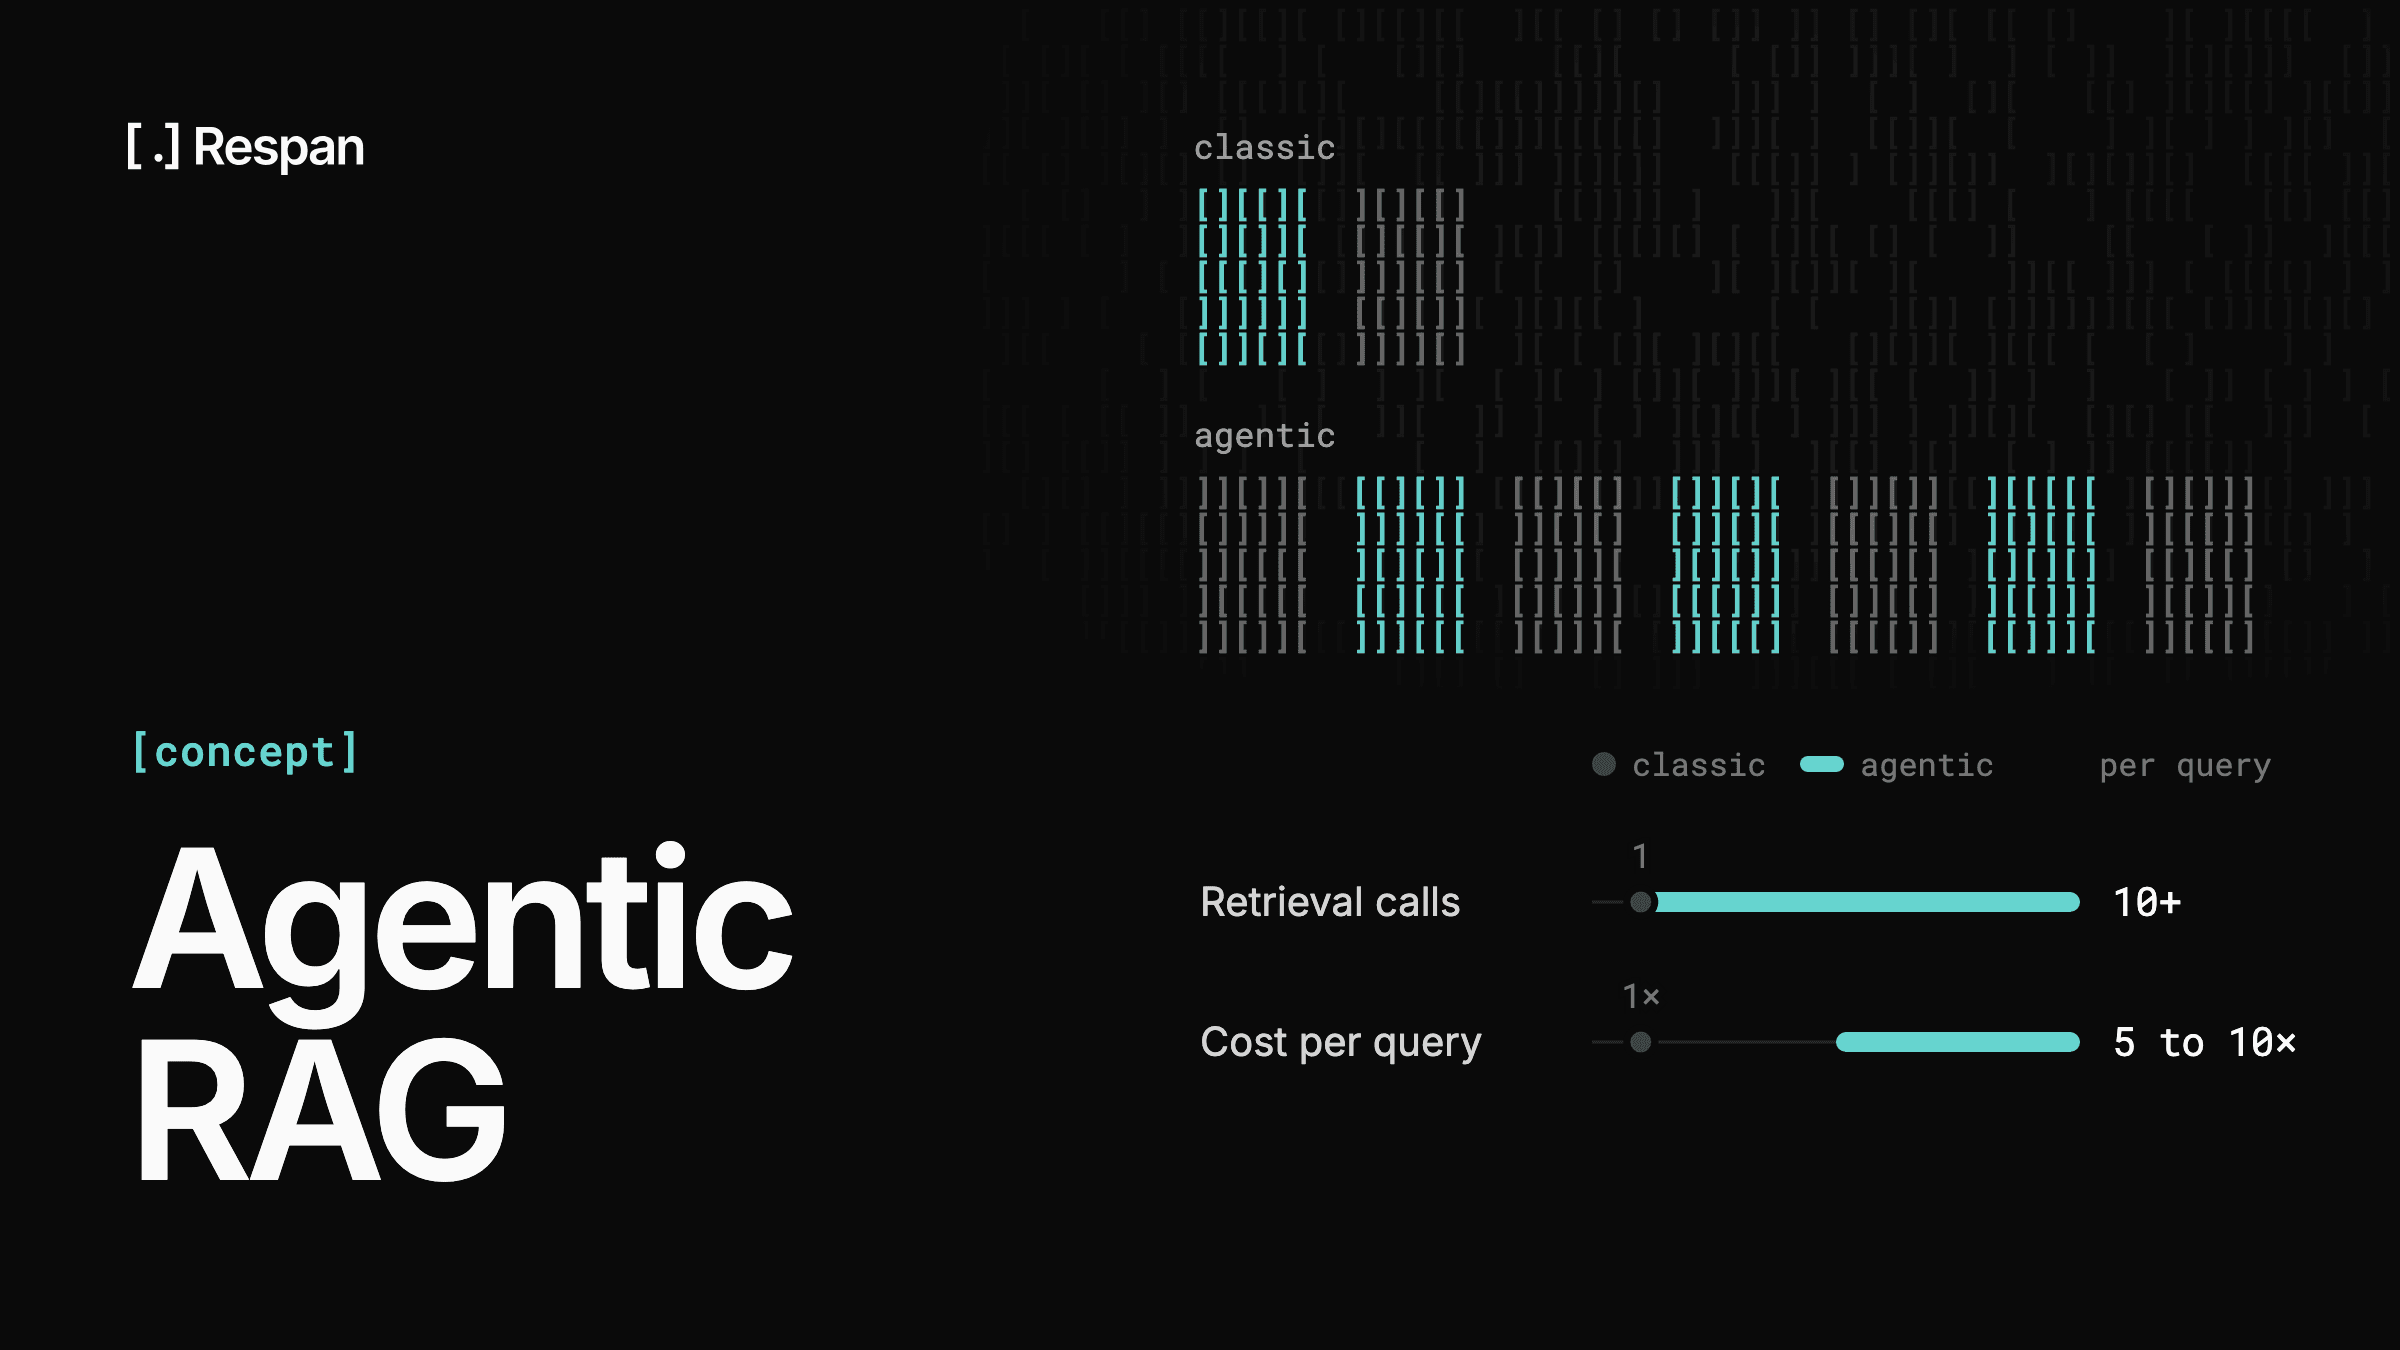
For complex queries, agentic RAG replaces single-shot retrieval with a multi-step agent that decides when to retrieve, what to retrieve, and when to stop.
5. Generation
Pass retrieved chunks + user query to an LLM with a prompt like:
Answer the user's question using ONLY the retrieved context.
If the context doesn't contain the answer, say so.

Context: {retrieved_chunks}
Question: {user_query}

Answer (with citations):
The model produces an answer grounded in the retrieved chunks, ideally with citations linking claims back to source documents.
Common production additions
Above the basic pipeline, production RAG systems usually add:
- Re-ranking: cross-encoder ranks the top-k from vector search for higher precision
- Hybrid search: combine vector similarity with BM25 keyword search; better recall on specific terms / acronyms
- Query rewriting: agent rewrites query before retrieval (handles ambiguity, expansion)
- Metadata filtering: filter retrieval by tags (date, source, language) before semantic ranking
- Citation extraction: parse model output to extract which chunks were referenced
- Eval pipeline: score retrieval quality and answer quality separately (AI evaluation platform)
Common RAG pipeline mistakes
- Bad chunking: too small, too large, or breaking on bad boundaries (mid-sentence). Chunking quality dominates retrieval quality.
- Wrong embedding model for the domain. General-purpose embeddings struggle with specialized vocabularies (legal, medical). Sometimes a fine-tuned embedding model wins.
- No re-ranking. Top-k vector search has decent recall but mediocre precision. Re-ranking is cheap relative to the quality boost.
- No retrieval evaluation. Many teams evaluate end-to-end answer quality but never measure if the right docs got retrieved. Decompose: retrieval evals separate from generation evals.
- One-shot retrieval for complex queries. Multi-hop questions need agentic retrieval.
- Skipping production observability. Tracing every retrieval + generation step is essential for debugging.
When RAG isn't the right answer
Three scenarios:
- Information fits in the prompt. If your knowledge base is under ~50 pages, just stuff it in the system prompt with prompt caching. Cheaper and simpler than RAG.
- Real-time information is needed. Use Perplexity or web search instead of indexed documents.
- Structured data Q&A. SQL or API querying often beats RAG for "what's our customer count last quarter?"
How to start
If you're building your first RAG pipeline:
- Day 1: ingest a small corpus (50-200 documents). Use OpenAI
text-embedding-3-largeand pgvector or Pinecone. Fixed-size chunks of 400 tokens with 50-token overlap. - Day 2-3: build the retrieval + generation loop. Use a modern model (Sonnet 4.6 or GPT-5.4) for generation.
- Day 4-5: build a 50-example test set sampled from real user queries. Score retrieval (was the right doc retrieved?) and generation (was the answer correct?) separately.
- Week 2: add re-ranking with Cohere Rerank or BGE Reranker. Compare scores.
- Week 3: add hybrid search (vector + BM25). Compare scores.
- Week 4: production deploy with observability and online evals.
This path gets you to a working production RAG pipeline in a month. Going faster is possible; the scoring/eval steps are what separate "demo" from "production" so don't skip them.
Tools and frameworks
- LlamaIndex: RAG-first framework, best out of the box
- LangChain: broad framework, retrievers + vectorstore wrappers
- LlamaParse: best parser for complex documents (paid)
- Respan: observability + evals over the full RAG loop
FAQ
What does RAG stand for?
Retrieval-Augmented Generation. Retrieve relevant context, augment the LLM prompt with it, generate the answer.
Do I need a vector database?
For RAG at any meaningful scale, yes. For under ~10k documents, pgvector inside an existing Postgres works. Above that, dedicated vector DBs (Pinecone, Weaviate, Qdrant) are the right call.
Which embedding model should I use?
OpenAI's text-embedding-3-large is a strong default. Voyage and Cohere are competitive. For specialized domains (legal, medical, code), test fine-tuned alternatives.
How do I evaluate a RAG pipeline?
Split into retrieval evals (was the right document retrieved?) and generation evals (was the answer correct given the retrieved docs?). Different failure modes. See our RAG evaluation guide.
What's the difference between RAG and fine-tuning?
RAG provides knowledge at inference time via retrieval. Fine-tuning bakes knowledge into the model weights. RAG is faster to update (re-index docs) and cheaper than fine-tuning. Most teams should start with RAG.
Should I use agentic RAG?
For simple queries, no, overkill. For multi-hop, ambiguous, or multi-source queries, yes. See our agentic RAG explainer.
How big should chunks be?
Common sweet spot: 200-500 tokens with 50-token overlap. Test on your specific data.