About Finta
Finta is an all-in-one accounting and finance software for startups that helps with filing taxes, automating accounting, providing financial insights, and forecasting various scenarios for the future.
AI runs throughout the Finta platform. Customers only see a small part of that surface, which is intentional. The work happens underneath, and what reaches the customer is supposed to be a correct number.
Finta's philosophy: accuracy > automation
Most AI products can get something a little wrong and survive it. Accounting can't. A transaction filed under the wrong category is a wrong number sitting in a founder's books, and it stays wrong until somebody catches it.
The failures that matter are also small. A single transaction placed in the wrong bucket, in a batch where everything else looks right.
That constraint shapes how Finta builds. Rather than trusting a single model call and shipping whatever comes back, the team puts checks in front of the output, and then checks in front of those.
Sometimes AI will hallucinate and think a small transaction is not what the right category should be. That's why we need layers and layers of evals and checks to make sure that things get through accurately.
Andy Wang
CEO of Finta
The challenge: seeing why an AI decision went wrong
Layers of checks only help if you can see what each layer did. Otherwise a bad category is just a bad category, with no way to tell whether the model misread the transaction, the prompt framed it badly, or something upstream handed it the wrong context.
Finta had the outputs. Working back from a wrong answer to the thing that produced it was the hard part.
That struggle is what brought the team to Respan.
Such a no brainer choice over LangSmith or anything else and super easy to set up.
Andy Wang
CEO of Finta
How Finta runs evals in production
AI transaction categorization is one of Finta's biggest AI use cases, and it is where the eval workflow gets the most use.
The team uploads and edits golden datasets in Respan, so every test runs against cases where Finta already knows the right answer. When a new failure mode shows up, it becomes a new evaluator rather than a note in someone's head.
What that looks like in practice:
- Golden datasets uploaded and edited in Respan, so tests run against known-correct cases
- Evaluators added as new failure modes appear
- Prompt versions tracked, so every score has a specific version attached to it
- Model and parameter testing across different models, temperatures, and variables rather than one configuration at a time
- An accuracy threshold that a change has to clear before it ships
All of it runs against that threshold. Finta defines what accuracy has to look like before a change is allowed to automate anything, and evals run continuously to check whether a given version clears it.
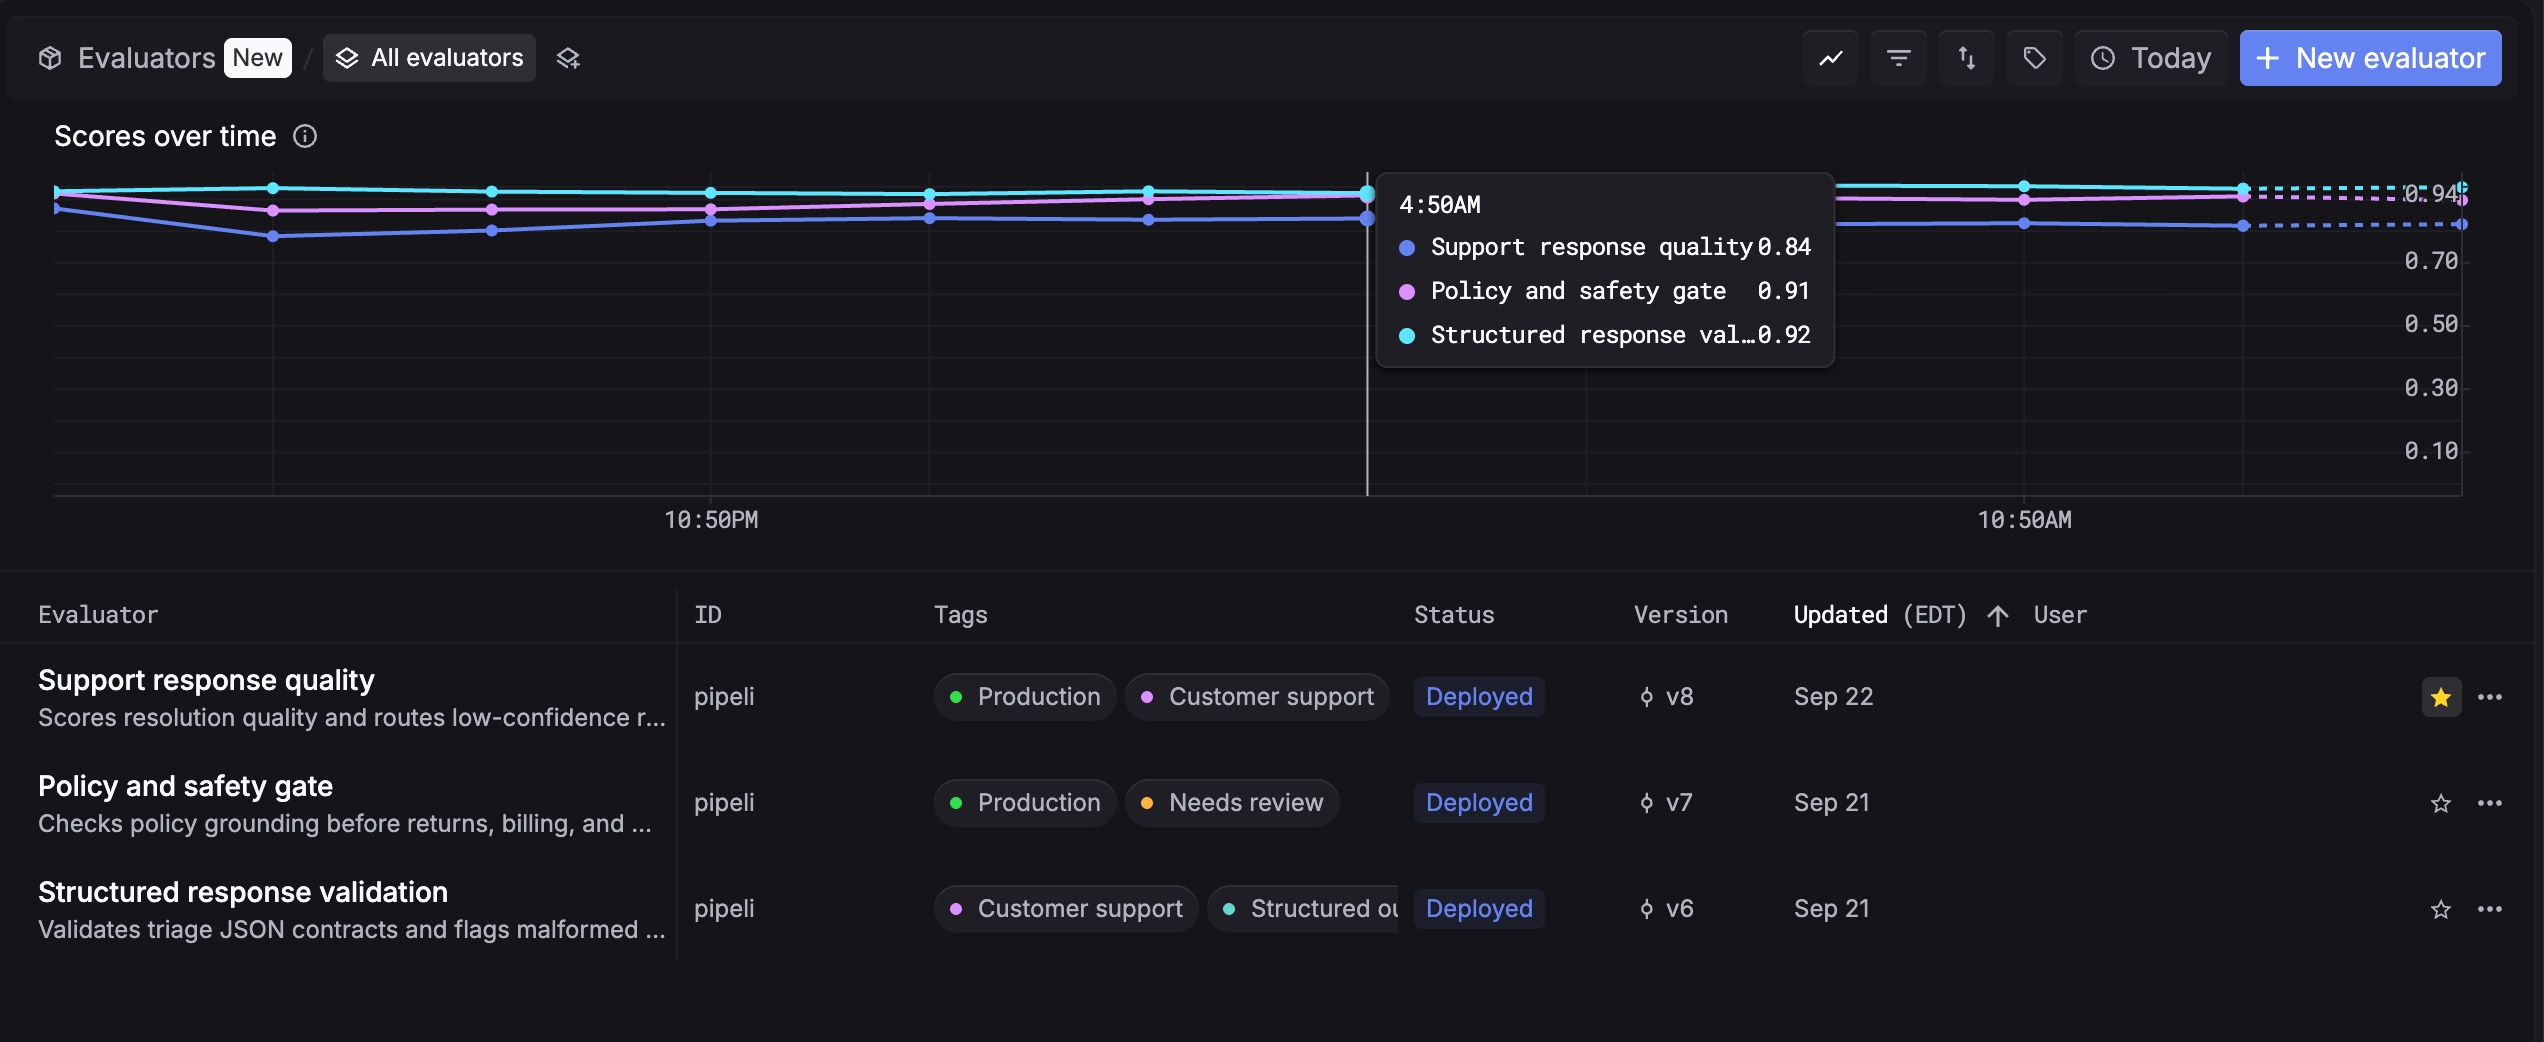
Sample data from demo.respan.ai.
Our evals are 50% more accurate using Respan.
Andy Wang
CEO of Finta
From a bad output to a shipped fix
Finding the bad output is the easy part. The slow part is everything after: working out which variable actually caused it, changing that one thing, and confirming the change helped before it ships.
With Respan, prompt versions, golden datasets, and evaluators all live in the same place, so each step feeds the next one. A version gets a score, the score points at a variable, the fix gets tested against the same dataset.
We're able to just really quickly get to the answer of what's wrong, figure out what is the knob or the variable to tweak, and then test it, confirm our hypothesis in Respan, and then just ship it and then move on.
Andy Wang
CEO of Finta
Results
Finta's team is in Respan for a few hours every single day. Evals, golden datasets, prompt versioning, and model comparison come out of the box, so none of it is infrastructure Finta has to build and maintain.
[With Respan], you get everything out of the box, they have great support, they're constantly improving the product, and it will save you so much time from building your own AI infrastructure, tracking prompts, measuring evals, and things like that, so you can actually focus on your own product.
Andy Wang
CEO of Finta