AI Evals built for
Production LLM Quality
Evaluators and datasets regression-test every prompt and model change. Online evals and alerts when production scores drop.
Ship the version that scores best.
Score every output against the bar you set, so you know it holds up on a test set and in production, instead of just hoping it does.
Every way to grade an output, in one evaluator
An LLM judge, a deterministic code check, or a human reviewer, composed into one evaluator that turns any output into a single score.
Production traffic
Sampling 2% of 12,480 requests
Test cases sampled straight from production
Pull real requests from your logs by filter and sampling rate, or upload a CSV, so every case is one your users actually sent.
See which version scores better, before you ship
Run a model or prompt against the dataset, then compare their score distributions side by side, so you ship the change that measurably wins.
Faithfulness
Scoring 5% of production spans
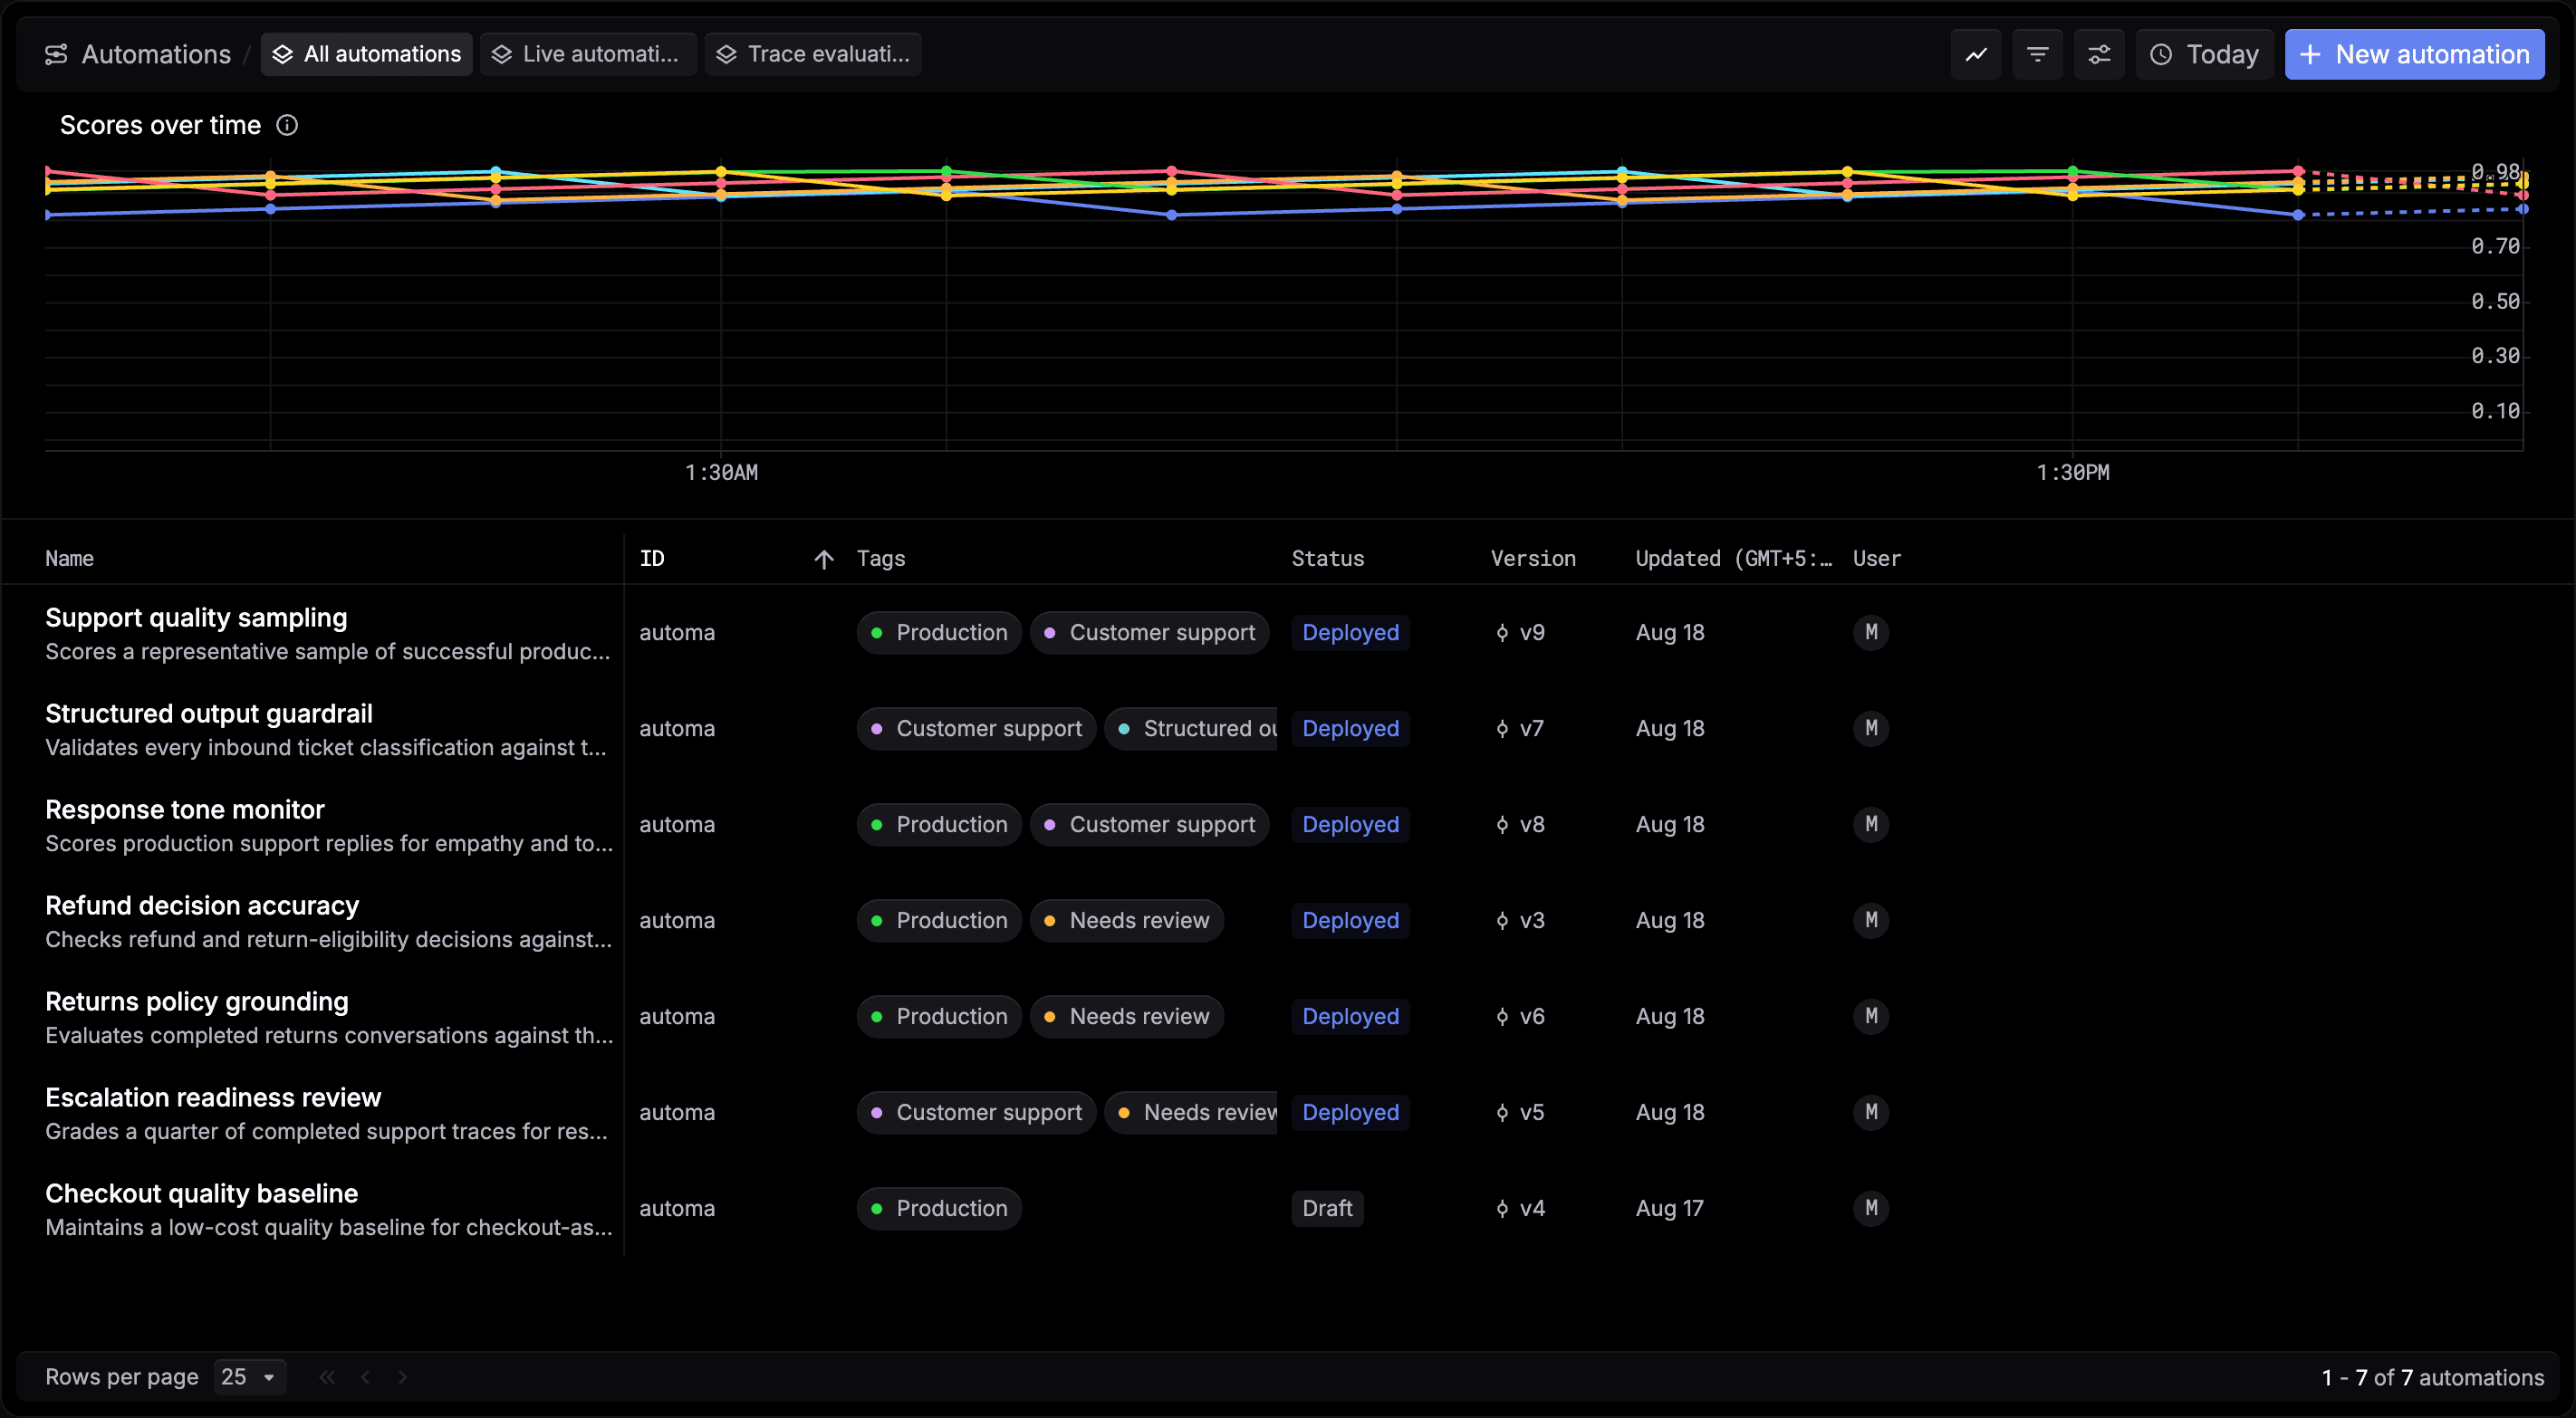
The same evaluator, now scoring live traffic
Deploy an evaluator on production spans, filtered by status, customer, or thread and sampled to control cost, so regressions surface in real time.
Quality is still an opinion.
Without a fixed set of cases and a grader you trust, a release comes down to whoever read the outputs most recently.
One number for every failure
A single quality score blends format errors, wrong facts, and the wrong tone together, so it moves without telling you which of them moved.
Nobody ever checked the judge
A model grades the answers and its verdicts get taken as truth, with no set of human-scored examples to say whether it agrees with you.
The judge changes under you
Providers retire and replace the model doing the grading, so a score that moved overnight might mean the work changed, or only the grader did.
Test cases nobody kept current
Examples written at launch, or invented wholesale, drift away from what users actually send, until passing them stops meaning very much.
Nothing stops a worse version
A prompt or model change goes out on judgement and a couple of spot checks, because nothing compares it against what is already live.
A score you cannot act on
The number says quality fell, and there is no way to open the runs behind it, so what actually changed stays a matter of guesswork.
Start with your own traffic.
Sample real requests into a dataset, chain the graders you need, and run it against any prompt or model variant.
import json def main(eval_inputs): """Pass when the output is JSON with the keys we need.""" output = eval_inputs["output"] if isinstance(output, str): try: output = json.loads(output) except (ValueError, TypeError): return False if not isinstance(output, dict): return False required = {"category", "priority", "sentiment"} return required.issubset(output.keys())import json def main(eval_inputs): """Pass when the output is JSON with the keys we need.""" output = eval_inputs["output"] if isinstance(output, str): try: output = json.loads(output) except (ValueError, TypeError): return False if not isinstance(output, dict): return False required = {"category", "priority", "sentiment"} return required.issubset(output.keys())The AI observability platform behind 80 trillion+ tokens.
Loved by world-class founders, engineers, and product teams.
“Imagine jumping to a log immediately after every LLM call. This is the dream for debugging.”
Daniel Wolf
Product Lead, AlphaSense
“We scaled from 5M to 500M+ monthly API calls quickly. Respan gave us the debugging layer to resolve production issues 10x faster.”
Read how Retell builds next-gen voice agents that scale->Zexia Zhang
CTO, Retell AI
“Respan legit has some of the best UX/DX I’ve ever seen in my life. I truly don’t think I’ve ever integrated a product that was as easy.”
Rahul Behal
Co-founder, Gumloop
“This one felt pretty nice.”
Fabian Hedin
CTO, Lovable
“Such a no brainer choice over LangSmith or anything else and super easy to set up.”
Andy Wang
CEO, Finta
“Respan has been key in helping us scale to trillions of tokens reliably with real-time observability.”
Read how Mem0 builds reliable self-improving AI memory layer->Deshraj Yadav
CTO, Mem0
“Great product - really love the metrics dashboard.”
Esha Dinne
CTO, Giga
Certified where it counts.
Built to meet the security and privacy standards that enterprise and healthcare teams require.
ISO 27001
The internationally recognized standard for information security management.
SOC 2
Secure, compliant management of your data across all of our systems.
GDPR
Operated under GDPR, the world's strictest standard for data privacy.
HIPAA
HIPAA compliant, with a BAA available for healthcare teams.
Works with your entire stack
Use Respan with your favorite frameworks and tools.

