Anthropic shipped Claude Fable 5.1 and Claude Mythos 5.1 together on September 1, and developers have been sorting out what separates them ever since. Anthropic describes them as the same model running under different levels of safeguards, and on paper that is the entire difference.
For a team running agents in production, the safeguard level decides which requests come back with an answer and which come back as a refusal. It also decides whether Mythos is an option at all, because access runs through Anthropic's verification programs rather than a pricing page.
Fable 5.1 is the right default for nearly every team. Mythos 5.1 is worth the application only when Fable's restrictions are blocking work your organization is cleared to do.
Here is how Claude Fable 5.1 vs Mythos 5.1 compares, and which one to use in 2026.
TLDR: Fable 5.1 vs Mythos 5.1
Claude Fable 5.1 and Mythos 5.1 are the same model at the same price, with the same 1M token context window and 128K max output. Mythos 5.1 relaxes the restrictions Fable 5.1 applies to cybersecurity and biology work, and it posts the higher score on the one benchmark Anthropic reports for both: 60.9% on Terminal-Bench 4.0 against Fable's 55.8%.
| Fable 5.1 | Mythos 5.1 | Winner | |
|---|---|---|---|
| Terminal-Bench 4.0 | 55.8% | 60.9% | Mythos 5.1 |
| Cybersecurity | Declines exploits and pen testing | Relaxed for verified orgs | Mythos 5.1 |
| Life sciences | Restricts advanced biology | Relaxed for enrolled orgs | Mythos 5.1 |
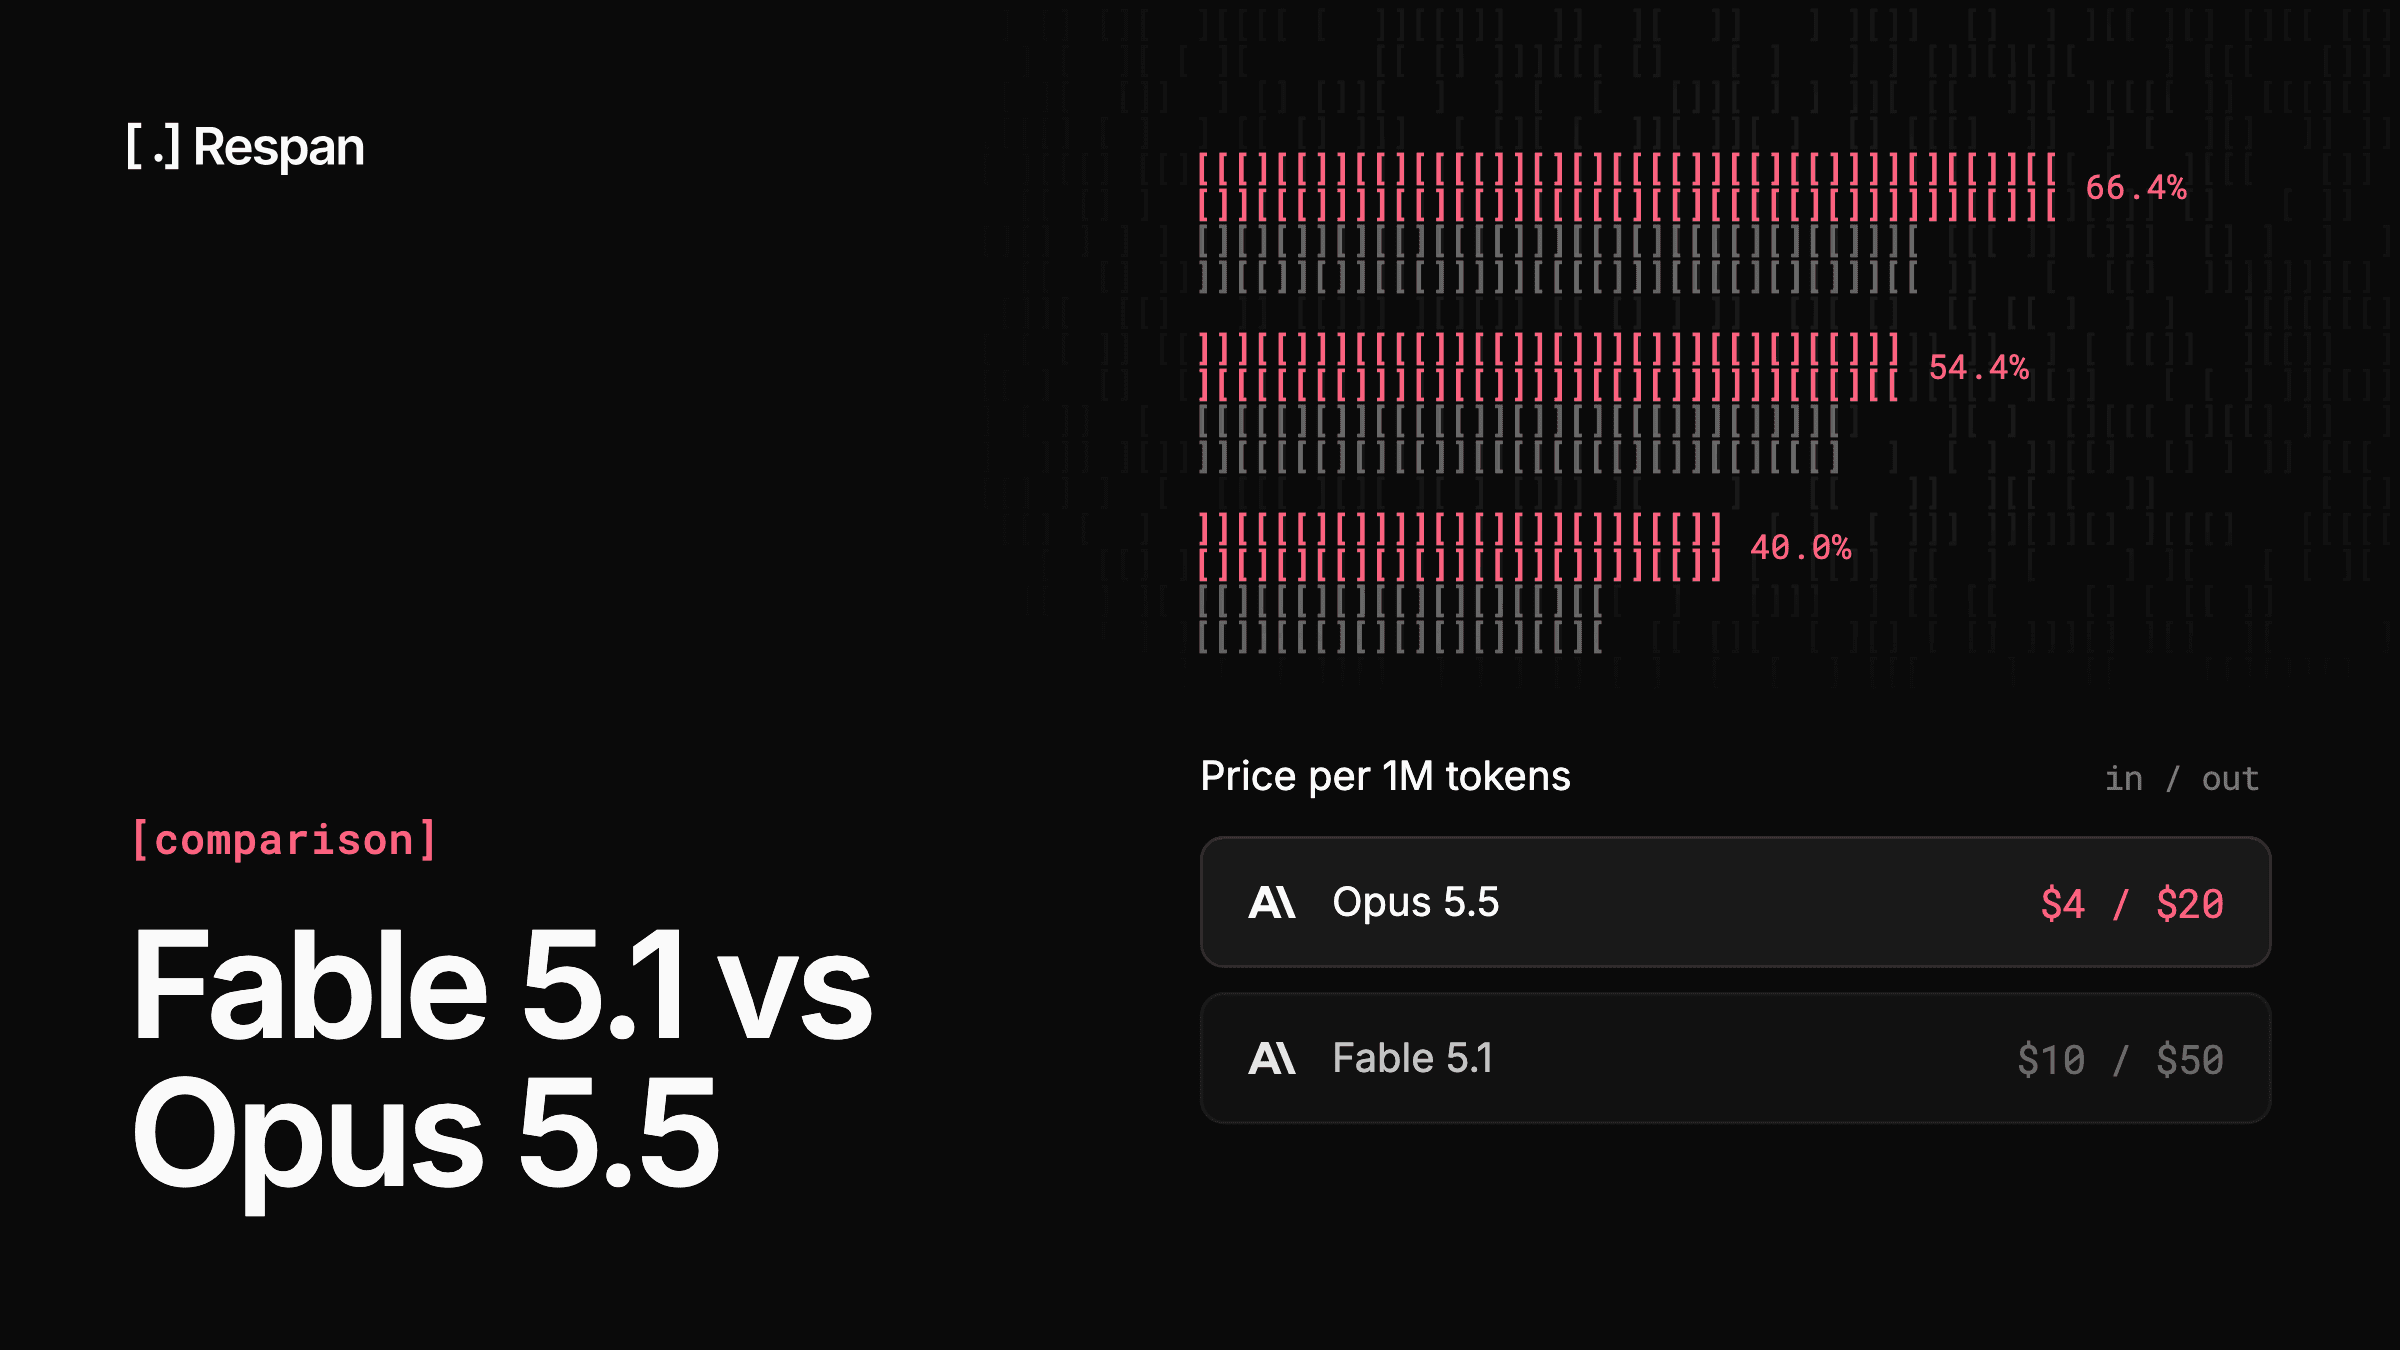
| Pricing (per 1M tokens) | $10 input / $50 output | $10 input / $50 output | Tie |
| Context / max output | 1M / 128K | 1M / 128K | Tie |
| API behavior | Validates edited history | Skips history check | Mythos 5.1 |
| Availability | Generally available | Verified US orgs only | Fable 5.1 |
The catch is access. Fable 5.1 is generally available, while Mythos 5.1 is limited to verified US organizations, so pick Fable 5.1 unless you qualify for Mythos and Fable's restrictions are blocking legitimate security or life-sciences work.
What is Claude Fable 5.1?
Claude Fable 5.1 is the generally available version of the model Anthropic released on September 1, 2026, aimed at demanding reasoning and long-horizon agentic work. It runs adaptive thinking on every request with effort levels from Low to Max, and Anthropic reports large gains over Fable 5 on long-running tasks, including 52.6% on Terminal-Bench-Science 0.1 against Fable 5's 24.7%.
The price of general availability is a set of classifiers that decline certain cybersecurity and biology requests. Those restrictions are what separate it from Mythos 5.1.
What is Claude Mythos 5.1?
Claude Mythos 5.1 shares Fable 5.1's specifications and pricing, and relaxes the restrictions on cybersecurity and life-sciences work for organizations Anthropic has verified.
It replaces Mythos 5, which launched alongside Fable 5 in June, and Anthropic recommends migrating to the newer version. Because access is limited to US organizations, the audience narrows well before capability enters the decision.
Claude Fable vs Mythos: Key Differences
Benchmarks
Fable 5.1: Anthropic reports 55.8% on Terminal-Bench 4.0 for agentic coding, along with published results across science, computer-use, and knowledge-work suites, including 73.4% on CursorBench 3.2.0.
Mythos 5.1: Terminal-Bench 4.0 is the only benchmark Anthropic publishes for Mythos 5.1, where it scores 60.9%.
Winner: Mythos 5.1, on the one suite where both have a score. Anthropic describes the two as the same model, so the five-point gap comes from what each one is allowed to finish rather than from different underlying capability.
Cybersecurity safeguards
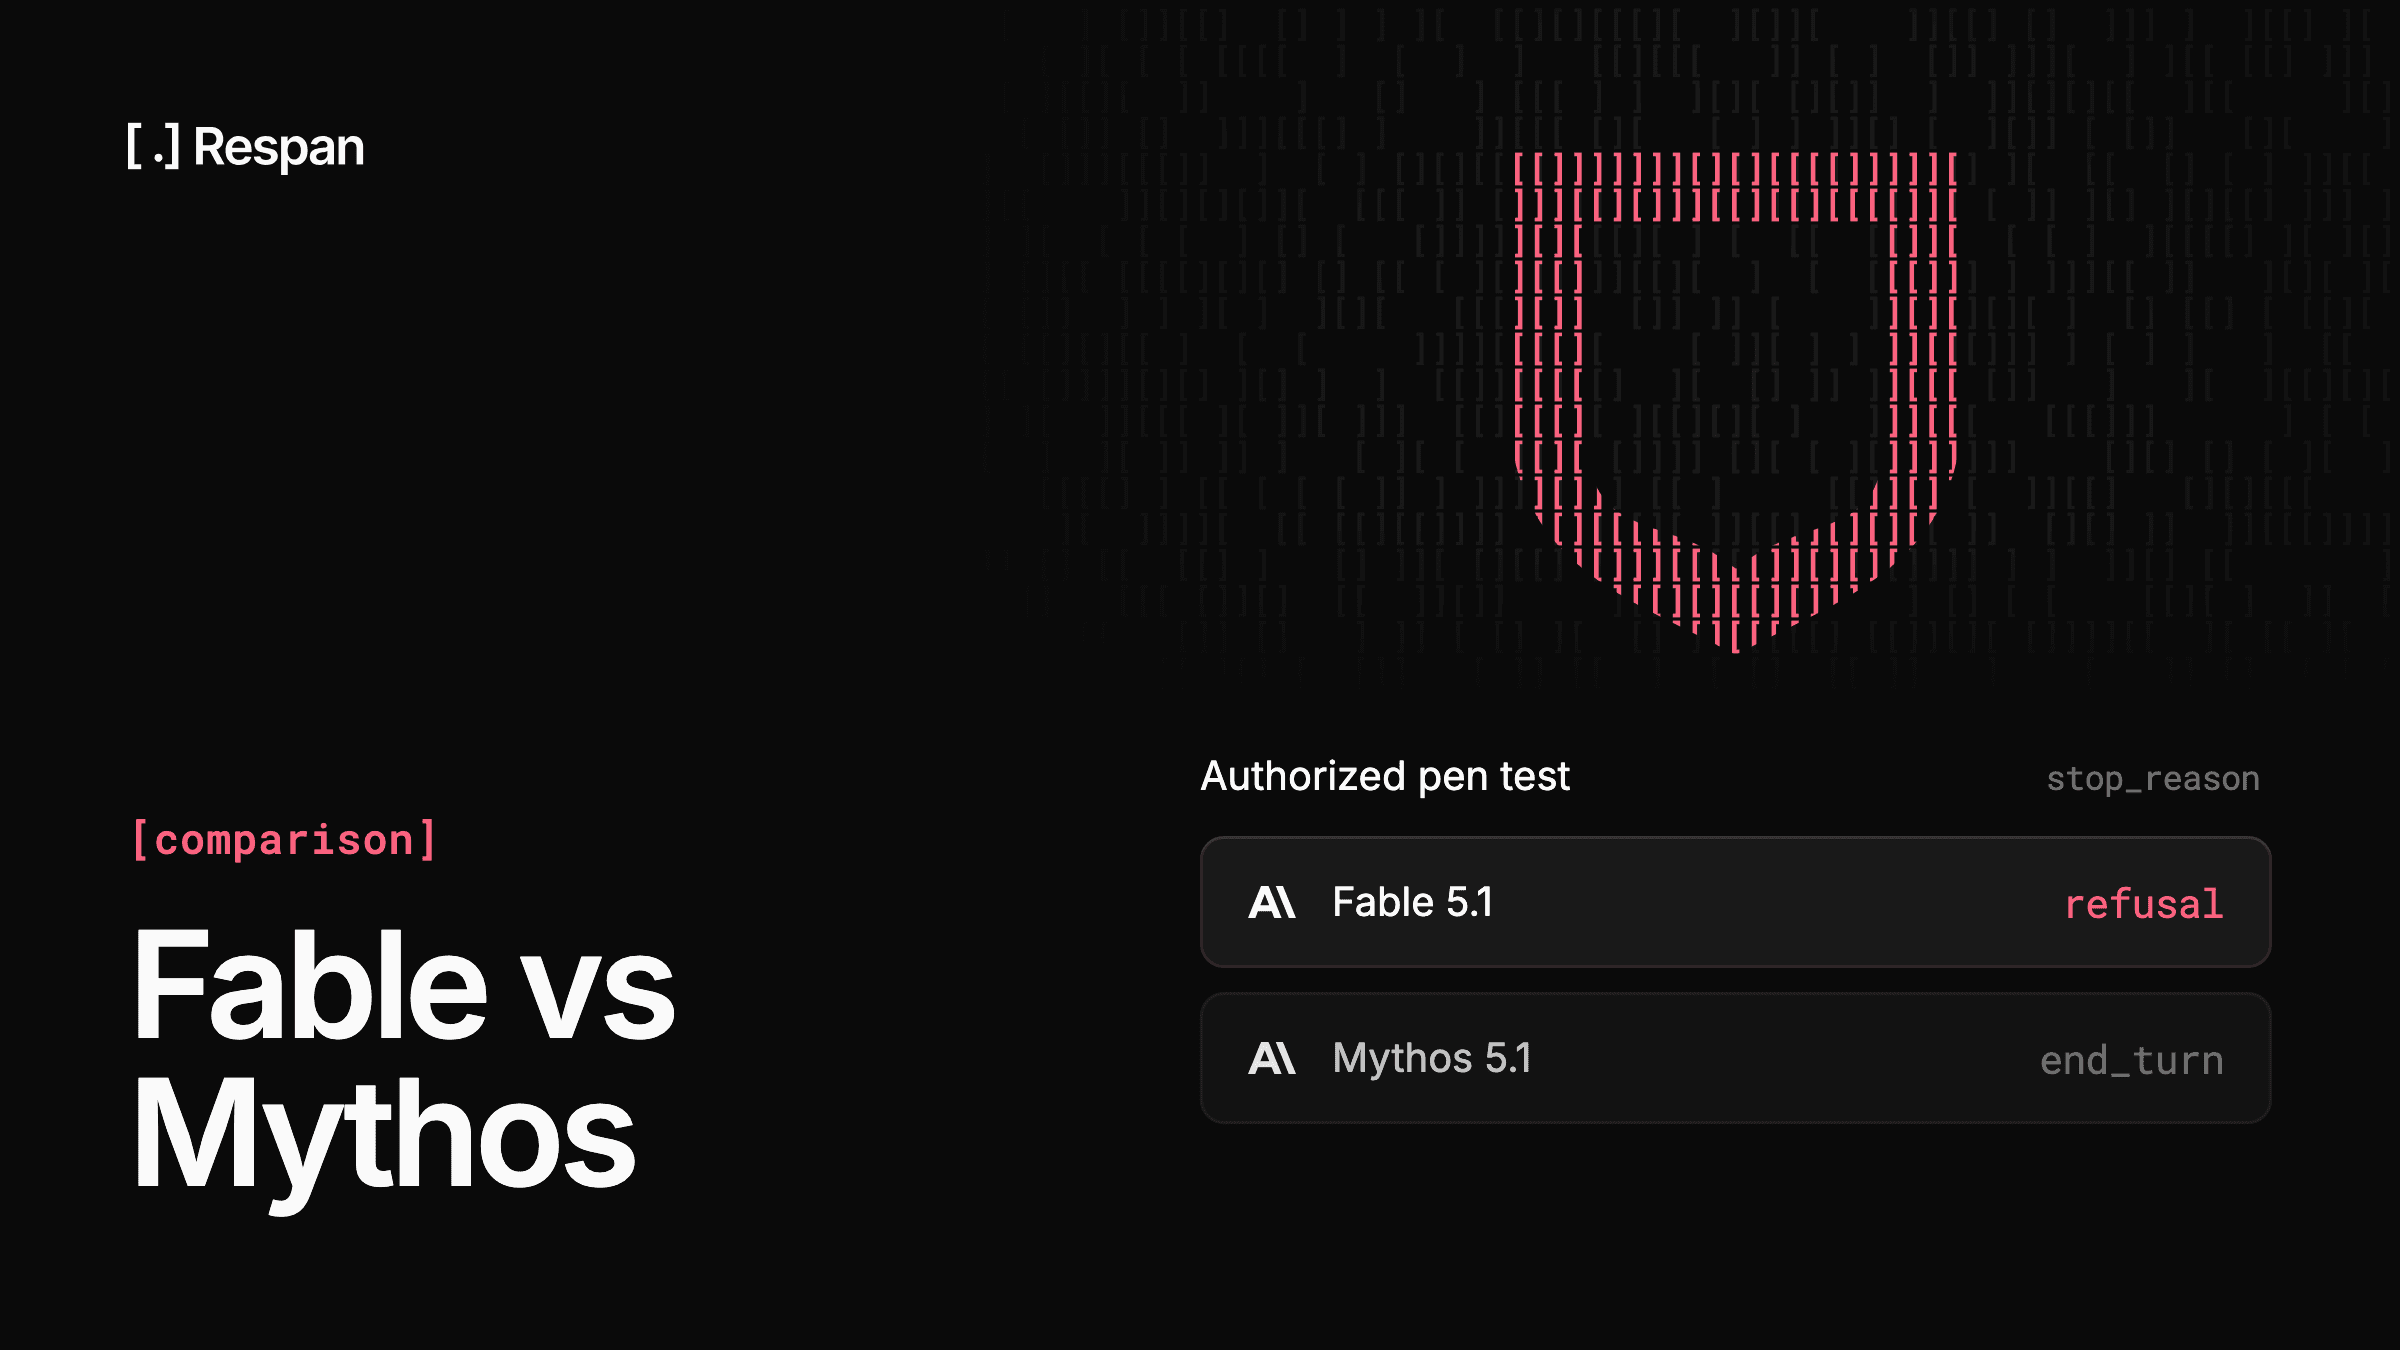
Fable 5.1: Defensive vulnerability discovery is supported, but the classifiers decline penetration testing and exploit generation. Anthropic reports its updated cyber safeguards block 60% fewer false positives than before.
On the API, a declined request returns stop_reason: "refusal" with the policy category, and retrying on another Claude model is opt-in, since Anthropic's refusal and fallback behavior requires the fallbacks parameter and a beta header on each call. When a fallback runs, response.model shows which model actually answered, and each attempt bills at that model's rates.
Mythos 5.1: Verified security organizations get reduced cyber restrictions, which brings offensive work like authorized penetration testing into scope.
Winner: Mythos 5.1 for verified security teams doing offensive work. For defensive vulnerability discovery, Fable 5.1 handles the job without an application.
Life sciences safeguards
Fable 5.1: Advanced biology research falls under Fable 5.1's restrictions, so requests in that category can be declined the same way cyber requests are.
Mythos 5.1: Anthropic runs the Life Sciences Verification Program in partnership with the US government, and enrolled organizations get Mythos 5.1 with those biology restrictions relaxed. Anthropic says enrollment is expanding to the broader life sciences community.
Winner: For enrolled life-sciences organizations, Mythos 5.1. Everyone else is on Fable 5.1 by default.
Pricing
Fable 5.1: $10 per million input tokens and $50 per million output tokens, with cache reads at $0.25 per million, according to Anthropic's pricing. Cache reads cost 0.025 times the base input price compared with 0.1 on other Claude models, which makes Claude prompt caching worth setting up for any agent that resends long context on every turn.
Mythos 5.1: The rates match Fable 5.1 line for line, including cache writes at $12.50 per million tokens for 5 minutes and $20 for 1 hour, plus the 50% batch discount.
Winner: Tie. Paying more doesn't unlock Mythos, so cost never decides between them.
Context window and output limits
Fable 5.1: A 1M token context window and up to 128K output tokens per response.
Mythos 5.1: The same 1M context window and 128K output ceiling, since Anthropic ships Mythos 5.1 with Fable 5.1's specifications.
Winner: Tie, since long-context workloads behave identically on both.
API behavior
Fable 5.1: Editing anything before a Fable 5.1 thinking block, whether the system prompt, the tool list, or an earlier message, is one of the breaking changes in Fable 5.1, and the next request either errors or drops the block. Forced tool use also returns a 400, so a tool_choice set to any or a named tool needs a workaround like strict tool use.
Earlier models also can't read Fable 5.1's thinking blocks, so a conversation that falls back to one loses Fable's reasoning for those turns.
Mythos 5.1: Mythos 5.1 skips the thinking-block prefix check, so agents that rewrite their system prompt or tools mid-conversation won't hit that error. Forced tool use is still unsupported.
Winner: Mythos 5.1, narrowly, and only if your agent edits earlier context. Otherwise the two behave the same at the API level.
Availability and access
Fable 5.1: Generally available on the Claude API, Amazon Bedrock, Google Cloud Vertex AI, and Microsoft Foundry, as well as in Claude's apps and Claude Code. Choosing between the Anthropic API, Bedrock, or Claude Platform on AWS mostly comes down to billing and where the rest of your infrastructure runs.
Mythos 5.1: Limited to US organizations verified through Anthropic's Cyber Verification Program, which now includes former Project Glasswing members, or its Life Sciences Verification Program. Once access is granted, the same four API platforms serve it.
Winner: Fable 5.1, since any team can call it today.
Which to Use: Fable 5.1 vs Mythos 5.1?
Use Claude Fable 5.1. It's the same model as Mythos 5.1 at the same price, and you can call it today on any of the major clouds. Its restrictions apply to offensive security and advanced biology work, which may never come up in what your agents do.
Mythos 5.1 is worth applying for when your organization is US-based, does security or life-sciences work Anthropic can verify, and is losing real work to Fable's refusals. Security firms running authorized penetration tests and labs enrolled in the life sciences program fit that description.
Fable 5.1 also costs more per token than Opus 5.5 or Sonnet 5.5, so for workloads that don't need long-horizon agentic work, the Claude Fable vs Opus decision matters more than the Mythos one. Before routing every request to Fable, a Claude model comparison shows where the cheaper models hold up.
Run Claude Fable 5.1 in Production with Respan
Running Claude Fable 5.1 in production means paying $50 per million output tokens on every long agent loop, and an outage at your provider takes your most capable model down with it. Respan's AI gateway routes every model call through one API, and Claude Fable 5.1 on Respan sits alongside 1,000+ other models, so every request is traced, priced, and ready to score in the same place.
Route, observe, and evaluate every LLM call. Instead of reading logs after the fact, use Respan to run observability in production, know when production shifts, and act before it spreads.
- One API for every model - Call Fable 5.1 or any of 1,000+ models through one endpoint, and switch between them by changing a single word.
- Stay up when a provider fails - Set a fallback chain once, and Respan moves to the next model when a provider errors or rate-limits. The log shows which model served each request.
- Know where every dollar goes - See Fable 5.1 spend broken down by model, request, and end customer, with hard spend limits that stop a runaway agent at the ceiling.
- See exactly what your agents did - Every LLM call, tool run, and agent turn lands in one trace with its own input, output, latency, and cost.
- Catch regressions before users do - Score output on a test set built from real production data before you ship a model or prompt change, then run the same evaluators on live traffic.
- Ship prompts without shipping code - Version prompts outside your codebase, and your application picks up the new version the moment you publish.
At Fable 5.1's output price, the gap between watching spend per request and finding it on the invoice gets expensive quickly.
FAQ
How do I get access to Claude Mythos 5.1?
Apply through one of Anthropic's verification programs. Security organizations apply to the Cyber Verification Program, and life-sciences organizations go through the Life Sciences Verification Program, which Anthropic runs with the US government. Access is currently limited to US organizations, and Anthropic's docs also point customers to their Anthropic, AWS, or Google Cloud account team.
When will Claude Fable 5.5 be released?
Anthropic hasn't announced Claude Fable 5.5 or a release date as of October 2026. Fable 5 shipped on June 9, 2026 and Fable 5.1 followed on September 1, and Anthropic has said it is working to bring Fable 5.1's improvements to the rest of its model family.
When a new version does ship, teams on Respan can run it against a dataset built from their own production traffic before moving any requests over.
When will Claude Mythos 5.5 be released?
There's no announcement for Claude Mythos 5.5 either. Every Mythos release so far has shipped alongside its Fable counterpart, with Mythos 5 arriving with Fable 5 in June and Mythos 5.1 with Fable 5.1 in September. If that pattern holds, a Mythos 5.5 would arrive with Fable 5.5.