OpenRouter comes up constantly in developer threads, usually from people who started with it for a prototype and are now asking what to move to. It's a fair question, since OpenRouter makes getting started easy: one key, one balance, and an OpenAI-compatible endpoint that most SDKs accept with a changed base URL.
The questions change once an agent is in production. A response comes back with a 200 and normal latency, and the activity log shows the model, the token count, and the cost. What it can't tell you is which tool call returned garbage or whether a fallback fired. Add a compliance review asking where requests travel, and the tradeoffs that were fine for a prototype start to matter.
The alternatives worth a look are the ones that answer those questions, either by running where your policies require or by recording what happened inside each request. Catalog size matters less than either.
Here are 12 OpenRouter alternatives and competitors for LLM routing, compared on where each one runs and what it records.
TL;DR: OpenRouter Alternatives Compared
Respan replaces the router and keeps traces, evals, and spend caps against the same request. The rest split between self-hosted gateways, platform-tied gateways, and hosted routers that work much like OpenRouter does.
| Tool | Model access | Deployment | Observability | Fee on tokens | Pricing |
|---|---|---|---|---|---|
| Respan | 1,000+ models | Cloud | Traces, evals, prompts | No fee on credits; BYOK | Free, $199/mo Team |
| Portkey | 1,600+ models | Cloud, OSS, Enterprise VPC | Logs, traces, cost analytics | Bills per log, not tokens | Free, $49/mo Production |
| LiteLLM | 140+ providers | Self-hosted | Logs, spend tracking | None; self-hosted | Free OSS, Enterprise custom |
| Cloudflare AI Gateway | Major providers, Workers AI | Managed only | Logs, analytics, OpenTelemetry | 5% on Unified Billing credits | Free with Cloudflare plan |
| Bifrost | 1,000+ models | Self-host, Enterprise VPC | Built-in, OpenTelemetry export | None; self-hosted | Free OSS, Enterprise custom |
| TrueFoundry | 1,600+ models | Hosted, Enterprise VPC | Request logs, budgets | Provider billed separately | Free, $25/user/mo Pro |
| LLM API | 400+ models | Managed, region options | Dashboards and analytics | Provider's published rate | Pay-as-you-go, Enterprise discounts |
| Requesty | 600+ models | Managed, EU region | Logs and analytics | 5% on top-ups | Free, pay-as-you-go |
| Vercel AI Gateway | Hundreds of models | Managed only | Logs, metrics, OTel trace drains | None; processing fees apply | $5 monthly credits, add-ons |
| Helicone | Provider-agnostic proxy | OSS self-host, cloud | Request logs, cost tracking | 0% markup; processing fees | Free, $79/mo Pro |
| Kong AI Gateway | Provider-agnostic plugins | Self-host, hybrid, cloud | Request-shaped metrics | $100/mo per model | $25-$500/mo per control plane |
| Merge | Major providers | Managed, Enterprise VPC | Routing decision logs | 5%; BYOK $0.05/M tokens | Free, pay-as-you-go Pro |
What Is OpenRouter?
OpenRouter is a hosted router that puts models from many providers behind a single OpenAI-compatible API and a single prepaid balance. You send a request naming a model, OpenRouter picks a provider for it, and the cost is deducted from your credits. The catalog covers 500+ models across 80+ providers.
It doesn't host models. Like other LLM gateways, it sits between your application and the inference providers, normalizing request formats and falling back to the next provider when one returns an error. Prompts and completions aren't logged by default, and opting into logging earns a 1% discount on usage.
Inference passes through at the provider's list rate, and the business runs on a fee charged when you buy credits: 5.5% with an $0.80 minimum on the Standard plan, 5% on crypto payments, and 8% on the Business plan. That floor is the part that surprises people, because it turns a $5 top-up into an effective 16% fee.
Bring-your-own-key usage is free up to $25,000 of list-price inference per month, then 5%. Unused credits can be expired 365 days after purchase, and refunds are only available within 24 hours, with the remaining plan details covered in OpenRouter pricing.
Stripe agreed to acquire OpenRouter in August 2026, which is worth knowing if you're weighing a multi-year commitment to its routing layer.
Why Look for an OpenRouter Alternative
A missing model is rarely the reason to leave OpenRouter, since its catalog covers 500+ models. What tends to show up first is one of these:
- The third-party hop - Every request goes through OpenRouter's infrastructure before it reaches a provider. Enterprise adds EU and US in-region routing, but there's no self-hosted build or VPC deployment, so a policy that model traffic stays inside your own network has no configuration that satisfies it.
- No trace behind the routing decision - Activity logs record the model, tokens, and cost per request. An agent that chains retrieval, several tool calls, and a summarization step produces one line per model call and no way to see which step went wrong or whether the answer degraded.
- Free tier ceilings - Free models are capped at 50 requests per day, rising to 1,000 per day once you've purchased $10 in credits. That's enough for prototyping, not for anything with users.
- Cost structure at volume - The fee lands on top-ups rather than usage, so it's invisible in per-request math and shows up in accounting instead. Breaking spend down by customer or feature means structuring keys around it or instrumenting it yourself.
The common thread is that OpenRouter optimizes for breadth and speed of adoption, while the teams that outgrow it need control over where traffic runs and a record of what happened inside it.
12 OpenRouter Alternatives for LLM Routing
1. Respan
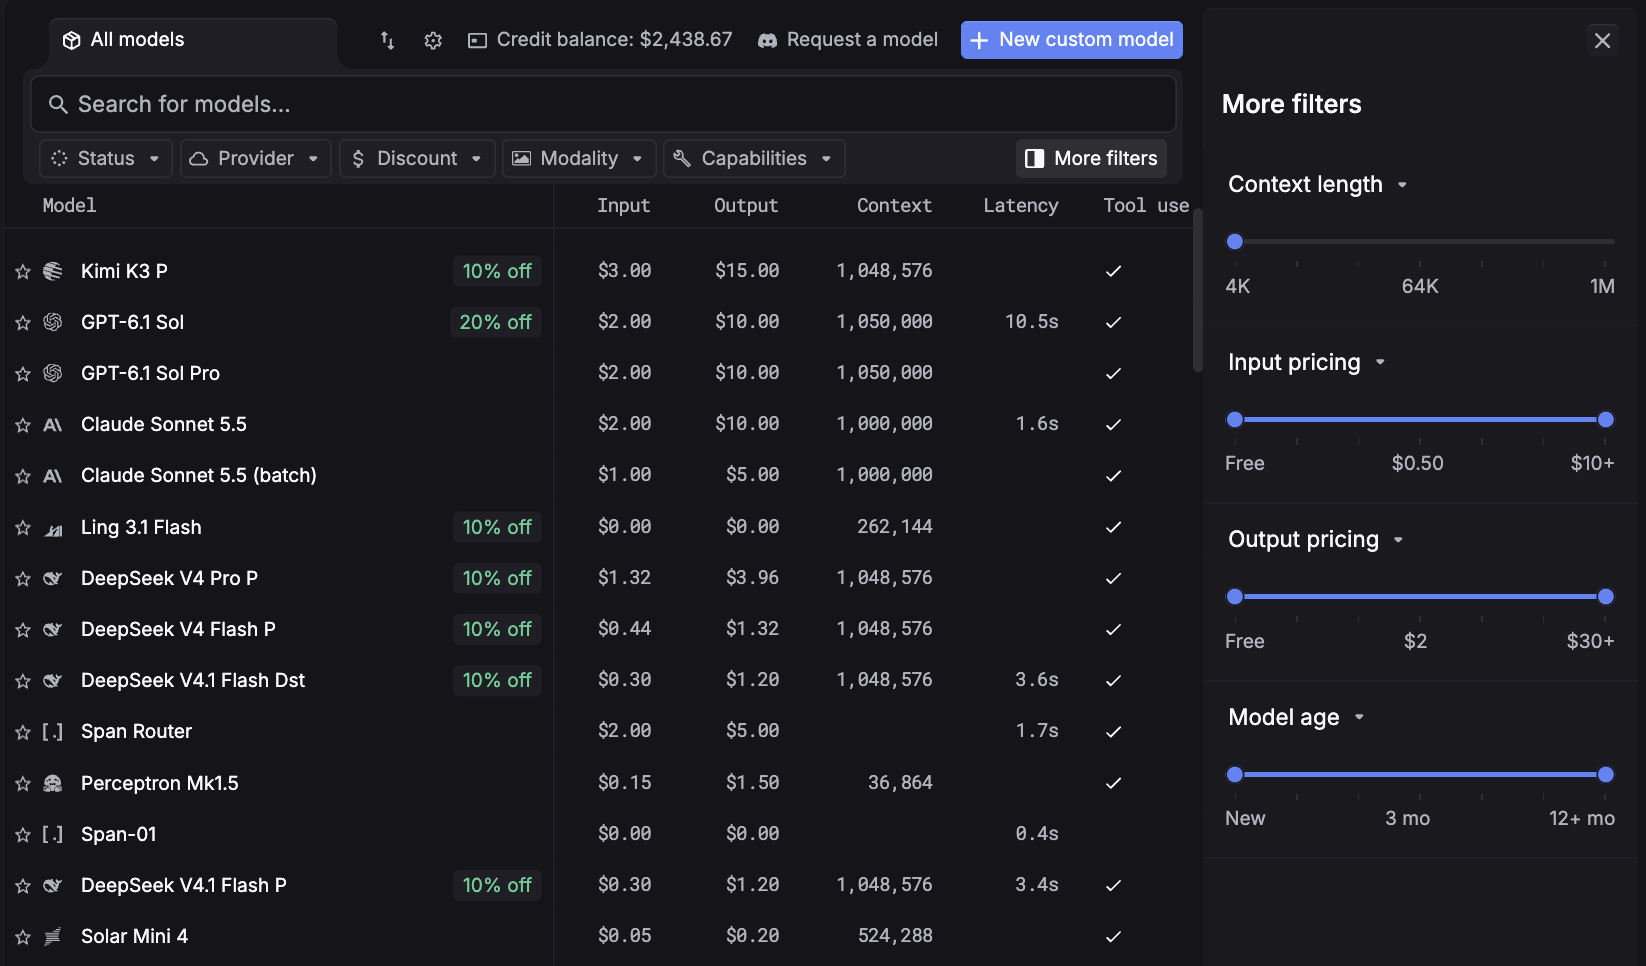
Leaving a hosted aggregator usually means assembling what it replaced: a router, somewhere to send logs, an eval harness, and a place to keep prompts. Respan puts all four in one platform, so a metric always ties back to the run behind it. Route, observe, and evaluate every LLM call from any model.
Point your client at a single OpenAI-compatible endpoint and every request is logged automatically, whether it goes through the unified router or a provider's native passthrough URL. Because the routing layer and the measurement layer are the same product, a fallback that fired and the eval score for the output it produced sit against the same request ID instead of being reconciled across two vendors.
With traffic running through Respan, teams get the following:
- Stay up when a provider fails - Ordered model fallback turns an upstream error into the next model in your list, with load balancing across keys and automatic retries.
- See exactly what your agent did - Every prompt, tool call, retrieval, and response renders as one trace tree with latency on each span, so a bad output resolves to the step that caused it.
- Know whether a change helped - Rule-based checks and LLM-as-a-judge evaluators score live production traffic, so a prompt edit is measured rather than argued about.
- Know where every dollar goes - Requests, tokens, errors, latency, and cost break down by model, user, and API key, with soft warnings or hard caps per key before the invoice arrives.
- Debug by tenant or feature - Tag requests with a customer identifier and metadata, then break down latency, errors, and eval scores by any of them.
- Ship prompts without a deploy - Versioned prompts referenced by ID, with one-click deployment and release management.
- Test what your agents block - Red teaming probes deployed agents on your schedule rather than an attacker's.
- Screen requests before any provider sees them - Respan Guardrails, in early access, block requests in categories like prompt injection or system prompt leak inside the gateway, so a blocked request never leaves for a model provider.
- Pass the review you're also running - SOC 2, ISO 27001, GDPR, and HIPAA with a BAA available.
Because every routed request is already a trace, moving off OpenRouter doesn't mean adding a second vendor for logs and a third for evals.
Model access & deployment: 1,000+ models through one OpenAI-compatible endpoint, cloud-hosted, with SAML SSO on Enterprise.
Pricing: Respan credits carry no processing fee and pass through any provider discount Respan gets, or you can bring your own provider keys. Free covers 100k logs, 412 requests per minute of gateway throughput, and 7-day retention. Team is $199 per month billed yearly, raising throughput to 8,400 requests per minute with 30-day retention. Additional logs are $8 per 100k.
Limitations: Log caps are real on the free tier.
2. Portkey
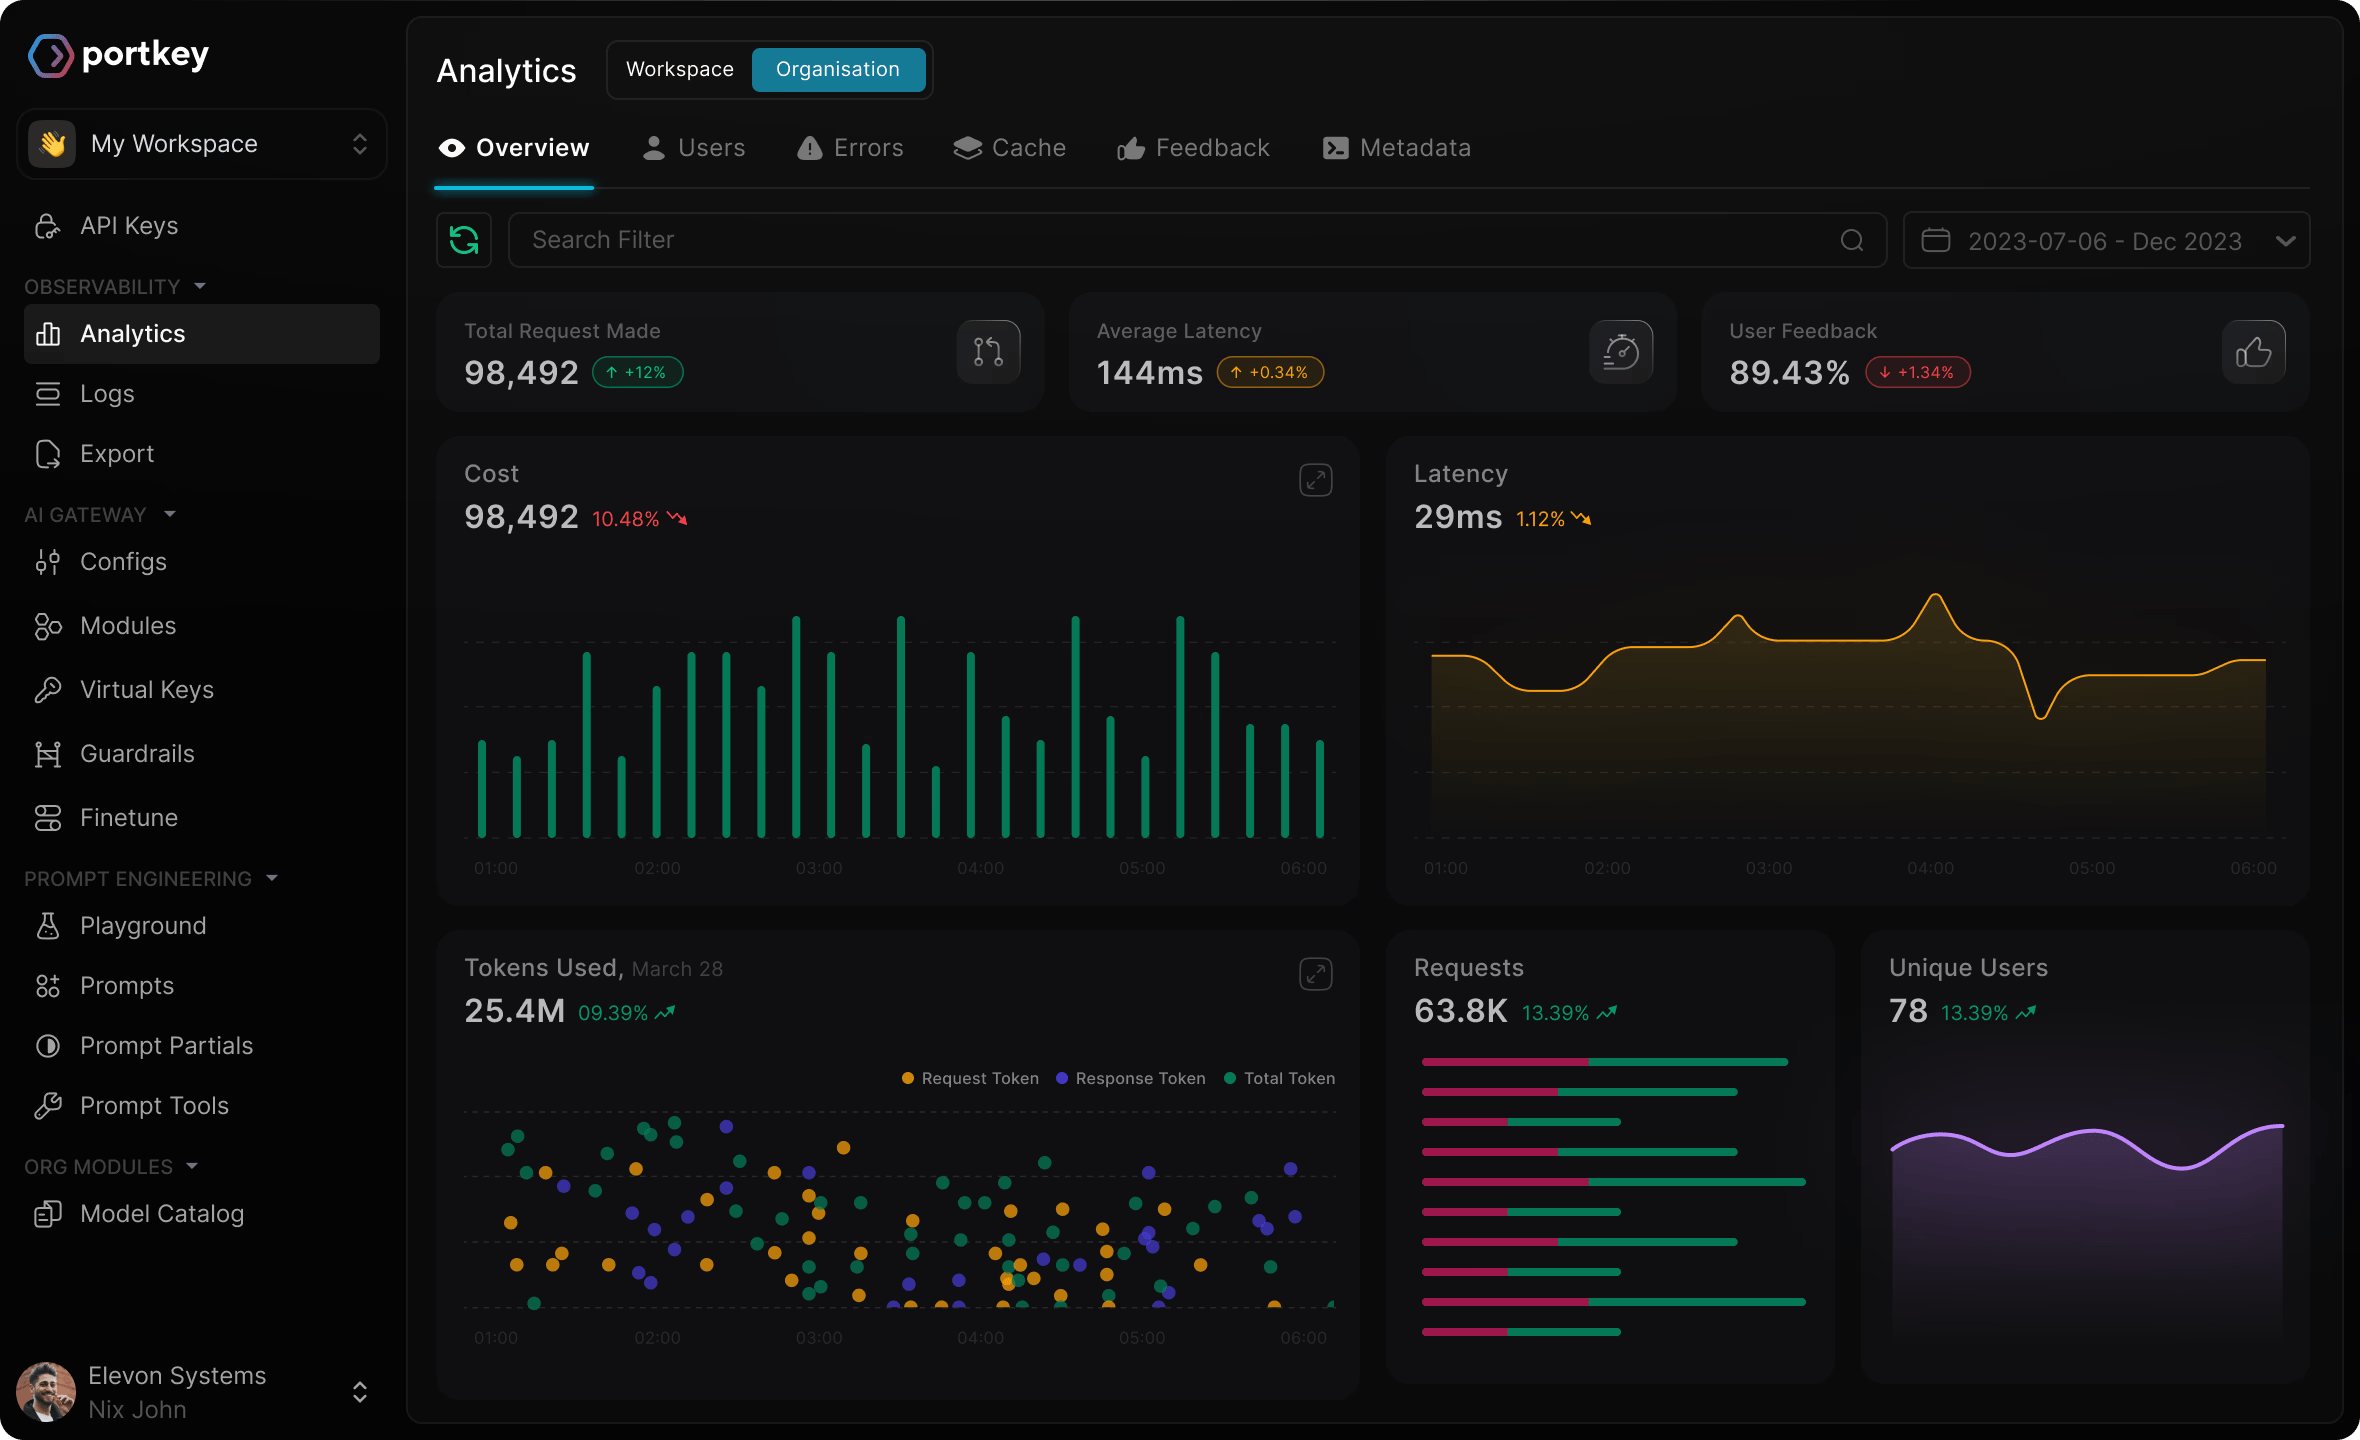
Portkey is a managed gateway with a control plane on top of the routing layer. Automatic fallbacks, load balancing, retries, request timeouts, circuit breakers, and both simple and semantic caching are configured in a Config object rather than in application code. Virtual keys carry their own budgets and rate limits, and guardrails including PII redaction run before a request reaches a provider.
Portkey is now part of Palo Alto Networks, where the gateway ships as Prisma AIRS AI Gateway. If that ownership change affects a multi-year decision, Portkey alternatives lays out where else that functionality lives.
Model access & deployment: 1,600+ models through a unified API, available as managed cloud, self-hosted from the open-source gateway, or VPC on Enterprise.
Observability: Request logs, latency traces, and token and cost analytics by app, team, or model.
Pricing: Plans are priced on recorded logs rather than tokens, with your provider credentials stored in Portkey. Developer is free at 10k recorded logs per month. Production is $49 per month for 100k logs, with overages at $9 per additional 100k requests.
Limitations: Metering runs on recorded logs rather than requests, so exceeding the allowance stops recording observability data during your busiest periods rather than breaking routing. Developer keeps logs for 3 days and Production for 30.
3. LiteLLM
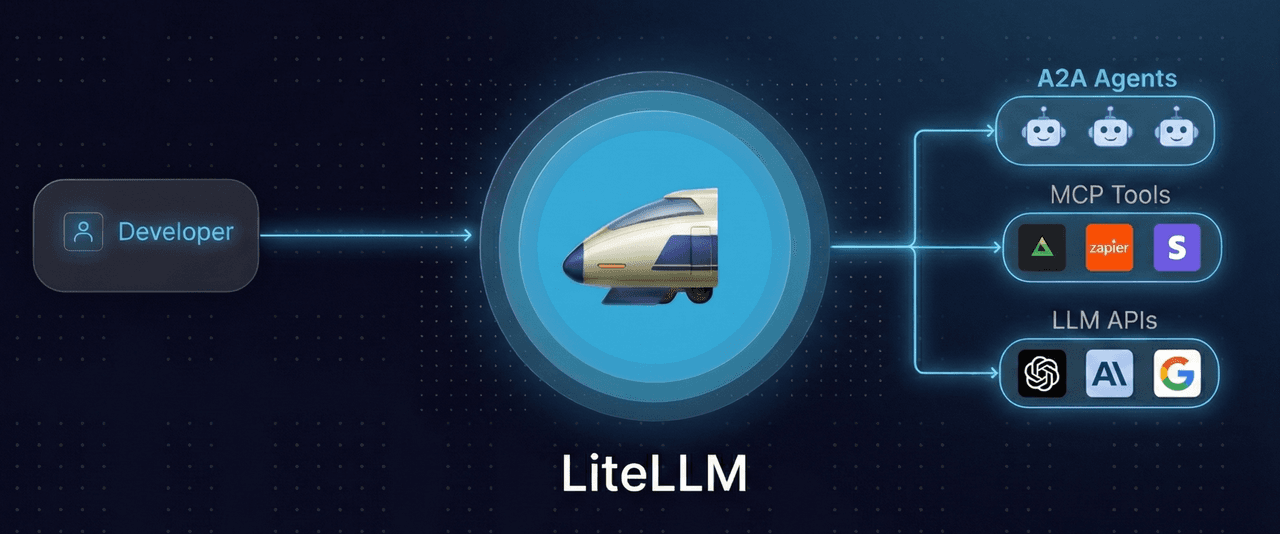
Self-hosting is the direct answer to the third-party hop, and LiteLLM is a common way to do it. The open-source proxy normalizes calls to more than 140 providers into OpenAI format, and because you run it, your keys stay in your infrastructure and requests go straight from your proxy to the provider. Routing, load balancing, virtual keys, and per-key budgets are all in the open-source build.
Two LiteLLM releases on PyPI were compromised in a March 2026 supply-chain incident, and the project now publishes through an isolated CI/CD pipeline, so pin to a current release before deploying. If running the proxy yourself is more than your team wants to take on, LiteLLM alternatives range from managed gateways to other self-hosted builds.
Model access & deployment: 140+ providers and 1,800+ models through an OpenAI-compatible proxy you deploy and operate yourself.
Observability: Request logs, spend tracking per key, team, and model, and logging callbacks to external observability tools.
Pricing: There's no token fee, since requests run on your own provider keys, and the open-source gateway carries no license fee, so the bill is infrastructure plus provider costs. Enterprise is quoted by annual request capacity and deployment architecture rather than published.
Limitations: The proxy needs a database and a cache layer once virtual keys and spend tracking are on, plus someone on call when it sits on the critical path. SSO, JWT auth, and audit logs are Enterprise-only.
4. Cloudflare AI Gateway
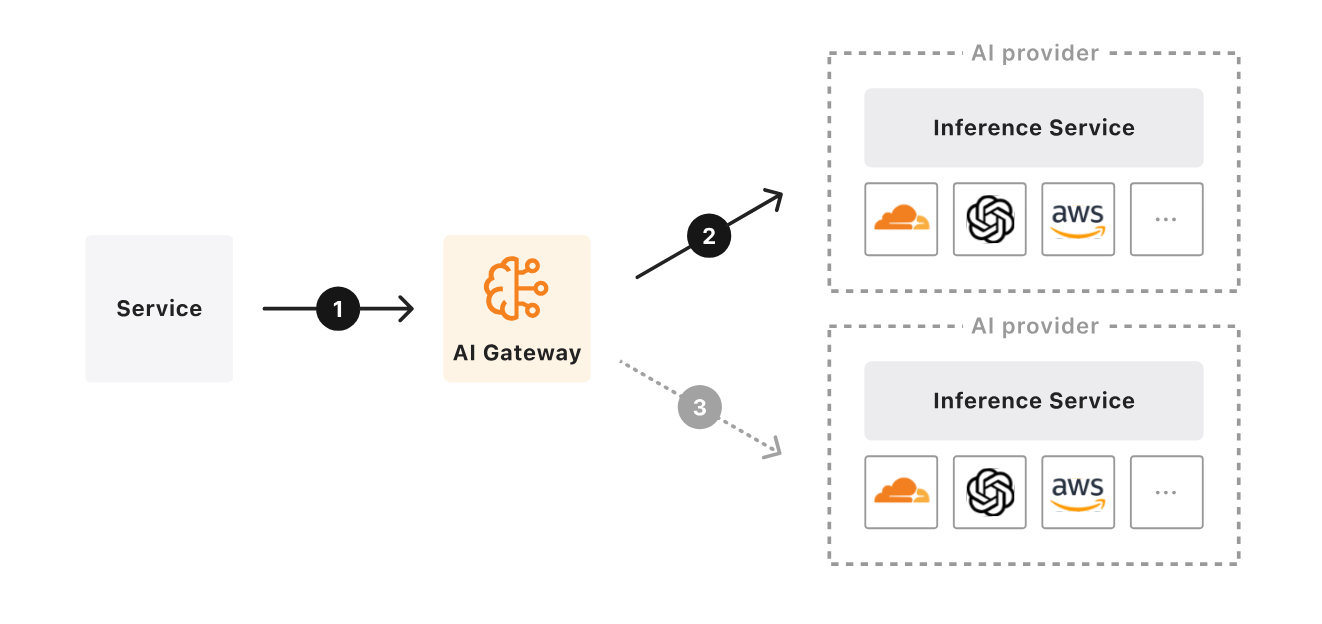
Cloudflare AI Gateway runs on Cloudflare's network between your application and providers like OpenAI, Anthropic, Google Gemini, and Workers AI. Caching, rate limiting, request retries, and model fallbacks are built in, and getting started takes one line of code.
Moving from one managed gateway to another doesn't solve deployment independence, though. There's no self-hosted build, and the product fits best for teams already inside the Cloudflare ecosystem.
Model access & deployment: Major providers plus Workers AI, using your own provider keys or Unified Billing, managed only.
Observability: Analytics, request logs, cost tracking, custom metadata, and an OpenTelemetry integration.
Pricing: With Unified Billing, inference passes through at provider rates with no markup and a 5% fee applies to purchased credits, so $100 of credit costs $105. Core features carry no per-call fee beyond your existing Cloudflare plan, and persistent log storage scales by plan, with Logpush billed separately.
Limitations: Once the persistent log ceiling is reached, new logs stop being saved until old ones are deleted.
5. Bifrost
Bifrost is an open-source gateway from Maxim AI, published under Apache 2.0 and designed for infrastructure you control. It works as a drop-in replacement for an existing client, and the open-source build covers provider fallback, virtual key management, budgeting, an MCP gateway, and built-in observability with OpenTelemetry support.
Clustering, adaptive load balancing, and deployment inside your VPC, on-prem, or air-gapped are Enterprise features, so the open-source build suits a team running a single gateway itself.
Model access & deployment: 1,000+ models across 8+ providers, self-hosted from the open-source build, with VPC, on-prem, and air-gapped deployment on Enterprise.
Observability: Built-in observability plus OpenTelemetry export to the tools you already run.
Pricing: Bifrost runs on your own provider keys, so routing adds nothing to what you pay per token. The open-source gateway is free, and Enterprise is custom priced through Maxim AI, with a 14-day trial available.
Limitations: Quality evaluation lives in Maxim's separate platform rather than the gateway, and Access Profiles, which bundle budget and rate-limit policies, need an Enterprise license.
6. TrueFoundry
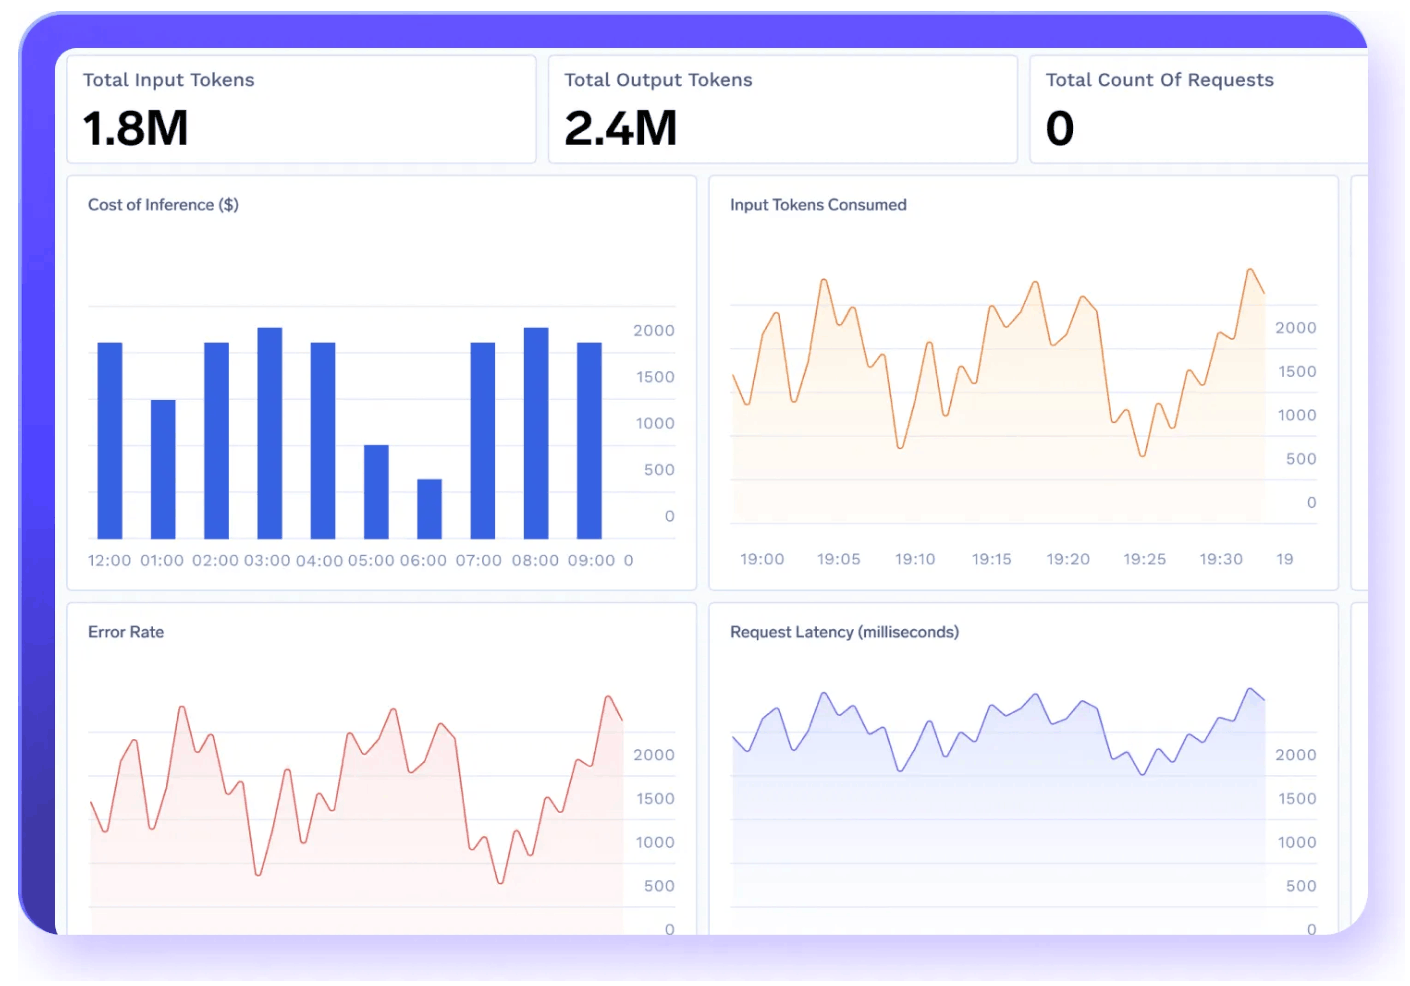
TrueFoundry pairs a gateway with a model deployment platform, so one product routes to hosted provider APIs and to models you run yourself on your own GPUs. Routing covers failover and load balancing, including weighted and latency-based distribution, with budgets and guardrail policies for governance. An MCP gateway handles agent and tool workloads.
The platform is considerably broader than a gateway, which cuts both ways. Teams that want routing and nothing else are buying model deployment and GPU tooling they won't use.
Model access & deployment: 1,600+ models through one API, available hosted, with VPC, on-prem, and air-gapped deployment on Enterprise.
Observability: Request logs with 7-day retention on Developer and 30 days on Pro, plus usage and budget tracking per team.
Pricing: Model-provider charges bill separately, so the gateway fee is per request and per user rather than per token. Developer is free for up to 3 users at 10K gateway requests per user per month. Pro is $25 per user per month with 20K requests per user and $20 per additional 100K, and it adds SSO, custom roles, and up to 10 budget rules. Per-user pricing means the bill tracks team size as well as traffic.
Limitations: Self-hosted deployment, audit logs, and SCIM are gated to Enterprise, and compute for models you host bills through your cloud provider, so the platform fee is never the whole number.
7. LLM API
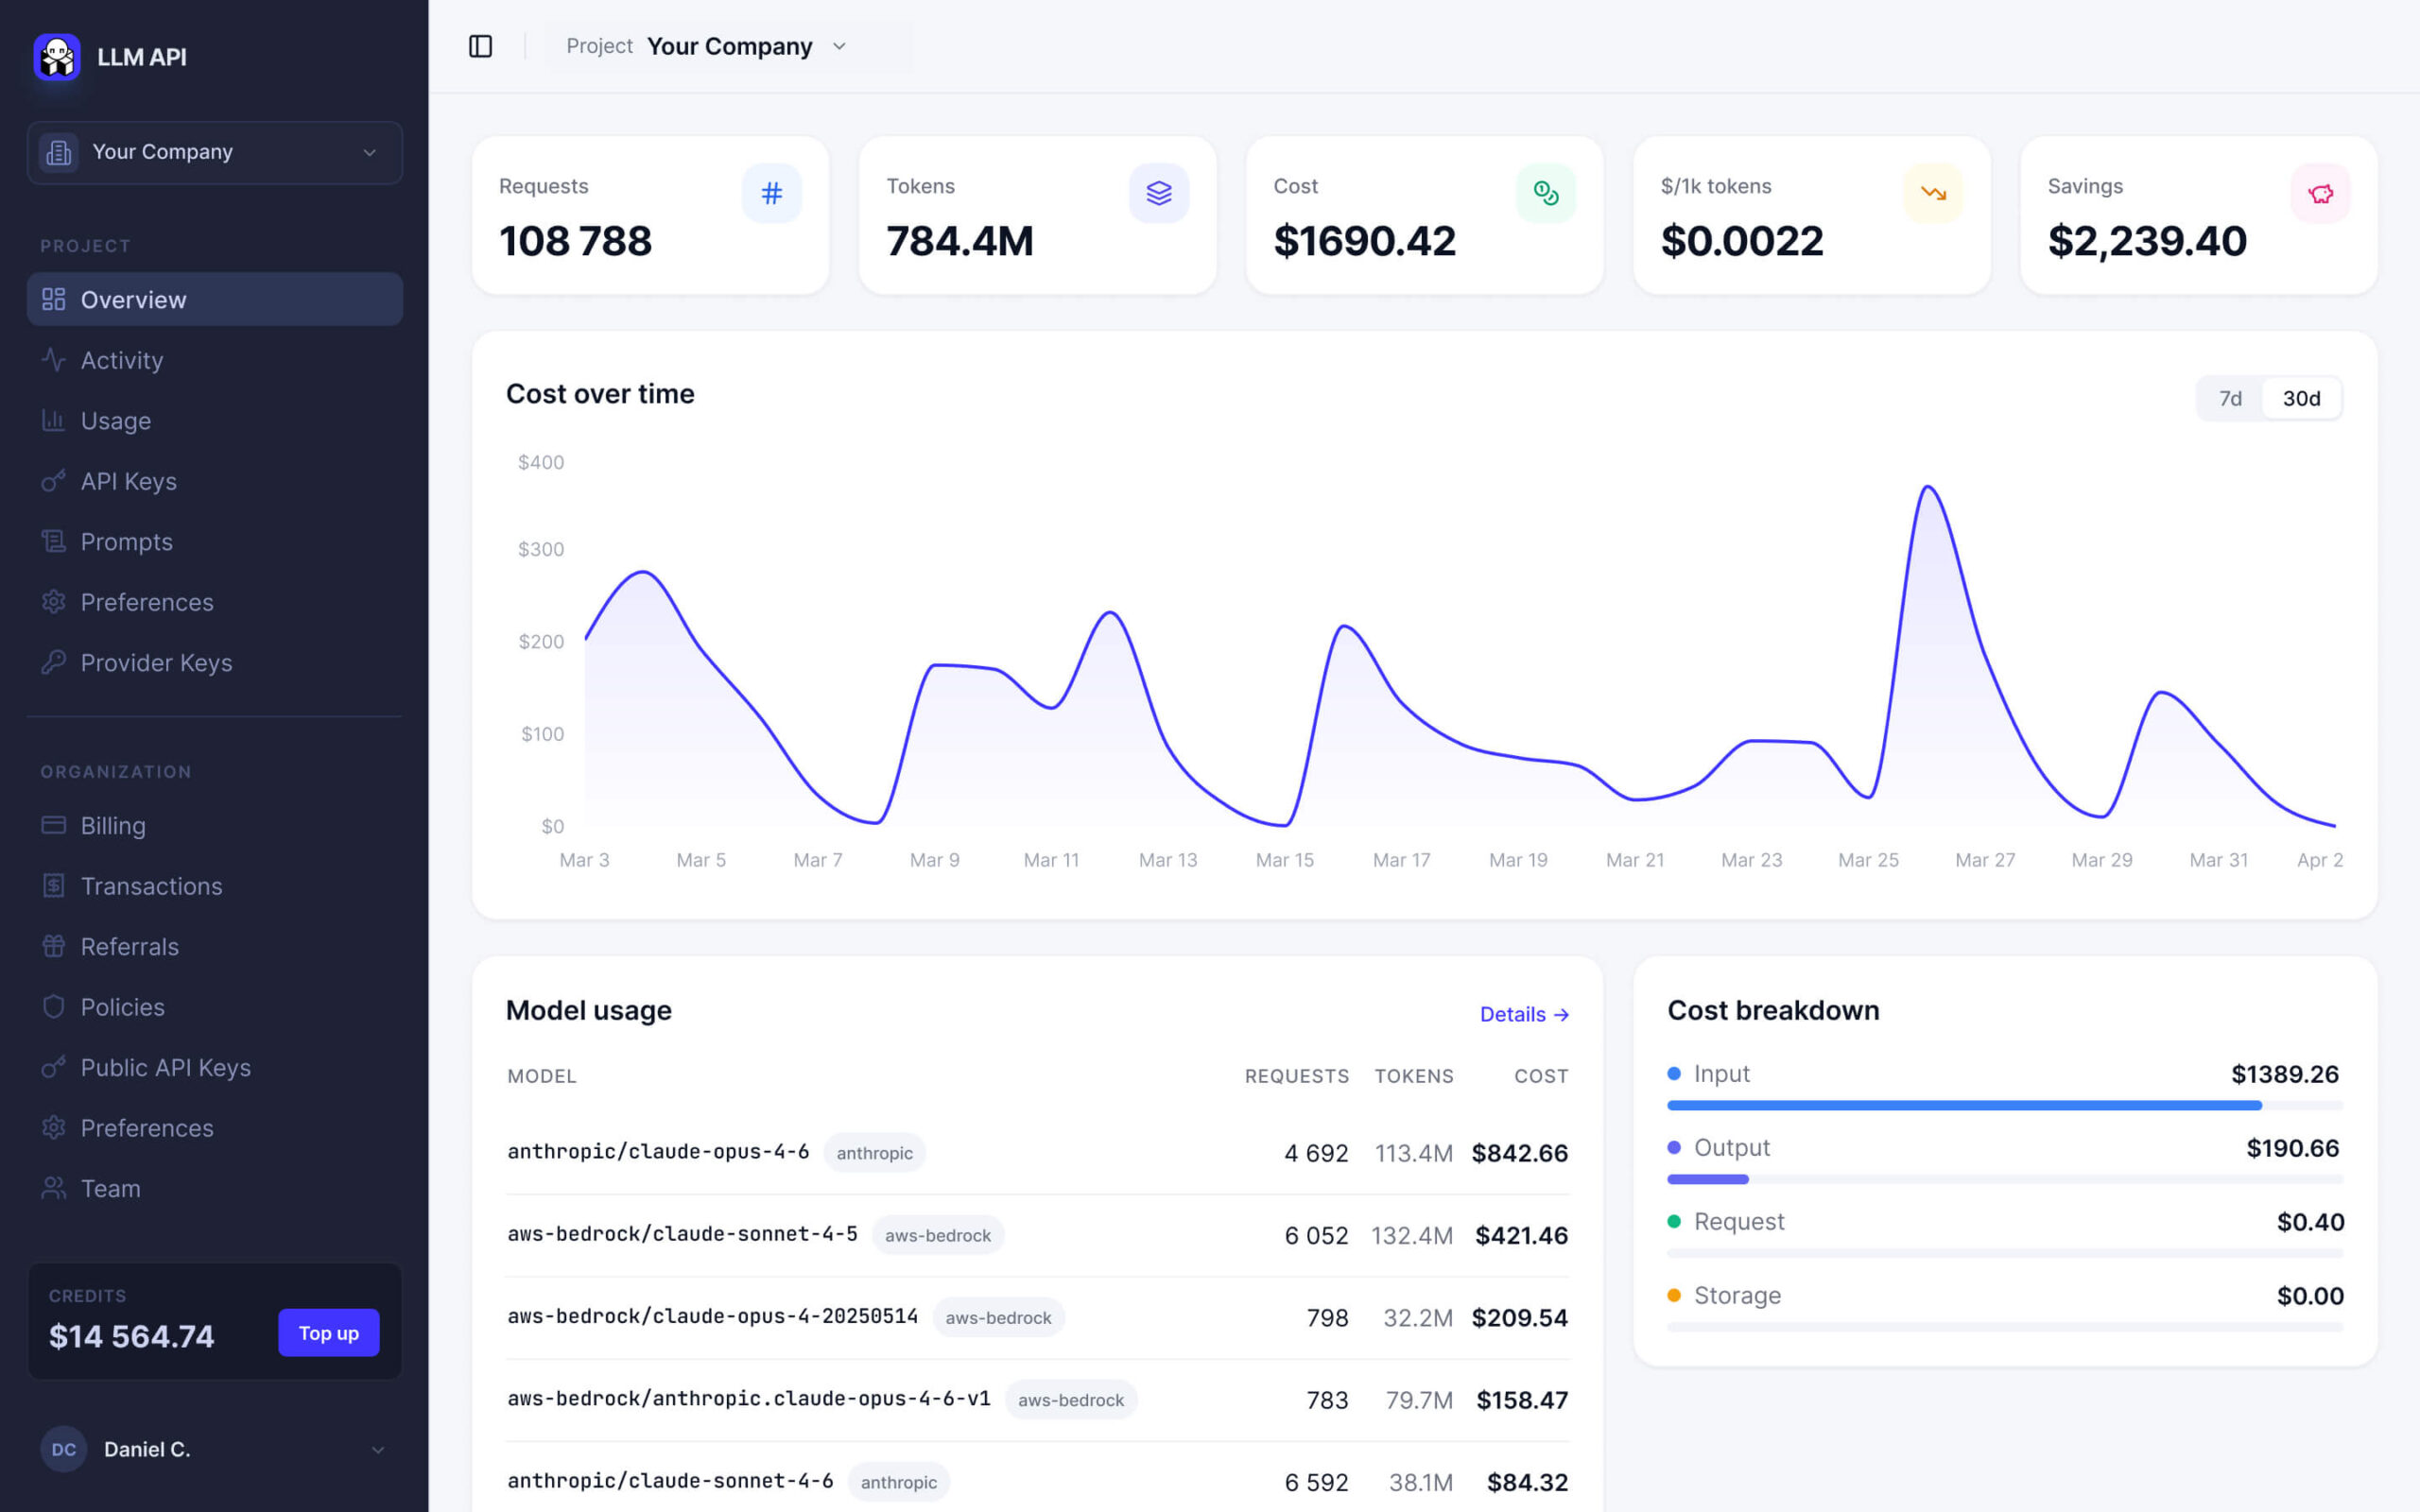
LLM API is a hosted aggregator that puts 400+ models behind one key and one bill, with routing, automatic fallbacks, and caching. Cost governance covers per-team attribution, budget limits, and model policies, and security settings include zero-retention routes and audit logs.
Its pitch centers on cost, with Enterprise contracts trading a usage commitment for a custom discount on inference.
Model access & deployment: 400+ models through one key, with region options and private routing.
Observability: Dashboards and analytics on the self-serve plan.
Pricing: Self-serve is $0 per month, and every request routes at the provider's officially published rate. Discounts are Enterprise-only, set against a usage commitment, with a custom contract and SLA.
Limitations: Cost savings require an Enterprise usage commitment, so self-serve traffic pays the same rate as going direct.
8. Requesty
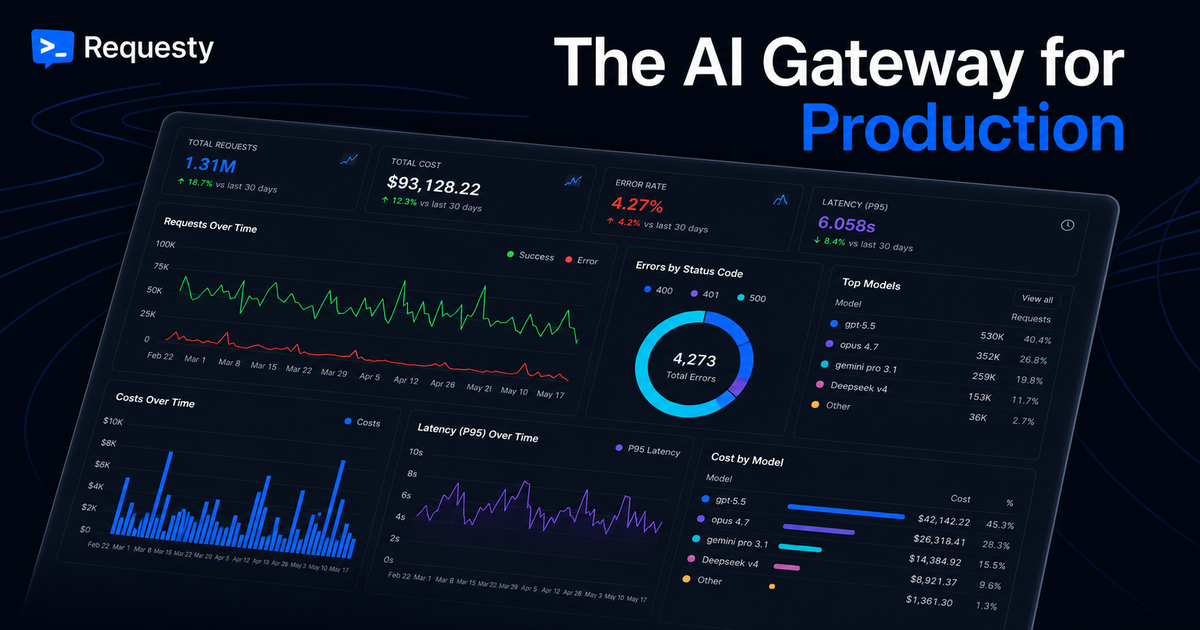
For teams that like how OpenRouter works and want more control around it, Requesty is a hosted router in the same mold: 600+ models behind an OpenAI-compatible base URL. Routing covers automatic failover, load balancing, per-agent fallback chains, and routing to cheaper equivalent models, with spending limits and rate limits settable per user, team, or API key.
Its fee works the same way OpenRouter's does, as a percentage added when you top up credits, so switching changes the rate rather than the structure.
Model access & deployment: 600+ models through an OpenAI-compatible endpoint, hosted, with an EU region in Frankfurt.
Observability: Request logs and analytics on cost, performance, and usage.
Pricing: Requesty adds a 5% service fee to every credit top-up, so $100 of credit costs $105, and bring-your-own-key traffic keeps your existing provider pricing. Free covers 200 requests per day on free models, and Enterprise is custom.
Limitations: SOC 2 Type II is still in progress, and SSO, RBAC with audit logs, and guardrails with PII detection sit on Enterprise.
9. Vercel AI Gateway
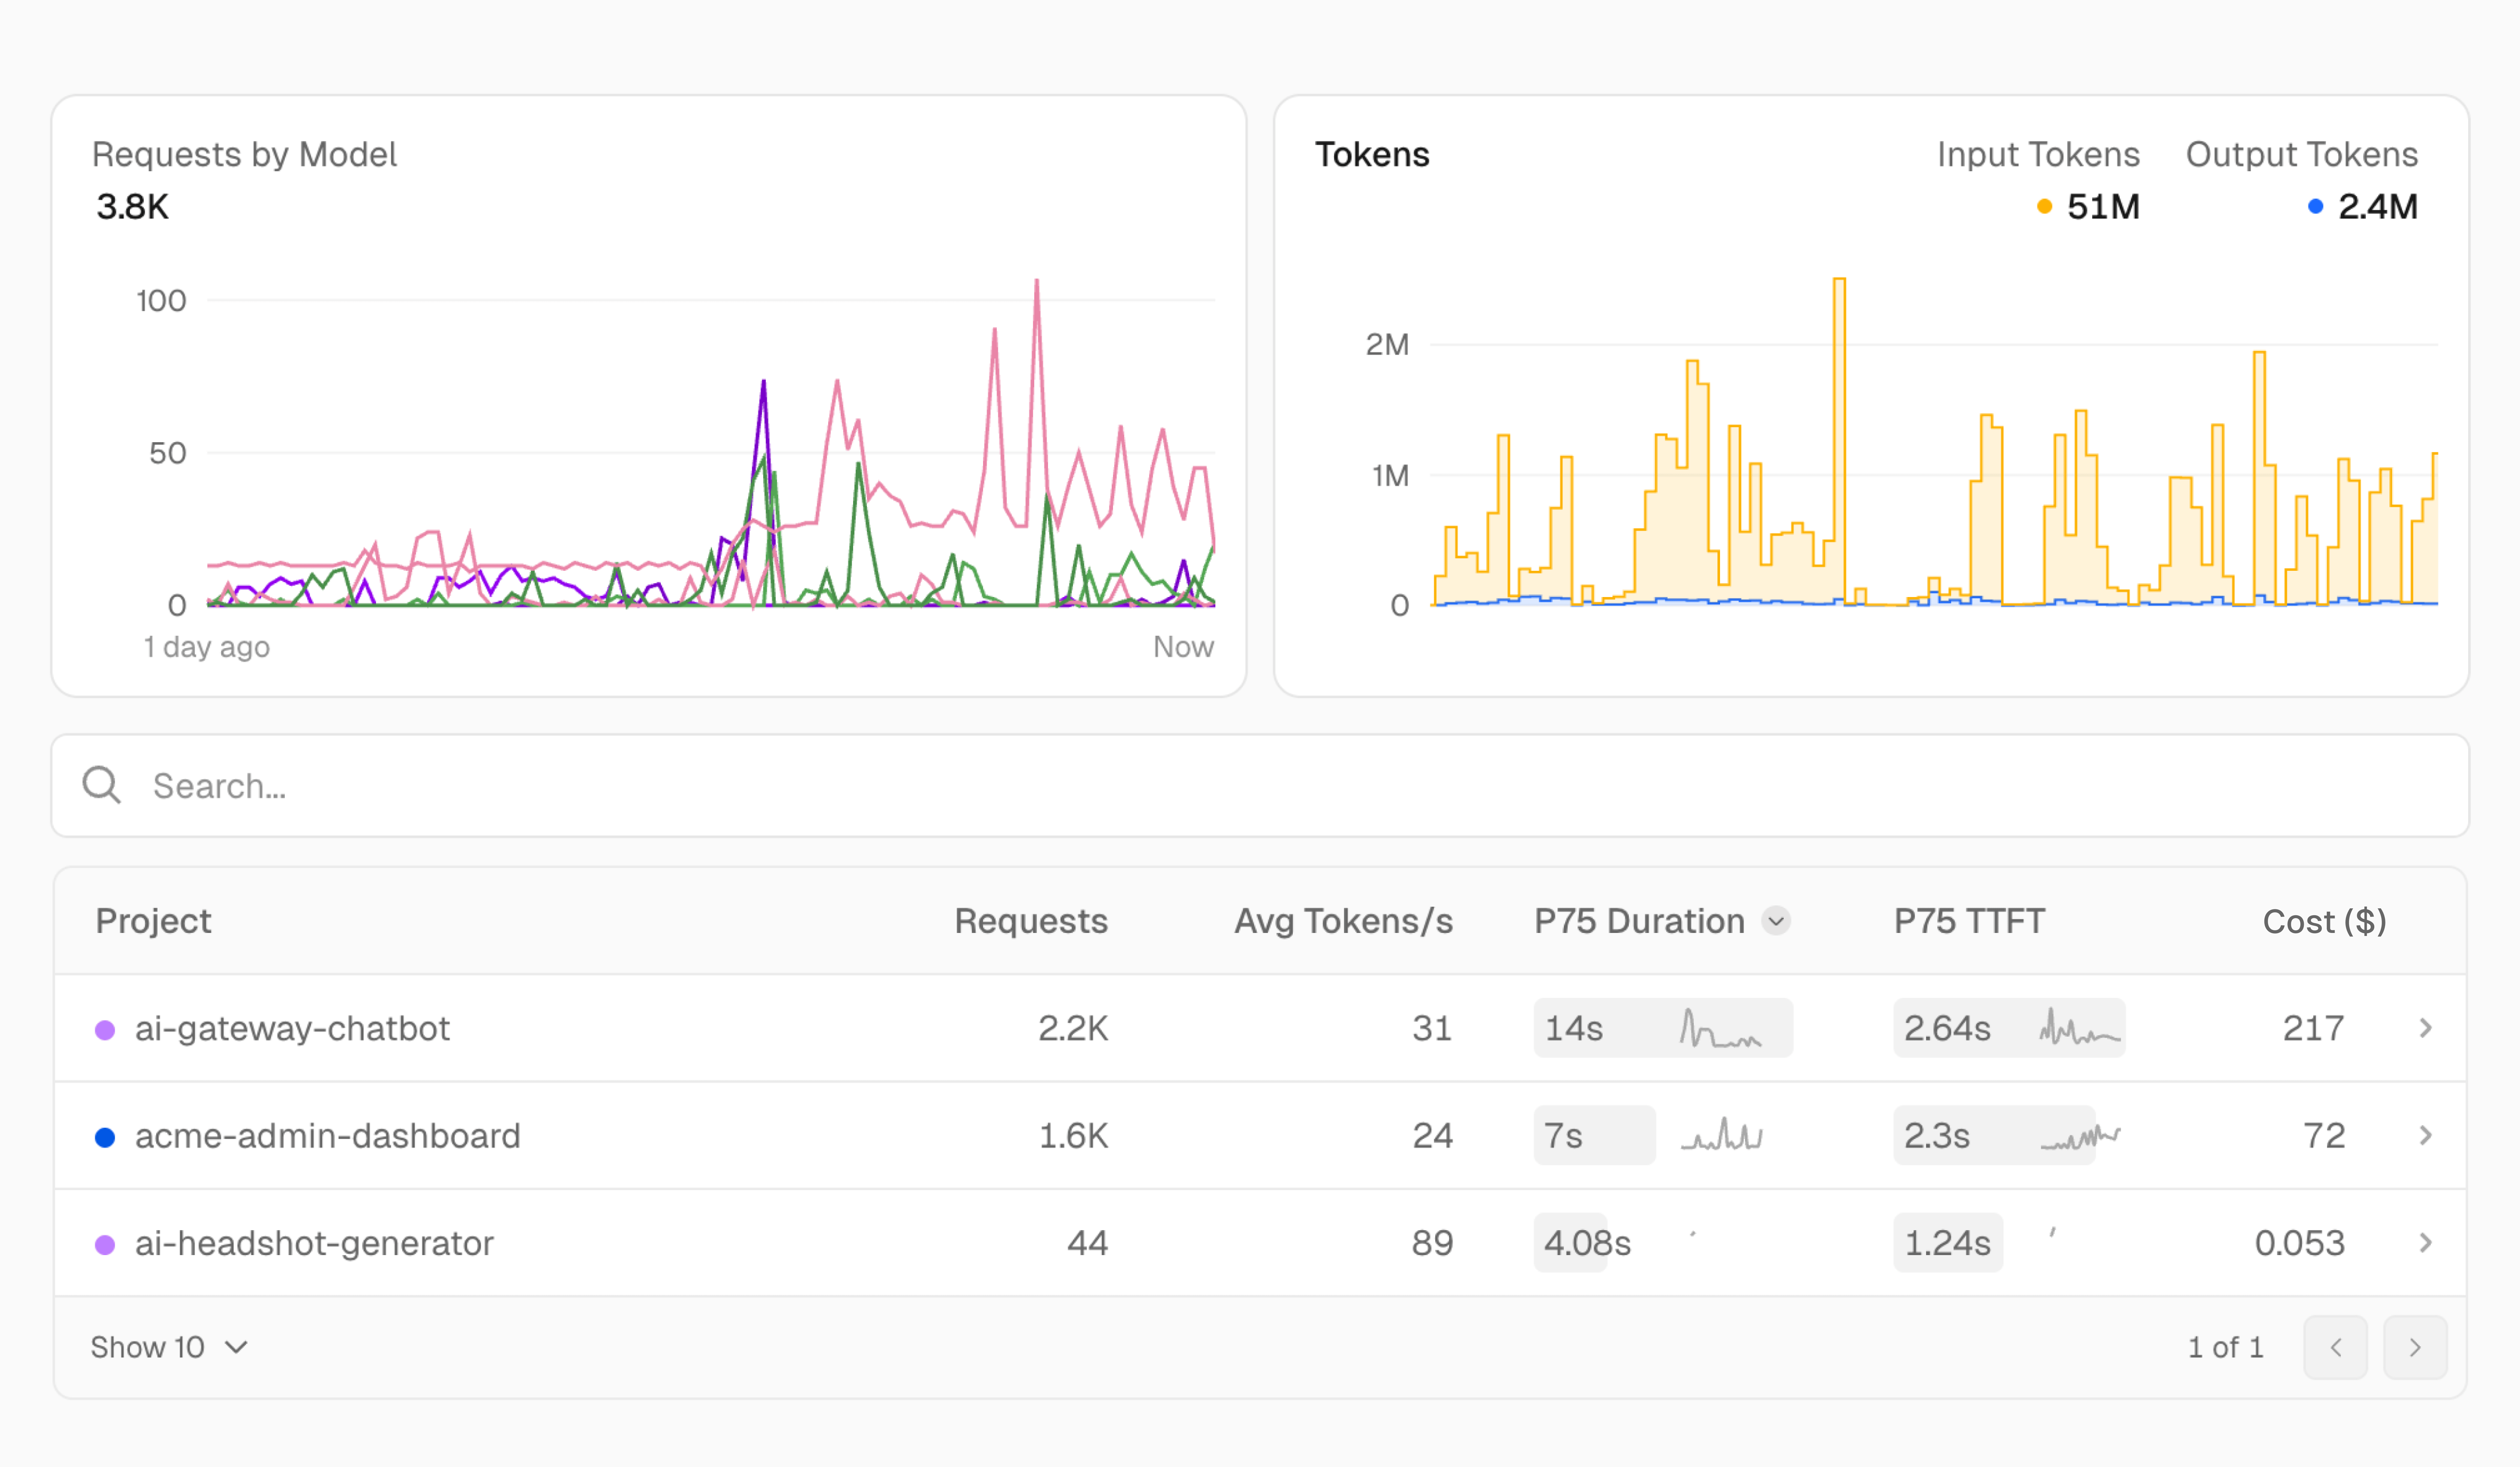
Vercel AI Gateway is built into the Vercel platform and handles automatic retries, managed fallback, load balancing, and spend budgets, with tight integration into the Vercel AI SDK. For a Next.js team adding an AI feature, the setup cost is close to zero.
The coupling is the catch. It's a managed service operated by Vercel with no self-hosted build and no VPC option, so once backend services live on AWS or your own hardware, the gateway is the component that can't follow, and at that point Vercel AI Gateway alternatives are worth a look.
Model access & deployment: Hundreds of models across providers including OpenAI, Anthropic, Google, Mistral, and xAI, managed only.
Observability: Request logs with per-request routing detail, usage, time-to-first-token, token, and spend metrics by team, project, and API key, plus Trace Drains on Pro and Enterprise that forward an OpenTelemetry trace of every request to your own tool.
Pricing: Tokens bill at provider list price with no markup or platform fee, including on bring-your-own-key, though you cover any payment processing fees on credit purchases unless you pay by Enterprise invoice. Each team gets $5 in monthly credits until it buys credits. Add-ons bill separately: Custom Reporting at $0.075 per 1,000 writes and $5 per 1,000 queries, team-wide provider allowlisting or zero data retention at $0.10 per 1,000 requests, and Trace Drains at $0.05 per 1,000 traces plus $0.50 per GB.
Limitations: BYOK requires purchased credits, and a request that fails on your key retries on Vercel's credentials and bills against your balance.
10. Helicone
Integration with Helicone is a base URL change, after which request logs, token counts, cost tracking, and latency metrics appear on a dashboard. That proxy setup made Helicone a quick way to get visibility on LLM spend, and it still works the same way today.
Mintlify acquired Helicone in March 2026, and the product is now in maintenance mode, with security updates, bug fixes, and new models still shipping. Putting a maintenance-mode product on the critical path is hard to justify for a new deployment, and Mintlify has said it will help existing customers migrate, so Helicone alternatives are the more likely destination.
Model access & deployment: Provider-agnostic through a proxy, self-hostable from the open-source build or run as managed cloud.
Observability: Request logs, cost tracking, and latency metrics for every call through the proxy.
Pricing: Gateway credits bill at provider prices with 0% markup, plus standard payment processing on purchases. Hobby is free with 10,000 requests, Pro is $79 per month, and Team is $799 per month, with usage above the included requests billed on top.
Limitations: Proxy instrumentation is request-shaped, so it sees the calls passing through it rather than the reasoning and tool steps between them.
11. Kong AI Gateway
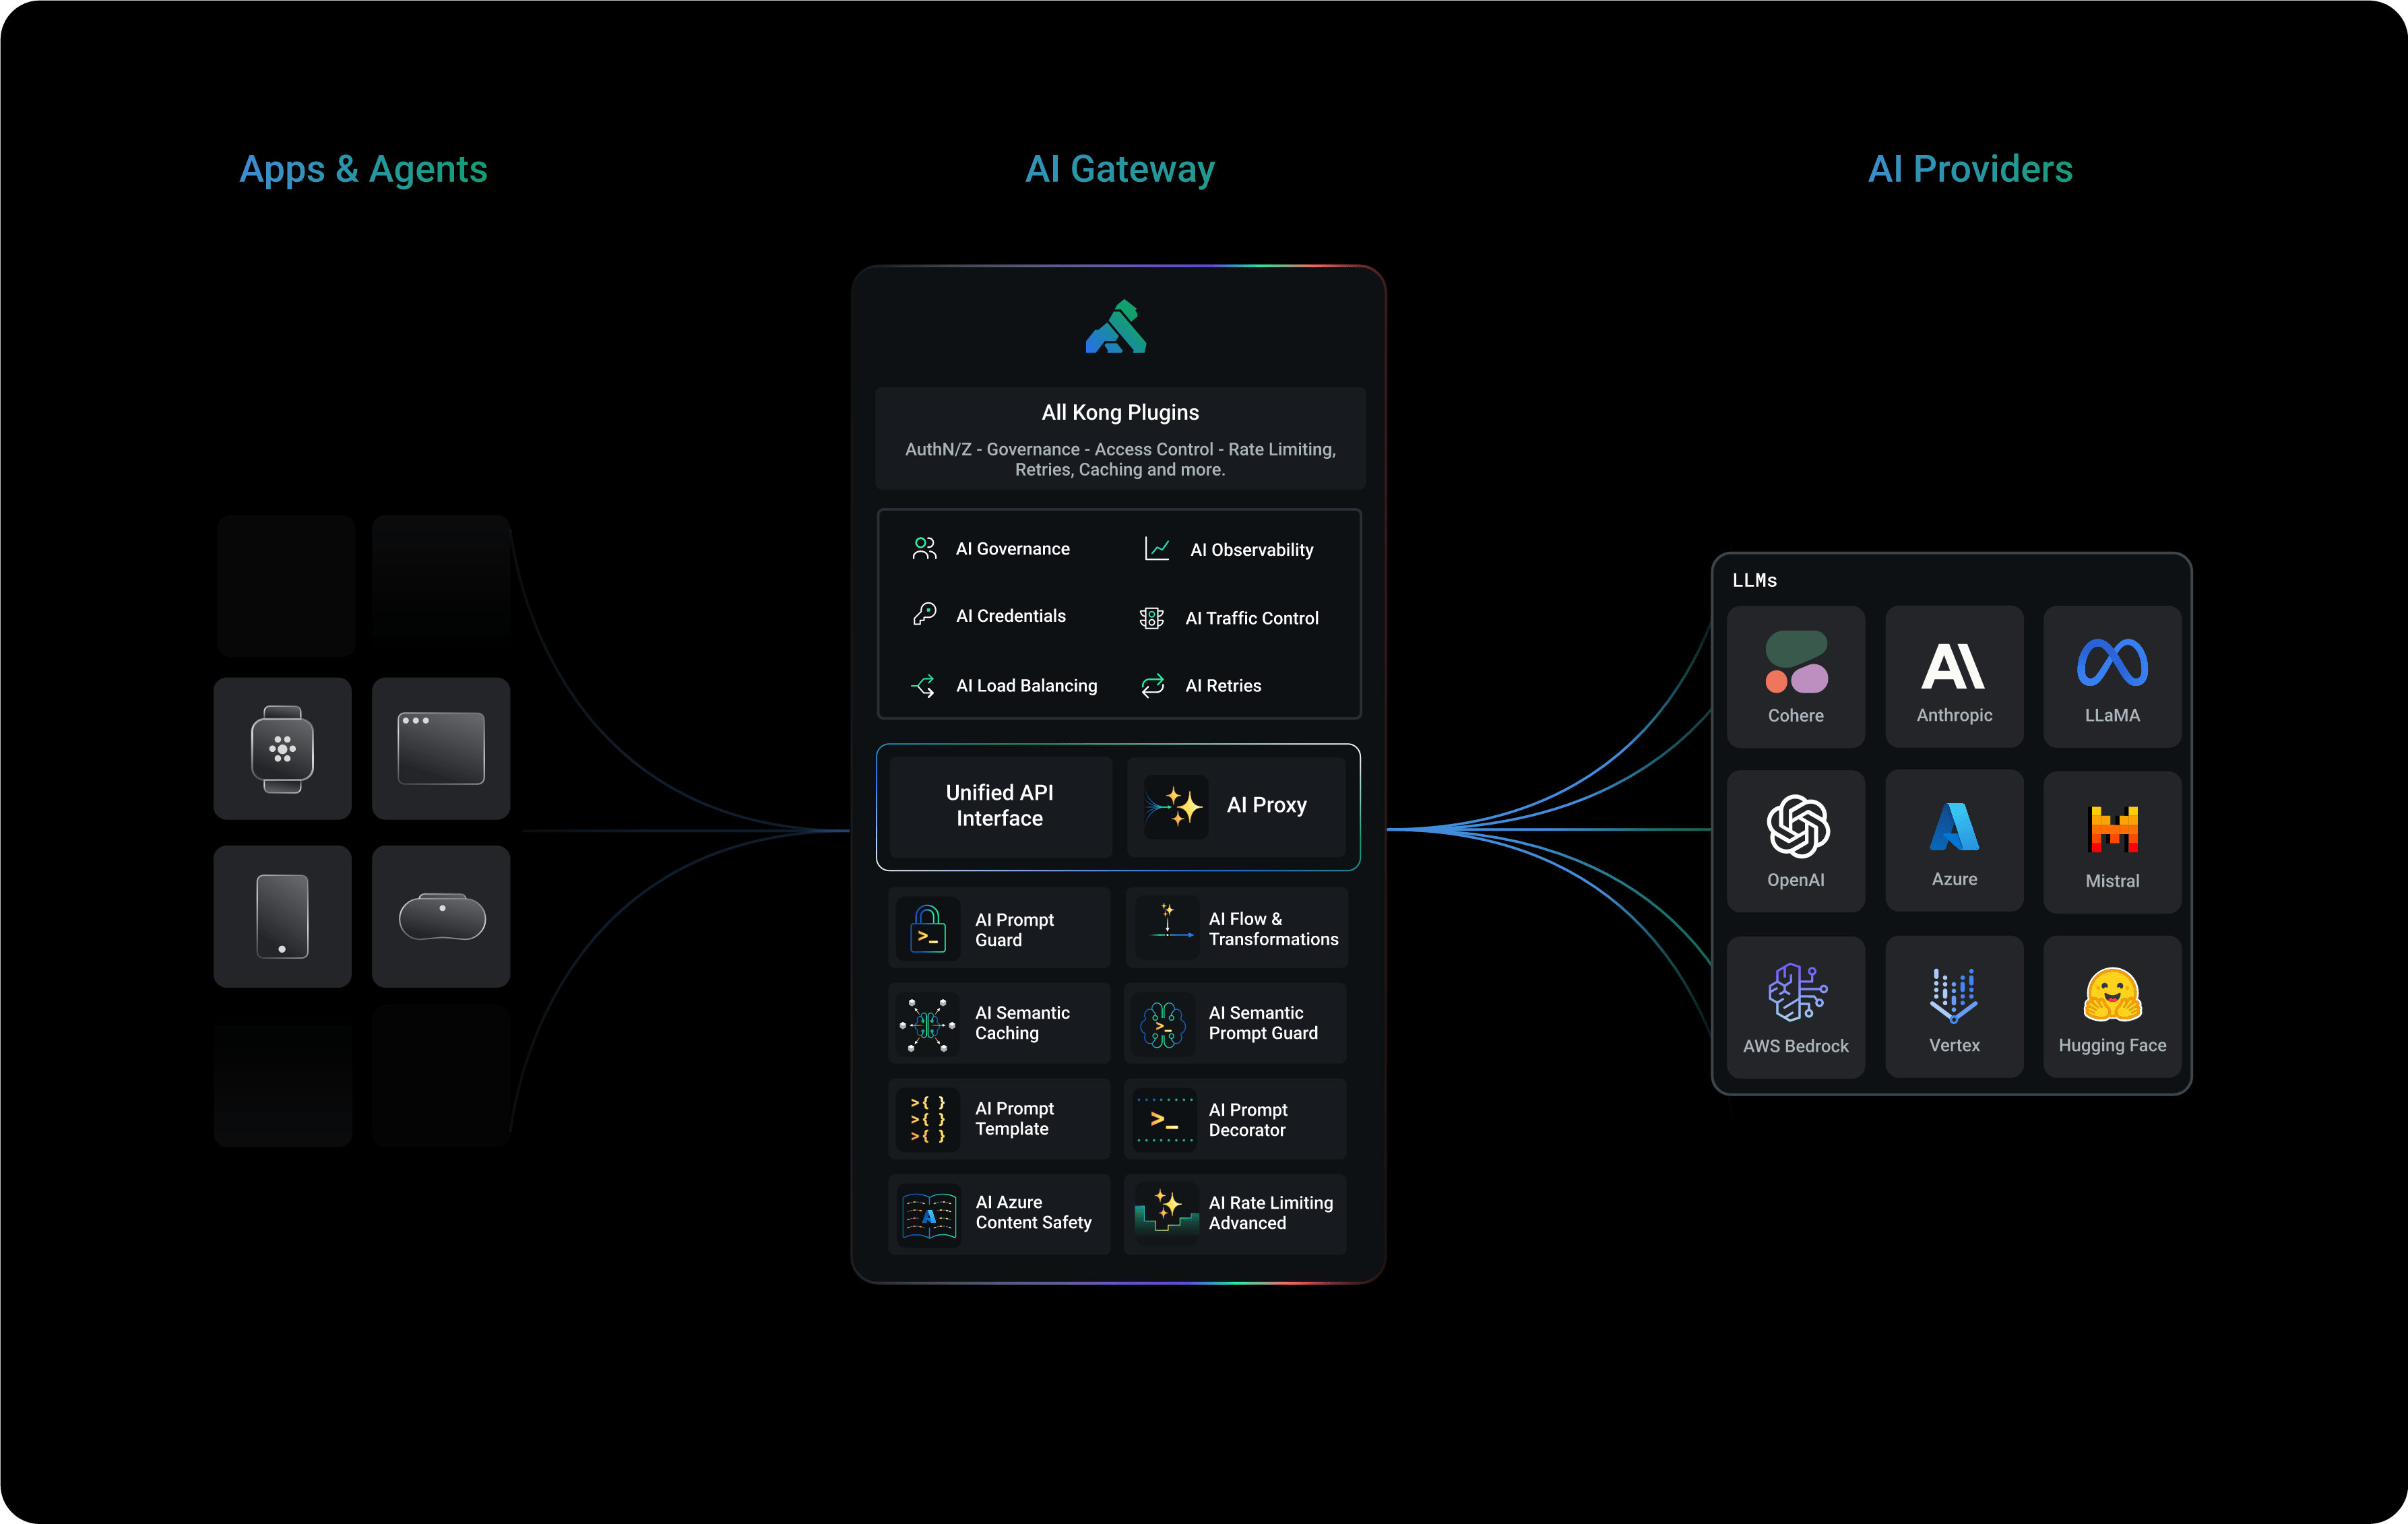
Kong added AI routing to its existing API gateway rather than building a separate product, so model traffic runs through the same plugin architecture, policies, and control plane as the rest of your APIs. AI Proxy plugins normalize provider APIs, and the surrounding platform brings authentication, rate limiting, and audit that predate anyone's LLM workload. Semantic routing can send a request to a cheaper model based on the content of the prompt.
For an organization already running Kong, this is governance you don't have to build twice, and for teams that don't run Kong, Kong AI Gateway alternatives cover gateways built for model traffic first.
Model access & deployment: Provider-agnostic through AI Proxy plugins, deployable as serverless, hybrid, or dedicated cloud, with fully self-hosted on enterprise terms.
Observability: Request-shaped metrics and logs from the API gateway layer.
Pricing: The AI-specific charge is per model rather than per token, with each unique model routed through AI plugins adding $100 per month on Plus. A control plane costs $25 per month serverless, $200 hybrid, or $500 as a Dedicated Cloud Gateway, so a multi-model strategy adds line items on top of the base.
Limitations: The AI capabilities sit on a general-purpose HTTP proxy, so the primitives are request-shaped rather than token-shaped.
12. Merge
Merge Gateway inverts OpenRouter's fee structure by charging on usage rather than on top-ups. Routing, fallback, spend policies, and logging sit behind one endpoint, with budgets settable by project, team, or customer tier. You can also define routing logic yourself by weighting the benchmarks you care about, including your own scores, and every routing decision comes back with a plain-language explanation.
Spend policies scoped per customer tier are directly useful for anyone shipping AI features to their own customers.
Model access & deployment: OpenAI, Anthropic, Google, Grok, Mistral, and Cohere through a managed endpoint that accepts existing OpenAI SDK code, with VPC or on-prem deployment on Enterprise.
Observability: Logs of every routing decision, cost, and outcome in one place.
Pricing: Pro is LLM cost plus a 5% markup, and bring-your-own-key usage bills at $0.05 per million tokens. Pro includes $10 in monthly credits that expire at month end and don't roll over, and Enterprise is custom.
Limitations: The provider list covers major vendors rather than a long tail, and keeping traffic in your own network requires an Enterprise contract.
How to Choose Between OpenRouter Competitors
Once you've narrowed the list, test each candidate against the requests you actually send:
- OpenAI SDK compatibility - Run a production-shaped request against the new endpoint and note every change it needs. A base URL and key swap keeps the migration small, while a custom SDK or response format turns it into a refactor.
- Model breadth vs. the models you actually run - Start from the models you call through OpenRouter today and the ones you plan to test next. A catalog in the hundreds matters less than whether those specific models are supported and current.
- Fallback and reliability - Check whether fallback is ordered across models or only across providers for the same model, and whether retries live in the gateway or in your code. Routing logic varies more than catalogs do, and LLM routers differ on whether they pick a model by rule, by cost, or by task.
- Cost attribution and spend controls - Send the customer and feature metadata you use in production and check whether reports can group spend by it. A hard cap per key or per customer stops a leaked key, while a soft warning doesn't. Also check what the gateway charges for routing itself, because the models differ: a fee added when you top up credits (OpenRouter, Requesty, Cloudflare's Unified Billing), a markup on usage (Merge), list-price tokens with only payment processing on credit purchases (Vercel, Helicone), or no token fee at all when you bring your own keys and pay for the platform instead.
- Tracing and evals - Follow one failed multi-step request through every model and tool call. Gateways range from a single log line per call to full traces with eval scores attached, and the difference only shows up when you're debugging an agent.
- Deployment and compliance - Data residency requirements can usually be met by running the gateway inside your own network, or by using a hosted gateway with the certifications and data controls your review asks for, such as SOC 2, GDPR, HIPAA, PII masking, and retention settings.
No tool covers all of these 100% equally, so weight them by whatever is making you leave OpenRouter.
How to Switch from OpenRouter
An OpenAI-compatible client keeps the code change small, but a production migration still touches model names, routing rules, and credentials. Working through it in this order keeps traffic safe while you switch:
- Point your client at the new endpoint - Keep the OpenAI SDK, swap OpenRouter's base URL for the new gateway's, and load the new key. Test with a model ID the new gateway documents, since OpenRouter's
provider/modelslugs won't resolve until you map them. - Map model IDs - Translate every OpenRouter slug, including
:freeand other variants, to the new gateway's model names in config files, environment variables, and hardcoded references. Confirm each model still supports the tool calls, structured outputs, and context length you rely on. - Recreate fallback and routing rules - Rebuild provider order and model fallbacks in the new gateway, then force a failure to check that the chain fires in the order you expect.
- Move keys and spend limits - OpenRouter credits and BYOK settings don't transfer. Add provider keys or buy credits on the new platform, and set spend caps per key or per customer before traffic moves.
- Validate before shifting traffic - Replay a representative set of production requests through both routes, compare errors, latency, cost, and output quality, and then move traffic in stages.
On Respan, the last two steps happen in the same place: spend limits sit on the key, and replayed requests land as traces you can score with the same evaluators you'll run in production.
FAQs
What is the best OpenRouter alternative?
Respan, if the reason you're leaving is visibility into what your requests and agents actually did. It replaces the router with one OpenAI-compatible endpoint to 1,000+ models and keeps traces, eval scores, and spend caps against the same requests. If traffic has to stay inside your own network, LiteLLM and Bifrost are self-hosted, and if you already run Kong or Cloudflare, their gateways extend infrastructure you have.
Is there a free OpenRouter alternative?
Yes. Respan's free tier covers 100k logs, 412 requests per minute through the gateway, and 7-day retention, with routing, tracing, and evals included. LiteLLM and Bifrost are free to self-host, which moves the cost to infrastructure and on-call time, and Requesty's and Merge's free tiers cover free models only.
What services are similar to OpenRouter?
Respan works the same way at the endpoint, with one OpenAI-compatible URL in front of 1,000+ models, and adds tracing and evals behind it. Requesty, LLM API, and Merge are also hosted routers with one endpoint and one bill. Vercel AI Gateway and Cloudflare AI Gateway follow the same pattern but fit best inside their own platforms.
Is there a cheaper alternative to OpenRouter?
Yes, if the fee on OpenRouter credit purchases is what you're trying to avoid. With Respan, you can bring your own provider keys or use Respan credits with no processing fee, and plans are priced on logs rather than a percentage of spend. Vercel AI Gateway and Helicone bill tokens at list price with only payment processing on credit purchases, while Requesty adds 5% at top-up against OpenRouter's 5.5% and Merge adds 5% on usage. Self-hosting LiteLLM or Bifrost removes the gateway fee entirely, in exchange for running the gateway yourself.
Is LiteLLM similar to OpenRouter?
Yes. Both expose a unified OpenAI-compatible API across providers, and the split is hosted versus self-hosted. OpenRouter is a hosted router with a 5.5% fee on credit purchases and traffic that transits its infrastructure. LiteLLM is an open-source proxy you deploy, with no per-request fee and keys that stay in your network, in exchange for running a database, a cache layer, and an on-call rotation for a component on the critical path. Respan sits between the two: hosted like OpenRouter, with tracing, evals, and per-key spend caps on every request.